KAFKA STREAMS ARCHITECTURE

Kafka Streams simplifies application development by building on the Kafka producer and consumer libraries and leveraging the native capabilities of Kafka to offer data parallelism, distributed coordination, fault tolerance, and operational simplicity. In this section, we describe how Kafka Streams works underneath the covers.

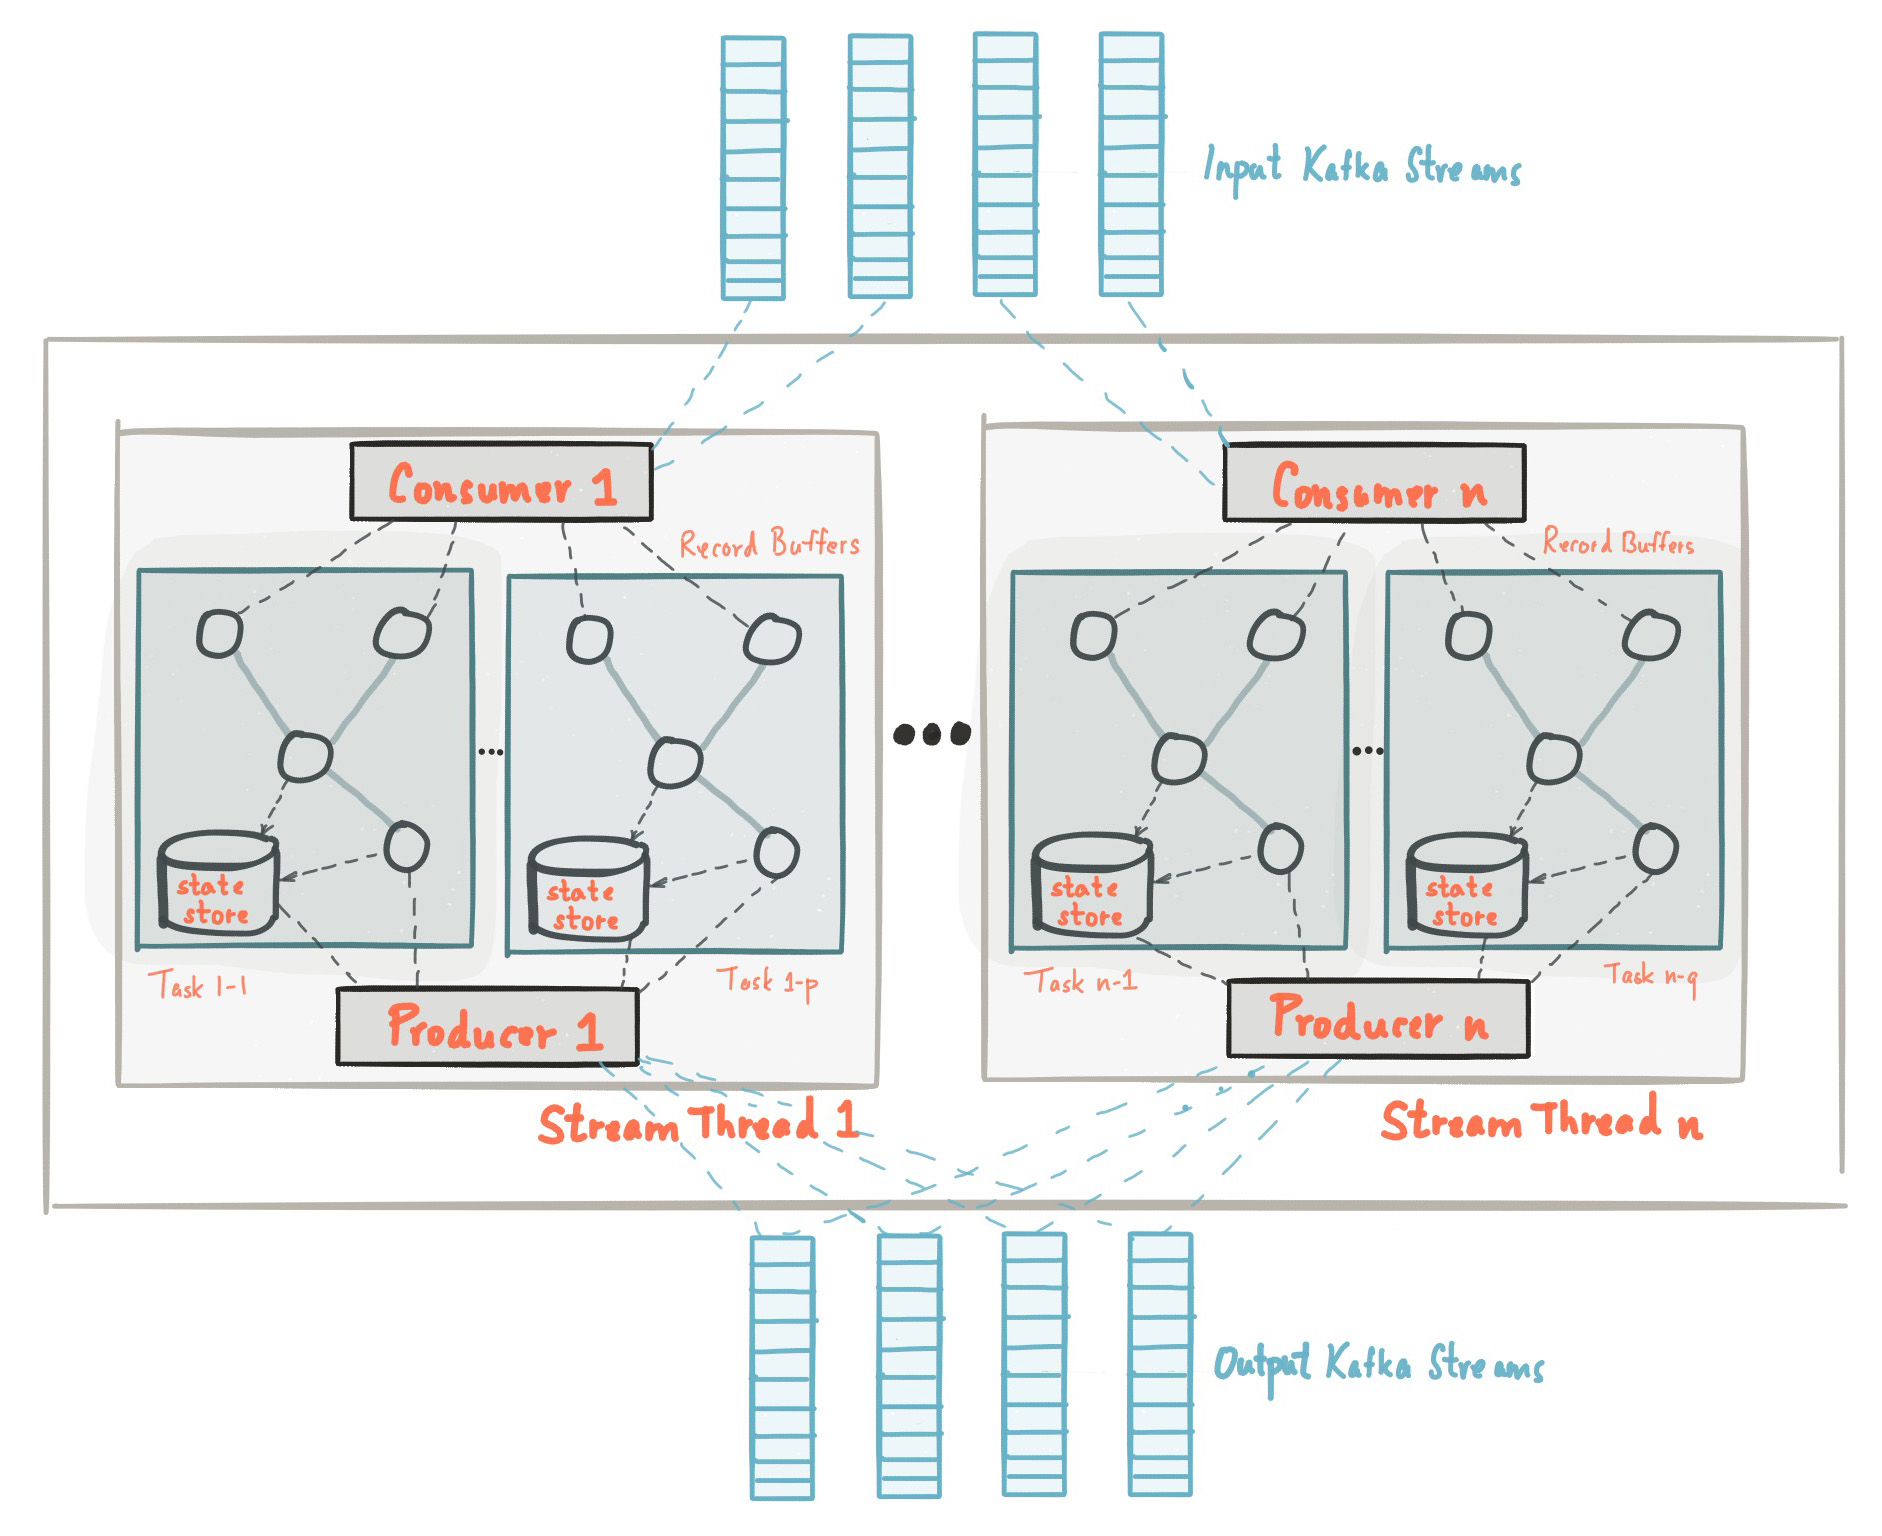
The picture below shows the anatomy of an application that uses the Kafka Streams library. Let's walk through some details.

img

Stream Partitions and Tasks

The messaging layer of Kafka partitions data for storing and transporting it. Kafka Streams partitions data for processing it. In both cases, this partitioning is what enables data locality, elasticity, scalability, high performance, and fault tolerance. Kafka Streams uses the concepts of partitions and tasks as logical units of its parallelism model based on Kafka topic partitions. There are close links between Kafka Streams and Kafka in the context of parallelism:

  • Each stream partition is a totally ordered sequence of data records and maps to a Kafka topic partition.
  • A data record in the stream maps to a Kafka message from that topic.
  • The keys of data records determine the partitioning of data in both Kafka and Kafka Streams, i.e., how data is routed to specific partitions within topics.

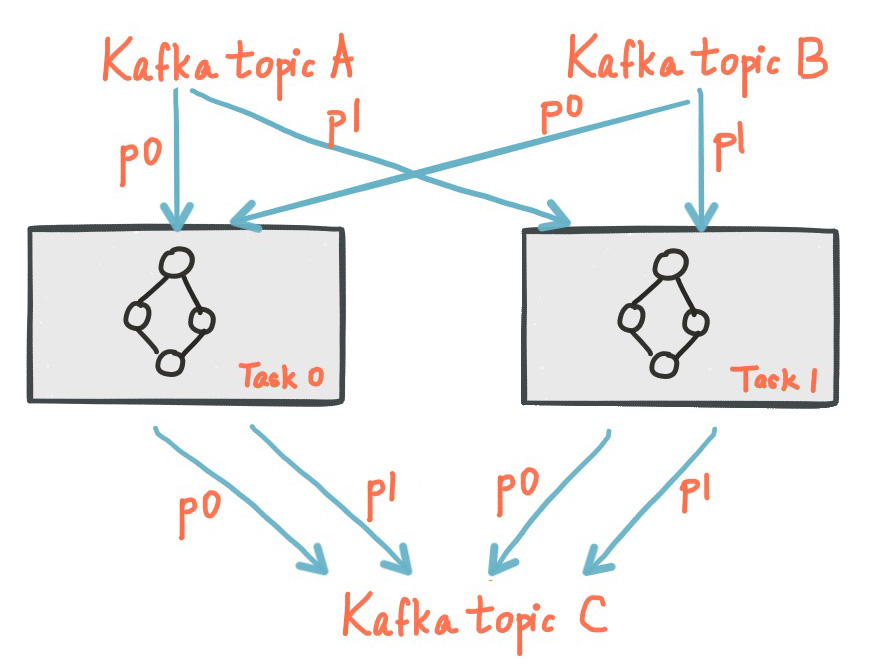
An application's processor topology is scaled by breaking it into multiple tasks. More specifically, Kafka Streams creates a fixed number of tasks based on the input stream partitions for the application, with each task assigned a list of partitions from the input streams (i.e., Kafka topics). The assignment of partitions to tasks never changes so that each task is a fixed unit of parallelism of the application. Tasks can then instantiate their own processor topology based on the assigned partitions; they also maintain a buffer for each of its assigned partitions and process messages one-at-a-time from these record buffers. As a result stream tasks can be processed independently and in parallel without manual intervention.

Slightly simplified, the maximum parallelism at which your application may run is bounded by the maximum number of stream tasks, which itself is determined by maximum number of partitions of the input topic(s) the application is reading from. For example, if your input topic has 5 partitions, then you can run up to 5 applications instances. These instances will collaboratively process the topic’s data. If you run a larger number of app instances than partitions of the input topic, the “excess” app instances will launch but remain idle; however, if one of the busy instances goes down, one of the idle instances will resume the former’s work.

It is important to understand that Kafka Streams is not a resource manager, but a library that "runs" anywhere its stream processing application runs. Multiple instances of the application are executed either on the same machine, or spread across multiple machines and tasks can be distributed automatically by the library to those running application instances. The assignment of partitions to tasks never changes; if an application instance fails, all its assigned tasks will be automatically restarted on other instances and continue to consume from the same stream partitions.

NOTE: Topic partitions are assigned to tasks, and tasks are assigned to all threads over all instances, in a best-effort attempt to trade off load-balancing and stickiness of stateful tasks. For this assignment, Kafka Streams uses the StreamsPartitionAssignor class and doesn't let you change to a different assignor. If you try to use a different assignor, Kafka Streams ignores it.

The following diagram shows two tasks each assigned with one partition of the input streams.

img

Threading Model

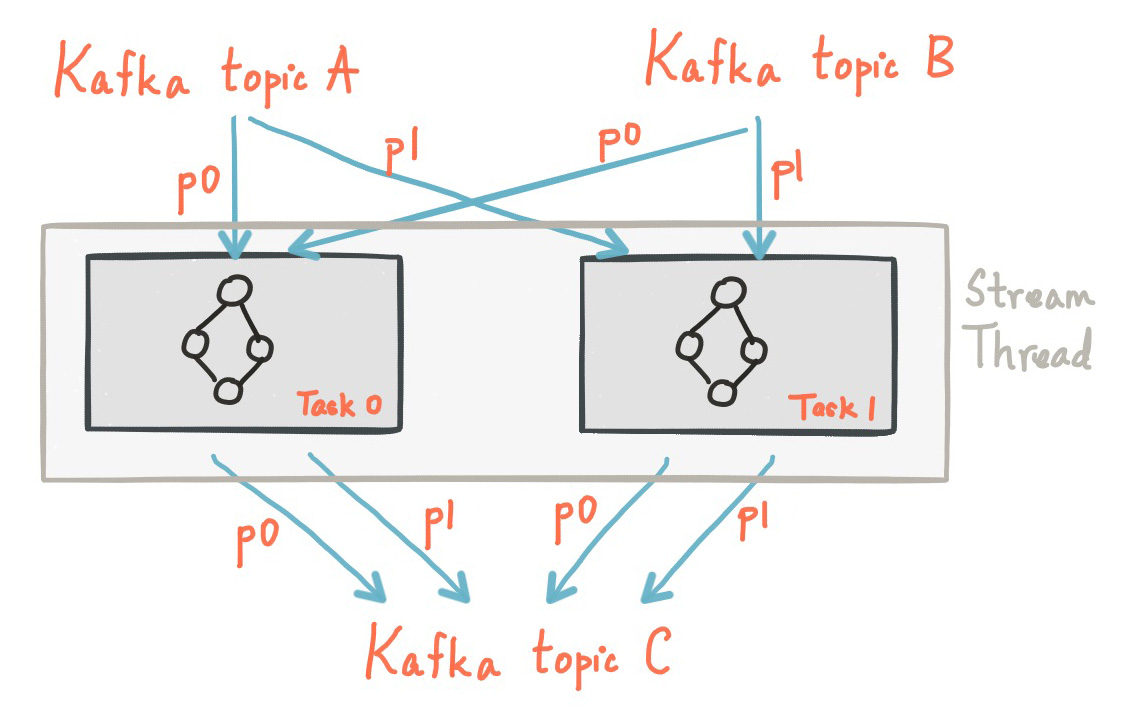
Kafka Streams allows the user to configure the number of threads that the library can use to parallelize processing within an application instance. Each thread can execute one or more tasks with their processor topologies independently. For example, the following diagram shows one stream thread running two stream tasks.

img

Starting more stream threads or more instances of the application merely amounts to replicating the topology and having it process a different subset of Kafka partitions, effectively parallelizing processing. It is worth noting that there is no shared state amongst the threads, so no inter-thread coordination is necessary. This makes it very simple to run topologies in parallel across the application instances and threads. The assignment of Kafka topic partitions amongst the various stream threads is transparently handled by Kafka Streams leveraging Kafka's coordination functionality.

As we described above, scaling your stream processing application with Kafka Streams is easy: you merely need to start additional instances of your application, and Kafka Streams takes care of distributing partitions amongst tasks that run in the application instances. You can start as many threads of the application as there are input Kafka topic partitions so that, across all running instances of an application, every thread (or rather, the tasks it runs) has at least one input partition to process.

As of Kafka 2.8 you can scale stream threads much in the same way you can scale your Kafka Stream clients. Simply add or remove stream threads and Kafka Streams will take care of redistributing the partitions. You may also add threads to replace stream threads that have died removing the need to restart clients to recover the number of thread running.

Local State Stores

Kafka Streams provides so-called state stores, which can be used by stream processing applications to store and query data, which is an important capability when implementing stateful operations. The Kafka Streams DSL, for example, automatically creates and manages such state stores when you are calling stateful operators such as join() or aggregate(), or when you are windowing a stream.

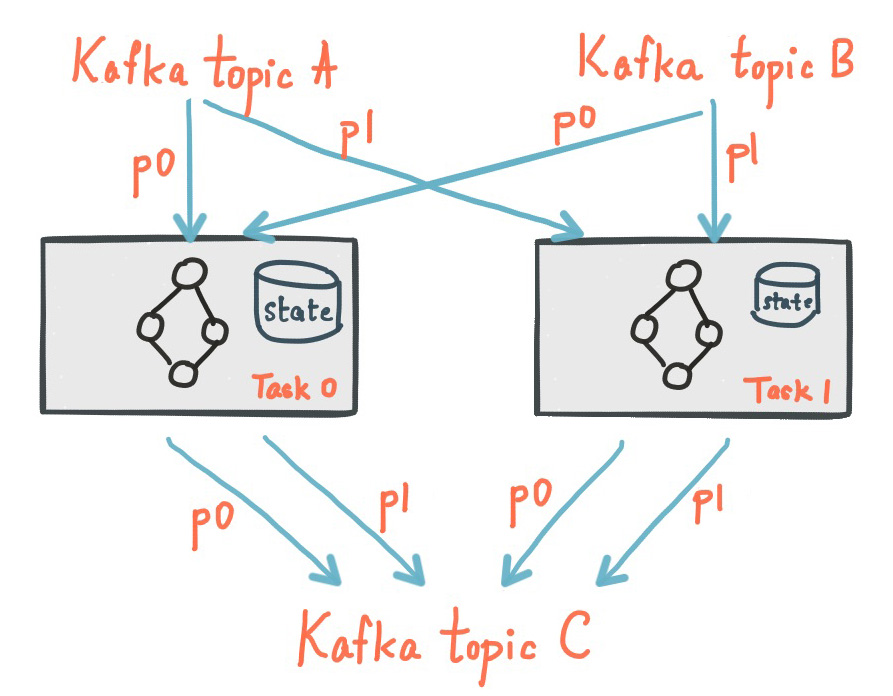
Every stream task in a Kafka Streams application may embed one or more local state stores that can be accessed via APIs to store and query data required for processing. Kafka Streams offers fault-tolerance and automatic recovery for such local state stores.

The following diagram shows two stream tasks with their dedicated local state stores.

img

Fault Tolerance

Kafka Streams builds on fault-tolerance capabilities integrated natively within Kafka. Kafka partitions are highly available and replicated; so when stream data is persisted to Kafka it is available even if the application fails and needs to re-process it. Tasks in Kafka Streams leverage the fault-tolerance capability offered by the Kafka consumer client to handle failures. If a task runs on a machine that fails, Kafka Streams automatically restarts the task in one of the remaining running instances of the application.

In addition, Kafka Streams makes sure that the local state stores are robust to failures, too. For each state store, it maintains a replicated changelog Kafka topic in which it tracks any state updates. These changelog topics are partitioned as well so that each local state store instance, and hence the task accessing the store, has its own dedicated changelog topic partition. Log compaction is enabled on the changelog topics so that old data can be purged safely to prevent the topics from growing indefinitely. If tasks run on a machine that fails and are restarted on another machine, Kafka Streams guarantees to restore their associated state stores to the content before the failure by replaying the corresponding changelog topics prior to resuming the processing on the newly started tasks. As a result, failure handling is completely transparent to the end user.

Note that the cost of task (re)initialization typically depends primarily on the time for restoring the state by replaying the state stores' associated changelog topics. To minimize this restoration time, users can configure their applications to have standby replicas of local states (i.e. fully replicated copies of the state). When a task migration happens, Kafka Streams will assign a task to an application instance where such a standby replica already exists in order to minimize the task (re)initialization cost. See num.standby.replicas in the Kafka Streams Configs section. Starting in 2.6, Kafka Streams will guarantee that a task is only ever assigned to an instance with a fully caught-up local copy of the state, if such an instance exists. Standby tasks will increase the likelihood that a caught-up instance exists in the case of a failure.

Views: 202

KAFKA STREAMS CONCEPTS

INTRODUCTION RUN DEMO APP TUTORIAL: WRITE APP CONCEPTS ARCHITECTURE DEVELOPER GUIDE UPGRADE

Kafka Streams is a client library for processing and analyzing data stored in Kafka. It builds upon important stream processing concepts such as properly distinguishing between event time and processing time, windowing support, and simple yet efficient management and real-time querying of application state.

Kafka Streams has a low barrier to entry: You can quickly write and run a small-scale proof-of-concept on a single machine; and you only need to run additional instances of your application on multiple machines to scale up to high-volume production workloads. Kafka Streams transparently handles the load balancing of multiple instances of the same application by leveraging Kafka's parallelism model.

Some highlights of Kafka Streams:

  • Designed as a simple and lightweight client library, which can be easily embedded in any Java application and integrated with any existing packaging, deployment and operational tools that users have for their streaming applications.
  • Has no external dependencies on systems other than Apache Kafka itself as the internal messaging layer; notably, it uses Kafka's partitioning model to horizontally scale processing while maintaining strong ordering guarantees.
  • Supports fault-tolerant local state, which enables very fast and efficient stateful operations like windowed joins and aggregations.
  • Supports exactly-once processing semantics to guarantee that each record will be processed once and only once even when there is a failure on either Streams clients or Kafka brokers in the middle of processing.
  • Employs one-record-at-a-time processing to achieve millisecond processing latency, and supports event-time based windowing operations with out-of-order arrival of records.
  • Offers necessary stream processing primitives, along with a high-level Streams DSL and a low-level Processor API.

We first summarize the key concepts of Kafka Streams.

Stream Processing Topology

  • A stream is the most important abstraction provided by Kafka Streams: it represents an unbounded, continuously updating data set. A stream is an ordered, replayable, and fault-tolerant sequence of immutable data records, where a data record is defined as a key-value pair.
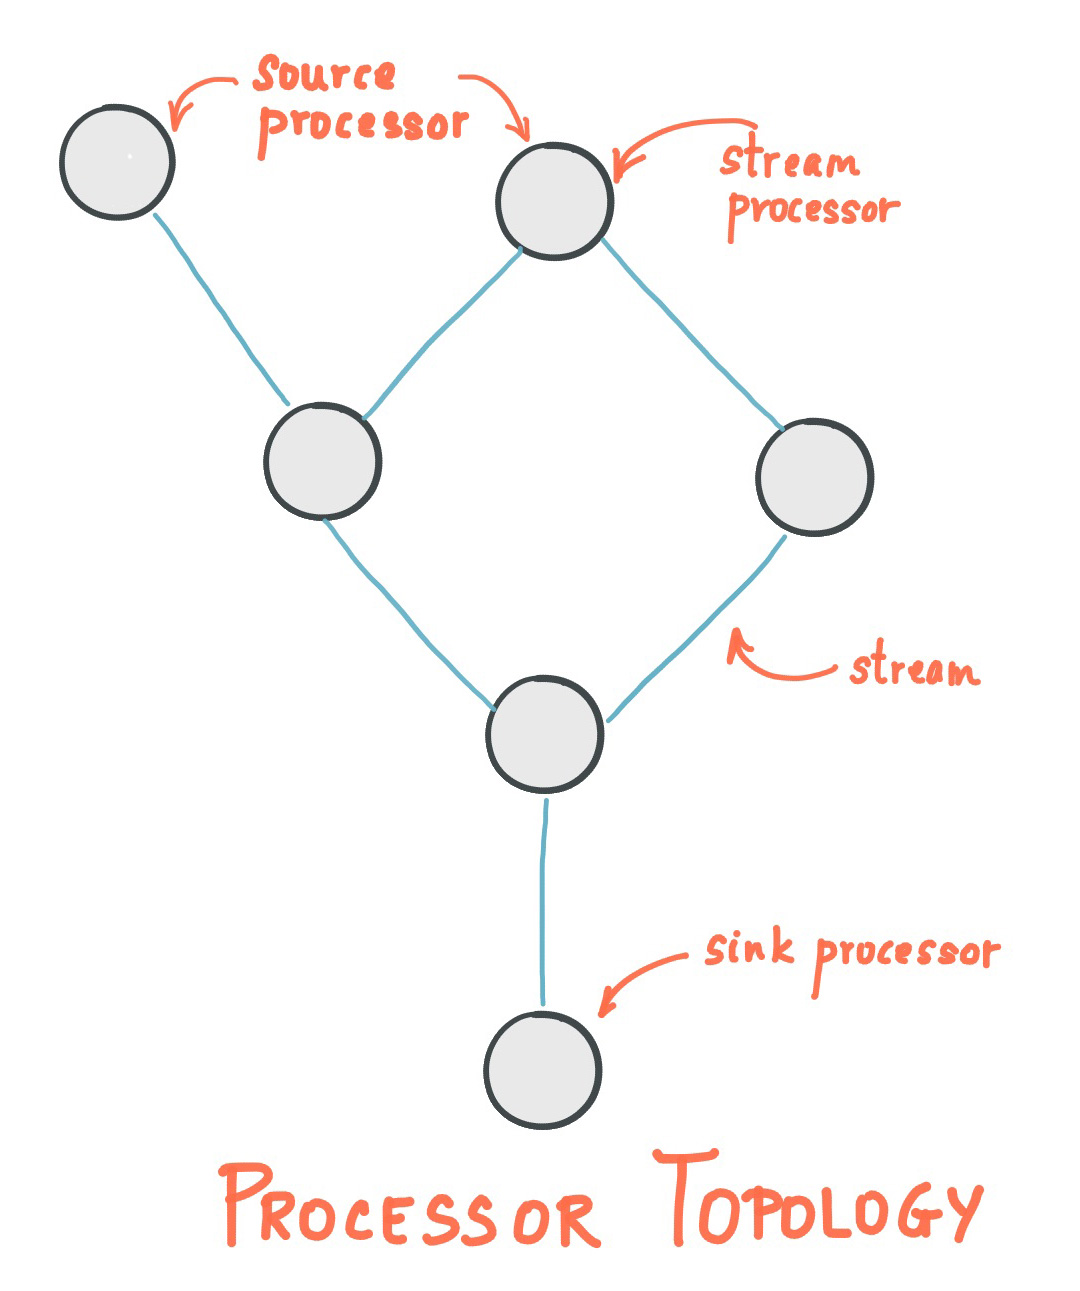
  • A stream processing application is any program that makes use of the Kafka Streams library. It defines its computational logic through one or more processor topologies, where a processor topology is a graph of stream processors (nodes) that are connected by streams (edges).
  • A stream processor is a node in the processor topology; it represents a processing step to transform data in streams by receiving one input record at a time from its upstream processors in the topology, applying its operation to it, and may subsequently produce one or more output records to its downstream processors.

There are two special processors in the topology:

  • Source Processor: A source processor is a special type of stream processor that does not have any upstream processors. It produces an input stream to its topology from one or multiple Kafka topics by consuming records from these topics and forwarding them to its down-stream processors.
  • Sink Processor: A sink processor is a special type of stream processor that does not have down-stream processors. It sends any received records from its up-stream processors to a specified Kafka topic.

Note that in normal processor nodes other remote systems can also be accessed while processing the current record. Therefore the processed results can either be streamed back into Kafka or written to an external system.

img

Kafka Streams offers two ways to define the stream processing topology: the Kafka Streams DSL provides the most common data transformation operations such as map, filter, join and aggregations out of the box; the lower-level Processor API allows developers define and connect custom processors as well as to interact with state stores.

A processor topology is merely a logical abstraction for your stream processing code. At runtime, the logical topology is instantiated and replicated inside the application for parallel processing (see Stream Partitions and Tasks for details).

Time

A critical aspect in stream processing is the notion of time, and how it is modeled and integrated. For example, some operations such as windowing are defined based on time boundaries.

Common notions of time in streams are:

  • Event time - The point in time when an event or data record occurred, i.e. was originally created "at the source". Example: If the event is a geo-location change reported by a GPS sensor in a car, then the associated event-time would be the time when the GPS sensor captured the location change.
  • Processing time - The point in time when the event or data record happens to be processed by the stream processing application, i.e. when the record is being consumed. The processing time may be milliseconds, hours, or days etc. later than the original event time. Example: Imagine an analytics application that reads and processes the geo-location data reported from car sensors to present it to a fleet management dashboard. Here, processing-time in the analytics application might be milliseconds or seconds (e.g. for real-time pipelines based on Apache Kafka and Kafka Streams) or hours (e.g. for batch pipelines based on Apache Hadoop or Apache Spark) after event-time.
  • Ingestion time - The point in time when an event or data record is stored in a topic partition by a Kafka broker. The difference to event time is that this ingestion timestamp is generated when the record is appended to the target topic by the Kafka broker, not when the record is created "at the source". The difference to processing time is that processing time is when the stream processing application processes the record. For example, if a record is never processed, there is no notion of processing time for it, but it still has an ingestion time.

The choice between event-time and ingestion-time is actually done through the configuration of Kafka (not Kafka Streams): From Kafka 0.10.x onwards, timestamps are automatically embedded into Kafka messages. Depending on Kafka's configuration these timestamps represent event-time or ingestion-time. The respective Kafka configuration setting can be specified on the broker level or per topic. The default timestamp extractor in Kafka Streams will retrieve these embedded timestamps as-is. Hence, the effective time semantics of your application depend on the effective Kafka configuration for these embedded timestamps.

Kafka Streams assigns a timestamp to every data record via the TimestampExtractor interface. These per-record timestamps describe the progress of a stream with regards to time and are leveraged by time-dependent operations such as window operations. As a result, this time will only advance when a new record arrives at the processor. We call this data-driven time the stream time of the application to differentiate with the wall-clock time when this application is actually executing. Concrete implementations of the TimestampExtractor interface will then provide different semantics to the stream time definition. For example retrieving or computing timestamps based on the actual contents of data records such as an embedded timestamp field to provide event time semantics, and returning the current wall-clock time thereby yield processing time semantics to stream time. Developers can thus enforce different notions of time depending on their business needs.

Finally, whenever a Kafka Streams application writes records to Kafka, then it will also assign timestamps to these new records. The way the timestamps are assigned depends on the context:

  • When new output records are generated via processing some input record, for example, context.forward() triggered in the process() function call, output record timestamps are inherited from input record timestamps directly.
  • When new output records are generated via periodic functions such as Punctuator#punctuate(), the output record timestamp is defined as the current internal time (obtained through context.timestamp()) of the stream task.
  • For aggregations, the timestamp of a result update record will be the maximum timestamp of all input records contributing to the result.

You can change the default behavior in the Processor API by assigning timestamps to output records explicitly when calling #forward().

For aggregations and joins, timestamps are computed by using the following rules.

  • For joins (stream-stream, table-table) that have left and right input records, the timestamp of the output record is assigned max(left.ts, right.ts).
  • For stream-table joins, the output record is assigned the timestamp from the stream record.
  • For aggregations, Kafka Streams also computes the max timestamp over all records, per key, either globally (for non-windowed) or per-window.
  • For stateless operations, the input record timestamp is passed through. For flatMap and siblings that emit multiple records, all output records inherit the timestamp from the corresponding input record.

Duality of Streams and Tables

When implementing stream processing use cases in practice, you typically need both streams and also databases. An example use case that is very common in practice is an e-commerce application that enriches an incoming stream of customer transactions with the latest customer information from a database table. In other words, streams are everywhere, but databases are everywhere, too.

Any stream processing technology must therefore provide first-class support for streams and tables. Kafka's Streams API provides such functionality through its core abstractions for streams and tables, which we will talk about in a minute. Now, an interesting observation is that there is actually a close relationship between streams and tables, the so-called stream-table duality. And Kafka exploits this duality in many ways: for example, to make your applications elastic, to support fault-tolerant stateful processing, or to run interactive queries against your application's latest processing results. And, beyond its internal usage, the Kafka Streams API also allows developers to exploit this duality in their own applications.

Before we discuss concepts such as aggregations in Kafka Streams, we must first introduce tables in more detail, and talk about the aforementioned stream-table duality. Essentially, this duality means that a stream can be viewed as a table, and a table can be viewed as a stream. Kafka's log compaction feature, for example, exploits this duality.

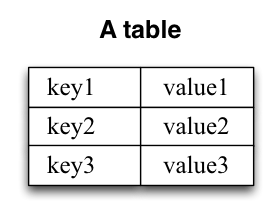
A simple form of a table is a collection of key-value pairs, also called a map or associative array. Such a table may look as follows:

img

The stream-table duality describes the close relationship between streams and tables.

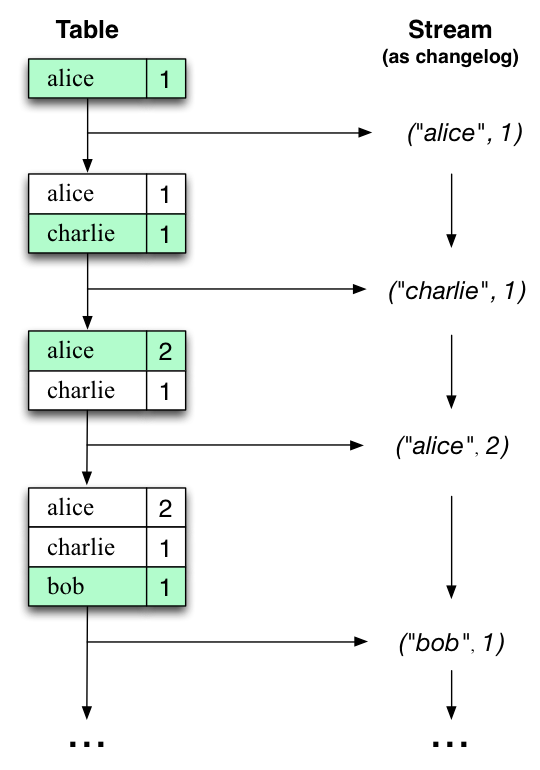
  • Stream as Table: A stream can be considered a changelog of a table, where each data record in the stream captures a state change of the table. A stream is thus a table in disguise, and it can be easily turned into a "real" table by replaying the changelog from beginning to end to reconstruct the table. Similarly, in a more general analogy, aggregating data records in a stream - such as computing the total number of pageviews by user from a stream of pageview events - will return a table (here with the key and the value being the user and its corresponding pageview count, respectively).
  • Table as Stream: A table can be considered a snapshot, at a point in time, of the latest value for each key in a stream (a stream's data records are key-value pairs). A table is thus a stream in disguise, and it can be easily turned into a "real" stream by iterating over each key-value entry in the table.

Let's illustrate this with an example. Imagine a table that tracks the total number of pageviews by user (first column of diagram below). Over time, whenever a new pageview event is processed, the state of the table is updated accordingly. Here, the state changes between different points in time - and different revisions of the table - can be represented as a changelog stream (second column).

img

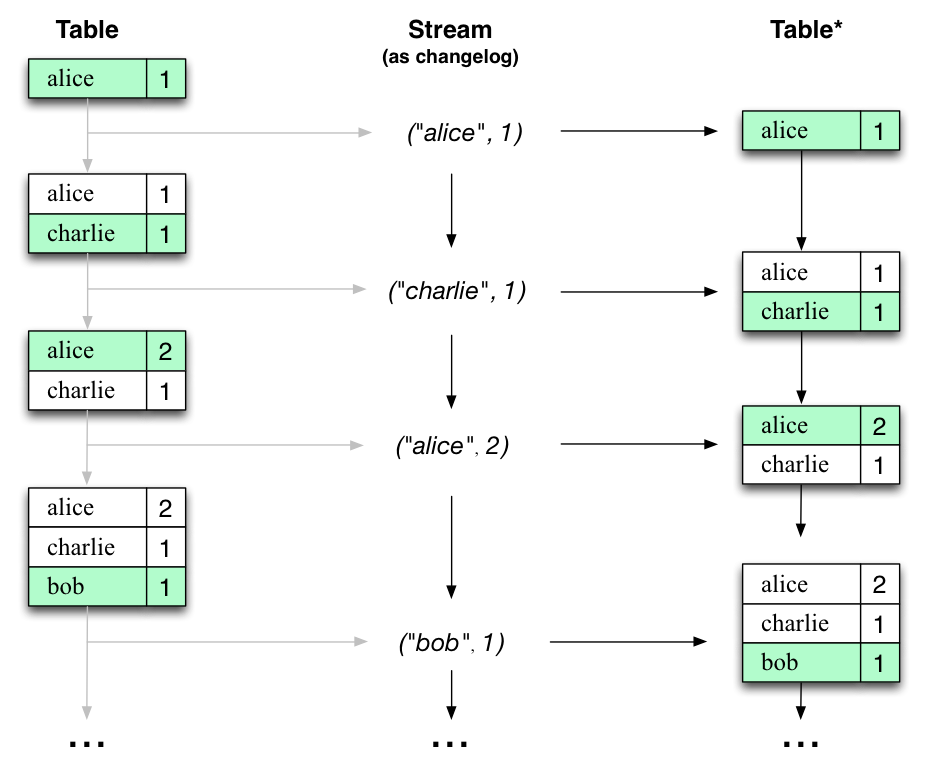
Interestingly, because of the stream-table duality, the same stream can be used to reconstruct the original table (third column):

img

The same mechanism is used, for example, to replicate databases via change data capture (CDC) and, within Kafka Streams, to replicate its so-called state stores across machines for fault-tolerance. The stream-table duality is such an important concept that Kafka Streams models it explicitly via the KStream, KTable, and GlobalKTable interfaces.

Aggregations

An aggregation operation takes one input stream or table, and yields a new table by combining multiple input records into a single output record. Examples of aggregations are computing counts or sum.

In the Kafka Streams DSL, an input stream of an aggregation can be a KStream or a KTable, but the output stream will always be a KTable. This allows Kafka Streams to update an aggregate value upon the out-of-order arrival of further records after the value was produced and emitted. When such out-of-order arrival happens, the aggregating KStream or KTable emits a new aggregate value. Because the output is a KTable, the new value is considered to overwrite the old value with the same key in subsequent processing steps.

Windowing

Windowing lets you control how to group records that have the same key for stateful operations such as aggregations or joins into so-called windows. Windows are tracked per record key.

Windowing operations are available in the Kafka Streams DSL. When working with windows, you can specify a grace period for the window. This grace period controls how long Kafka Streams will wait for out-of-order data records for a given window. If a record arrives after the grace period of a window has passed, the record is discarded and will not be processed in that window. Specifically, a record is discarded if its timestamp dictates it belongs to a window, but the current stream time is greater than the end of the window plus the grace period.

Out-of-order records are always possible in the real world and should be properly accounted for in your applications. It depends on the effective time semantics how out-of-order records are handled. In the case of processing-time, the semantics are "when the record is being processed", which means that the notion of out-of-order records is not applicable as, by definition, no record can be out-of-order. Hence, out-of-order records can only be considered as such for event-time. In both cases, Kafka Streams is able to properly handle out-of-order records.

States

Some stream processing applications don't require state, which means the processing of a message is independent from the processing of all other messages. However, being able to maintain state opens up many possibilities for sophisticated stream processing applications: you can join input streams, or group and aggregate data records. Many such stateful operators are provided by the Kafka Streams DSL.

Kafka Streams provides so-called state stores, which can be used by stream processing applications to store and query data. This is an important capability when implementing stateful operations. Every task in Kafka Streams embeds one or more state stores that can be accessed via APIs to store and query data required for processing. These state stores can either be a persistent key-value store, an in-memory hashmap, or another convenient data structure. Kafka Streams offers fault-tolerance and automatic recovery for local state stores.

Kafka Streams allows direct read-only queries of the state stores by methods, threads, processes or applications external to the stream processing application that created the state stores. This is provided through a feature called Interactive Queries. All stores are named and Interactive Queries exposes only the read operations of the underlying implementation.

PROCESSING GUARANTEES

In stream processing, one of the most frequently asked question is "does my stream processing system guarantee that each record is processed once and only once, even if some failures are encountered in the middle of processing?" Failing to guarantee exactly-once stream processing is a deal-breaker for many applications that cannot tolerate any data-loss or data duplicates, and in that case a batch-oriented framework is usually used in addition to the stream processing pipeline, known as the Lambda Architecture. Prior to 0.11.0.0, Kafka only provides at-least-once delivery guarantees and hence any stream processing systems that leverage it as the backend storage could not guarantee end-to-end exactly-once semantics. In fact, even for those stream processing systems that claim to support exactly-once processing, as long as they are reading from / writing to Kafka as the source / sink, their applications cannot actually guarantee that no duplicates will be generated throughout the pipeline.
Since the 0.11.0.0 release, Kafka has added support to allow its producers to send messages to different topic partitions in a transactional and idempotent manner, and Kafka Streams has hence added the end-to-end exactly-once processing semantics by leveraging these features. More specifically, it guarantees that for any record read from the source Kafka topics, its processing results will be reflected exactly once in the output Kafka topic as well as in the state stores for stateful operations. Note the key difference between Kafka Streams end-to-end exactly-once guarantee with other stream processing frameworks' claimed guarantees is that Kafka Streams tightly integrates with the underlying Kafka storage system and ensure that commits on the input topic offsets, updates on the state stores, and writes to the output topics will be completed atomically instead of treating Kafka as an external system that may have side-effects. For more information on how this is done inside Kafka Streams, see KIP-129.
As of the 2.6.0 release, Kafka Streams supports an improved implementation of exactly-once processing, named "exactly-once v2", which requires broker version 2.5.0 or newer. This implementation is more efficient, because it reduces client and broker resource utilization, like client threads and used network connections, and it enables higher throughput and improved scalability. As of the 3.0.0 release, the first version of exactly-once has been deprecated. Users are encouraged to use exactly-once v2 for exactly-once processing from now on, and prepare by upgrading their brokers if necessary. For more information on how this is done inside the brokers and Kafka Streams, see KIP-447.
To enable exactly-once semantics when running Kafka Streams applications, set the processing.guarantee config value (default value is at_least_once) to StreamsConfig.EXACTLY_ONCE_V2 (requires brokers version 2.5 or newer). For more information, see the Kafka Streams Configs section.

Out-of-Order Handling

Besides the guarantee that each record will be processed exactly-once, another issue that many stream processing application will face is how to handle out-of-order data that may impact their business logic. In Kafka Streams, there are two causes that could potentially result in out-of-order data arrivals with respect to their timestamps:

  • Within a topic-partition, a record's timestamp may not be monotonically increasing along with their offsets. Since Kafka Streams will always try to process records within a topic-partition to follow the offset order, it can cause records with larger timestamps (but smaller offsets) to be processed earlier than records with smaller timestamps (but larger offsets) in the same topic-partition.
  • Within a stream task that may be processing multiple topic-partitions, if users configure the application to not wait for all partitions to contain some buffered data and pick from the partition with the smallest timestamp to process the next record, then later on when some records are fetched for other topic-partitions, their timestamps may be smaller than those processed records fetched from another topic-partition.

For stateless operations, out-of-order data will not impact processing logic since only one record is considered at a time, without looking into the history of past processed records; for stateful operations such as aggregations and joins, however, out-of-order data could cause the processing logic to be incorrect. If users want to handle such out-of-order data, generally they need to allow their applications to wait for longer time while bookkeeping their states during the wait time, i.e. making trade-off decisions between latency, cost, and correctness. In Kafka Streams specifically, users can configure their window operators for windowed aggregations to achieve such trade-offs (details can be found in Developer Guide). As for Joins, users have to be aware that some of the out-of-order data cannot be handled by increasing on latency and cost in Streams yet:

  • For Stream-Stream joins, all three types (inner, outer, left) handle out-of-order records correctly, but the resulted stream may contain unnecessary leftRecord-null for left joins, and leftRecord-null or null-rightRecord for outer joins.
  • For Stream-Table joins, out-of-order records are not handled (i.e., Streams applications don't check for out-of-order records and just process all records in offset order), and hence it may produce unpredictable results.
  • For Table-Table joins, out-of-order records are not handled (i.e., Streams applications don't check for out-of-order records and just process all records in offset order). However, the join result is a changelog stream and hence will be eventually consistent.

Views: 188

TUTORIAL: WRITE A KAFKA STREAMS APPLICATION

INTRODUCTION RUN DEMO APP TUTORIAL: WRITE APP CONCEPTS ARCHITECTURE DEVELOPER GUIDE UPGRADE

In this guide we will start from scratch on setting up your own project to write a stream processing application using Kafka Streams. It is highly recommended to read the quickstart first on how to run a Streams application written in Kafka Streams if you have not done so.

Setting up a Maven Project

We are going to use a Kafka Streams Maven Archetype for creating a Streams project structure with the following commands:

mvn archetype:generate \
    -DarchetypeGroupId=org.apache.kafka \
    -DarchetypeArtifactId=streams-quickstart-java \
    -DarchetypeVersion=2.6.0 \
    -DgroupId=streams.examples \
    -DartifactId=streams.examples \
    -Dversion=0.1 \
    -Dpackage=myapps

Windows 中 \ 要替换成 ^

You can use a different value for groupId, artifactId and package parameters if you like. Assuming the above parameter values are used, this command will create a project structure that looks like this:

> tree streams.examples
streams-quickstart
|-- pom.xml
|-- src
    |-- main
        |-- java
        |   |-- myapps
        |       |-- LineSplit.java
        |       |-- Pipe.java
        |       |-- WordCount.java
        |-- resources
            |-- log4j.properties

The pom.xml file included in the project already has the Streams dependency defined. Note, that the generated pom.xml targets Java 8, and does not work with higher Java versions.

There are already several example programs written with Streams library under src/main/java. Since we are going to start writing such programs from scratch, we can now delete these examples:

> cd streams-quickstart
> rm src/main/java/myapps/*.java

Writing a first Streams application: Pipe

It's coding time now! Feel free to open your favorite IDE and import this Maven project, or simply open a text editor and create a java file under src/main/java/myapps. Let's name it Pipe.java:

package myapps;

public class Pipe {

    public static void main(String[] args) throws Exception {

    }
}

We are going to fill in the main function to write this pipe program. Note that we will not list the import statements as we go since IDEs can usually add them automatically. However if you are using a text editor you need to manually add the imports, and at the end of this section we'll show the complete code snippet with import statement for you.

The first step to write a Streams application is to create a java.util.Properties map to specify different Streams execution configuration values as defined in StreamsConfig. A couple of important configuration values you need to set are: StreamsConfig.BOOTSTRAP_SERVERS_CONFIG, which specifies a list of host/port pairs to use for establishing the initial connection to the Kafka cluster, and StreamsConfig.APPLICATION_ID_CONFIG, which gives the unique identifier of your Streams application to distinguish itself with other applications talking to the same Kafka cluster:

Properties props = new Properties();
props.put(StreamsConfig.APPLICATION_ID_CONFIG, "streams-pipe");
props.put(StreamsConfig.BOOTSTRAP_SERVERS_CONFIG, "hadoop000:9092");    // assuming that the Kafka broker this application is talking to runs on local machine with port 9092

In addition, you can customize other configurations in the same map, for example, default serialization and deserialization libraries for the record key-value pairs:

   props.put(StreamsConfig.DEFAULT_KEY_SERDE_CLASS_CONFIG, Serdes.String().getClass());
   props.put(StreamsConfig.DEFAULT_VALUE_SERDE_CLASS_CONFIG, Serdes.String().getClass());

For a full list of configurations of Kafka Streams please refer to this table.

Next we will define the computational logic of our Streams application. In Kafka Streams this computational logic is defined as a topology of connected processor nodes. We can use a topology builder to construct such a topology,

final StreamsBuilder builder = new StreamsBuilder();

And then create a source stream from a Kafka topic named streams-plaintext-input using this topology builder:

KStream<String, String> source = builder.stream("streams-plaintext-input");

Now we get a KStream that is continuously generating records from its source Kafka topic streams-plaintext-input. The records are organized as String typed key-value pairs. The simplest thing we can do with this stream is to write it into another Kafka topic, say it's named streams-pipe-output:

source.to("streams-pipe-output");

Note that we can also concatenate the above two lines into a single line as:

builder.stream("streams-plaintext-input").to("streams-pipe-output");

We can inspect what kind of topology is created from this builder by doing the following:

final Topology topology = builder.build();

And print its description to standard output as:

System.out.println(topology.describe());

If we just stop here, compile and run the program, it will output the following information:

> mvn clean package
> mvn exec:java -Dexec.mainClass=myapps.Pipe
Sub-topologies:
  Sub-topology: 0
    Source: KSTREAM-SOURCE-0000000000(topics: streams-plaintext-input) --> KSTREAM-SINK-0000000001
    Sink: KSTREAM-SINK-0000000001(topic: streams-pipe-output) <-- KSTREAM-SOURCE-0000000000
Global Stores:
  none

As shown above, it illustrates that the constructed topology has two processor nodes, a source node KSTREAM-SOURCE-0000000000 and a sink node KSTREAM-SINK-0000000001.

KSTREAM-SOURCE-0000000000 continuously read records from Kafka topic streams-plaintext-input and pipe them to its downstream node KSTREAM-SINK-0000000001;

KSTREAM-SINK-0000000001 will write each of its received record in order to another Kafka topic streams-pipe-output (the --> and <-- arrows dictates the downstream and upstream processor nodes of this node, i.e. "children" and "parents" within the topology graph).

It also illustrates that this simple topology has no global state stores associated with it (we will talk about state stores more in the following sections).

Note that we can always describe the topology as we did above at any given point while we are building it in the code, so as a user you can interactively "try and taste" your computational logic defined in the topology until you are happy with it. Suppose we are already done with this simple topology that just pipes data from one Kafka topic to another in an endless streaming manner, we can now construct the Streams client with the two components we have just constructed above: the configuration map specified in a java.util.Properties instance and the Topology object.

final KafkaStreams streams = new KafkaStreams(topology, props);

By calling its start() function we can trigger the execution of this client. The execution won't stop until close() is called on this client. We can, for example, add a shutdown hook with a countdown latch to capture a user interrupt and close the client upon terminating this program:

final CountDownLatch latch = new CountDownLatch(1);

// attach shutdown handler to catch control-c
Runtime.getRuntime().addShutdownHook(new Thread("streams-shutdown-hook") {
    @Override
    public void run() {
        streams.close();
        latch.countDown();
    }
});

try {
    streams.start();
    latch.await();
} catch (Throwable e) {
    System.exit(1);
}
System.exit(0);

The complete code so far looks like this:

package myapps;

import org.apache.kafka.common.serialization.Serdes;
import org.apache.kafka.streams.KafkaStreams;
import org.apache.kafka.streams.StreamsBuilder;
import org.apache.kafka.streams.StreamsConfig;
import org.apache.kafka.streams.Topology;

import java.util.Properties;
import java.util.concurrent.CountDownLatch;

public class Pipe {

    public static void main(String[] args) throws Exception {
        Properties props = new Properties();
        props.put(StreamsConfig.APPLICATION_ID_CONFIG, "streams-pipe");
        props.put(StreamsConfig.BOOTSTRAP_SERVERS_CONFIG, "hadoop000:9092");
        props.put(StreamsConfig.DEFAULT_KEY_SERDE_CLASS_CONFIG, Serdes.String().getClass());
        props.put(StreamsConfig.DEFAULT_VALUE_SERDE_CLASS_CONFIG, Serdes.String().getClass());

        final StreamsBuilder builder = new StreamsBuilder();

        builder.stream("streams-plaintext-input").to("streams-pipe-output");

        final Topology topology = builder.build();

        final KafkaStreams streams = new KafkaStreams(topology, props);
        final CountDownLatch latch = new CountDownLatch(1);

        // attach shutdown handler to catch control-c
        Runtime.getRuntime().addShutdownHook(new Thread("streams-shutdown-hook") {
            @Override
            public void run() {
                streams.close();
                latch.countDown();
            }
        });

        try {
            streams.start();
            latch.await();
        } catch (Throwable e) {
            System.exit(1);
        }
        System.exit(0);
    }
}

If you already have the Kafka broker up and running at hadoop000:9092, and the topics streams-plaintext-input and streams-pipe-output created on that broker, you can run this code in your IDE or on the command line, using Maven:

> mvn clean package
> mvn exec:java -Dexec.mainClass=myapps.Pipe

For detailed instructions on how to run a Streams application and observe its computing results, please read the Play with a Streams Application section. We will not talk about this in the rest of this section.

Writing a second Streams application: Line Split

We have learned how to construct a Streams client with its two key components: the StreamsConfig and Topology. Now let's move on to add some real processing logic by augmenting the current topology. We can first create another program by first copy the existing Pipe.java class:

> cp src/main/java/myapps/Pipe.java src/main/java/myapps/LineSplit.java

And change its class name as well as the application id config to distinguish with the original program:

public class LineSplit {

    public static void main(String[] args) throws Exception {
        Properties props = new Properties();
        props.put(StreamsConfig.APPLICATION_ID_CONFIG, "streams-linesplit");
        // ...
    }
}

Since each of the source stream's record is a String typed key-value pair, let's treat the value string as a text line and split it into words with a FlatMapValues operator:

KStream<String, String> source = builder.stream("streams-plaintext-input");
KStream<String, String> words = source.flatMapValues(new ValueMapper<String, Iterable<String>>() {
    @Override
    public Iterable<String> apply(String value) {
        return Arrays.asList(value.split("\\W+"));
    }
});

The operator will take the source stream as its input, and generate a new stream named words by processing each record from its source stream in order and breaking its value string into a list of words, and producing each word as a new record to the output words stream. This is a stateless operator that does not need to keep track of any previously received records or processed results. Note if you are using JDK 8 you can use lambda expression and simplify the above code as:

KStream<String, String> source = builder.stream("streams-plaintext-input");
KStream<String, String> words = source.flatMapValues(value -> Arrays.asList(value.split("\\W+")));

And finally we can write the word stream back into another Kafka topic, say streams-linesplit-output. Again, these two steps can be concatenated as the following (assuming lambda expression is used):

KStream<String, String> source = builder.stream("streams-plaintext-input");
source.flatMapValues(value -> Arrays.asList(value.split("\\W+")))
      .to("streams-linesplit-output");

If we now describe this augmented topology as System.out.println(topology.describe()), we will get the following:

> mvn clean package
> mvn exec:java -Dexec.mainClass=myapps.LineSplit
Sub-topologies:
  Sub-topology: 0
    Source: KSTREAM-SOURCE-0000000000(topics: streams-plaintext-input) --> KSTREAM-FLATMAPVALUES-0000000001
    Processor: KSTREAM-FLATMAPVALUES-0000000001(stores: []) --> KSTREAM-SINK-0000000002 <-- KSTREAM-SOURCE-0000000000
    Sink: KSTREAM-SINK-0000000002(topic: streams-linesplit-output) <-- KSTREAM-FLATMAPVALUES-0000000001
  Global Stores:
    none

As we can see above, a new processor node KSTREAM-FLATMAPVALUES-0000000001 is injected into the topology between the original source and sink nodes. It takes the source node as its parent and the sink node as its child. In other words, each record fetched by the source node will first traverse to the newly added KSTREAM-FLATMAPVALUES-0000000001 node to be processed, and one or more new records will be generated as a result. They will continue traverse down to the sink node to be written back to Kafka. Note this processor node is "stateless" as it is not associated with any stores (i.e. (stores: [])).

The complete code looks like this (assuming lambda expression is used):

package myapps;

import org.apache.kafka.common.serialization.Serdes;
import org.apache.kafka.streams.KafkaStreams;
import org.apache.kafka.streams.StreamsBuilder;
import org.apache.kafka.streams.StreamsConfig;
import org.apache.kafka.streams.Topology;
import org.apache.kafka.streams.kstream.KStream;

import java.util.Arrays;
import java.util.Properties;
import java.util.concurrent.CountDownLatch;

public class LineSplit {

    public static void main(String[] args) throws Exception {
        Properties props = new Properties();
        props.put(StreamsConfig.APPLICATION_ID_CONFIG, "streams-linesplit");
        props.put(StreamsConfig.BOOTSTRAP_SERVERS_CONFIG, "hadoop000:9092");
        props.put(StreamsConfig.DEFAULT_KEY_SERDE_CLASS_CONFIG, Serdes.String().getClass());
        props.put(StreamsConfig.DEFAULT_VALUE_SERDE_CLASS_CONFIG, Serdes.String().getClass());

        final StreamsBuilder builder = new StreamsBuilder();

        KStream<String, String> source = builder.stream("streams-plaintext-input");
        source.flatMapValues(value -> Arrays.asList(value.split("\\W+")))
              .to("streams-linesplit-output");

        final Topology topology = builder.build();
        final KafkaStreams streams = new KafkaStreams(topology, props);
        final CountDownLatch latch = new CountDownLatch(1);

        // ... same as Pipe.java above
    }
}

Writing a third Streams application: Wordcount

Let's now take a step further to add some "stateful" computations to the topology by counting the occurrence of the words split from the source text stream. Following similar steps let's create another program based on the LineSplit.java class:

public class WordCount {

    public static void main(String[] args) throws Exception {
        Properties props = new Properties();
        props.put(StreamsConfig.APPLICATION_ID_CONFIG, "streams-wordcount");
        // ...
    }
}

In order to count the words we can first modify the flatMapValues operator to treat all of them as lower case (assuming lambda expression is used):

source.flatMapValues(new ValueMapper<String, Iterable<String>>() {
            @Override
            public Iterable<String> apply(String value) {
                return Arrays.asList(value.toLowerCase(Locale.getDefault()).split("\\W+"));
            }
        });

In order to do the counting aggregation we have to first specify that we want to key the stream on the value string, i.e. the lower cased word, with a groupBy operator. This operator generate a new grouped stream, which can then be aggregated by a count operator, which generates a running count on each of the grouped keys:

KTable<String, Long> counts =
source.flatMapValues(new ValueMapper<String, Iterable<String>>() {
            @Override
            public Iterable<String> apply(String value) {
                return Arrays.asList(value.toLowerCase(Locale.getDefault()).split("\\W+"));
            }
        })
      .groupBy(new KeyValueMapper<String, String, String>() {
           @Override
           public String apply(String key, String value) {
               return value;
           }
        })
      // Materialize the result into a KeyValueStore named "counts-store".
      // The Materialized store is always of type <Bytes, byte[]> as this is the format of the inner most store.
      .count(Materialized.<String, Long, KeyValueStore<Bytes, byte[]>> as("counts-store"));

Note that the count operator has a Materialized parameter that specifies that the running count should be stored in a state store named counts-store. This Counts store can be queried in real-time, with details described in the Developer Manual.

We can also write the counts KTable's changelog stream back into another Kafka topic, say streams-wordcount-output. Because the result is a changelog stream, the output topic streams-wordcount-output should be configured with log compaction enabled. Note that this time the value type is no longer String but Long, so the default serialization classes are not viable for writing it to Kafka anymore. We need to provide overridden serialization methods for Long types, otherwise a runtime exception will be thrown:

counts.toStream().to("streams-wordcount-output", Produced.with(Serdes.String(), Serdes.Long()));

Note that in order to read the changelog stream from topic streams-wordcount-output, one needs to set the value deserialization as org.apache.kafka.common.serialization.LongDeserializer. Details of this can be found in the Play with a Streams Application section. Assuming lambda expression from JDK 8 can be used, the above code can be simplified as:

KStream<String, String> source = builder.stream("streams-plaintext-input");
source.flatMapValues(value -> Arrays.asList(value.toLowerCase(Locale.getDefault()).split("\\W+")))
      .groupBy((key, value) -> value)
      .count(Materialized.<String, Long, KeyValueStore<Bytes, byte[]>>as("counts-store"))
      .toStream()
      .to("streams-wordcount-output", Produced.with(Serdes.String(), Serdes.Long()));

If we again describe this augmented topology as System.out.println(topology.describe()), we will get the following:

> mvn clean package
> mvn exec:java -Dexec.mainClass=myapps.WordCount
Sub-topologies:
  Sub-topology: 0
    Source: KSTREAM-SOURCE-0000000000(topics: streams-plaintext-input) --> KSTREAM-FLATMAPVALUES-0000000001
    Processor: KSTREAM-FLATMAPVALUES-0000000001(stores: []) --> KSTREAM-KEY-SELECT-0000000002 <-- KSTREAM-SOURCE-0000000000
    Processor: KSTREAM-KEY-SELECT-0000000002(stores: []) --> KSTREAM-FILTER-0000000005 <-- KSTREAM-FLATMAPVALUES-0000000001
    Processor: KSTREAM-FILTER-0000000005(stores: []) --> KSTREAM-SINK-0000000004 <-- KSTREAM-KEY-SELECT-0000000002
    Sink: KSTREAM-SINK-0000000004(topic: Counts-repartition) <-- KSTREAM-FILTER-0000000005
  Sub-topology: 1
    Source: KSTREAM-SOURCE-0000000006(topics: Counts-repartition) --> KSTREAM-AGGREGATE-0000000003
    Processor: KSTREAM-AGGREGATE-0000000003(stores: [Counts]) --> KTABLE-TOSTREAM-0000000007 <-- KSTREAM-SOURCE-0000000006
    Processor: KTABLE-TOSTREAM-0000000007(stores: []) --> KSTREAM-SINK-0000000008 <-- KSTREAM-AGGREGATE-0000000003
    Sink: KSTREAM-SINK-0000000008(topic: streams-wordcount-output) <-- KTABLE-TOSTREAM-0000000007
Global Stores:
  none

As we can see above, the topology now contains two disconnected sub-topologies. The first sub-topology's sink node KSTREAM-SINK-0000000004 will write to a repartition topic Counts-repartition, which will be read by the second sub-topology's source node KSTREAM-SOURCE-0000000006. The repartition topic is used to "shuffle" the source stream by its aggregation key, which is in this case the value string. In addition, inside the first sub-topology a stateless KSTREAM-FILTER-0000000005 node is injected between the grouping KSTREAM-KEY-SELECT-0000000002 node and the sink node to filter out any intermediate record whose aggregate key is empty.

In the second sub-topology, the aggregation node KSTREAM-AGGREGATE-0000000003 is associated with a state store named Counts (the name is specified by the user in the count operator). Upon receiving each record from its upcoming stream source node, the aggregation processor will first query its associated Counts store to get the current count for that key, augment by one, and then write the new count back to the store. Each updated count for the key will also be piped downstream to the KTABLE-TOSTREAM-0000000007 node, which interpret this update stream as a record stream before further piping to the sink node KSTREAM-SINK-0000000008 for writing back to Kafka.

The complete code looks like this (assuming lambda expression is used):

package myapps;

import org.apache.kafka.common.serialization.Serdes;
import org.apache.kafka.streams.KafkaStreams;
import org.apache.kafka.streams.StreamsBuilder;
import org.apache.kafka.streams.StreamsConfig;
import org.apache.kafka.streams.Topology;
import org.apache.kafka.streams.kstream.KStream;

import java.util.Arrays;
import java.util.Locale;
import java.util.Properties;
import java.util.concurrent.CountDownLatch;

public class WordCount {

    public static void main(String[] args) throws Exception {
        Properties props = new Properties();
        props.put(StreamsConfig.APPLICATION_ID_CONFIG, "streams-wordcount");
        props.put(StreamsConfig.BOOTSTRAP_SERVERS_CONFIG, "hadoop000:9092");
        props.put(StreamsConfig.DEFAULT_KEY_SERDE_CLASS_CONFIG, Serdes.String().getClass());
        props.put(StreamsConfig.DEFAULT_VALUE_SERDE_CLASS_CONFIG, Serdes.String().getClass());

        final StreamsBuilder builder = new StreamsBuilder();

        KStream<String, String> source = builder.stream("streams-plaintext-input");
        source.flatMapValues(value -> Arrays.asList(value.toLowerCase(Locale.getDefault()).split("\\W+")))
              .groupBy((key, value) -> value)
              .count(Materialized.<String, Long, KeyValueStore<Bytes, byte[]>>as("counts-store"))
              .toStream()
              .to("streams-wordcount-output", Produced.with(Serdes.String(), Serdes.Long()));

        final Topology topology = builder.build();
        final KafkaStreams streams = new KafkaStreams(topology, props);
        final CountDownLatch latch = new CountDownLatch(1);

        // ... same as Pipe.java above
    }
}

Views: 192
Storm 集成 Redis

官方文档: Storm/Trident 集成 Redis

Storm-redis 使用 Jedis 作为 Redis client.

maven 依赖配置如下:

<dependency>
    <groupId>org.apache.storm</groupId>
    <artifactId>storm-redis</artifactId>
    <version>${storm.version}</version>
    <type>jar</type>
</dependency>

一般情况

storm-redis提供的三种基本的bolt实现:

  1. RedisLookupBolt 通过 key 从 redis 获取对应的 value
  2. RedisStoreBolt 存储 key / value 到 Redis
  3. RedisFilterBolt 用于过滤key或者field在 Redis 中不存在的 tuple.

Tuple和Redis中的键值对的映射关系可以通过TupleMapper来进行定义.

通过RedisDataTypeDescription这个类可以选择数据类型.参考 RedisDataTypeDescription.RedisDataType可以查看有哪些支持的数据类型.

接口 RedisLookupMapper、RedisStoreMapper、RedisFilterMapper 分别用来适配 RedisLookupBolt、RedisStoreBolt、和RedisFilterBolt. (当实现 RedisFilterMapper时要记得在declareOutputFields() 方法中定于输入流的字段, 因为 FilterBolt 会把 Redis 中的数据作为输入的 tuples 发送出去)

RedisLookupBolt 用法

class WordCountRedisLookupMapper implements RedisLookupMapper {
    private RedisDataTypeDescription description;
    private final String hashKey = "wordCount";

    public WordCountRedisLookupMapper() {
        description = new RedisDataTypeDescription(
                RedisDataTypeDescription.RedisDataType.HASH, hashKey);
    }

    @Override
    public List<Values> toTuple(ITuple input, Object value) {
        String member = getKeyFromTuple(input);
        List<Values> values = Lists.newArrayList();
        values.add(new Values(member, value));
        return values;
    }

    @Override
    public void declareOutputFields(OutputFieldsDeclarer declarer) {
        declarer.declare(new Fields("wordName", "count"));
    }

    @Override
    public RedisDataTypeDescription getDataTypeDescription() {
        return description;
    }

    @Override
    public String getKeyFromTuple(ITuple tuple) {
        return tuple.getStringByField("word");
    }

    @Override
    public String getValueFromTuple(ITuple tuple) {
        return null;
    }
}
JedisPoolConfig poolConfig = new JedisPoolConfig.Builder()
        .setHost(host).setPort(port).build();
RedisLookupMapper lookupMapper = new WordCountRedisLookupMapper();
RedisLookupBolt lookupBolt = new RedisLookupBolt(poolConfig, lookupMapper);

RedisFilterBolt 用法

RedisFilterBolt 用于当Redis不存在给定数据类型的给定 key/field 时进行过滤. 类似白名单, 即只保留Redis中存在的数据, 如果 Redis 上存在 key/field,则此 bolt 会将作为输入的元组根据指定输出格式转发到默认流。

支持的数据类型:STRING、HASH、SET、SORTED_SET、HYPER_LOG_LOG、GEO。

注1:对于 STRING,它会检查KEY SPACE中是否存在此KEY。 对于 HASH 和 SORTED_SET 和 GEO,它会检查该数据结构上是否存在此类FIELD。 对于 SET 和 HYPER_LOG_LOG,需要指定一个AdditionalKey作为KEY, 可以事先在SET 或 HYPER_LOG_LOG 中添加一些值作为白名单。这样过滤器会使用白名单和上游发来的 tuple 中的某个字段(通过RedisFilterMapper#getKeyFromTuple()方法来指定)的值进行比对,包含则放行.

注2:如果只想查询key是否在Redis中存在而不管实际数据类型为何,可将RedisFilterMapper的数据类型指定STRING。

class WhitelistWordFilterMapper implements RedisFilterMapper {

    private RedisDataTypeDescription description;

    private final String setKey = "whitelist";

    public BlacklistWordFilterMapper() {
        // 设置Redis的数据类型为SET(集合)
        // setKey 作为 AdditionalKey(集合的KEY)
        description = new RedisDataTypeDescription(
                RedisDataTypeDescription.RedisDataType.SET, setKey);
    }

    @Override
    public void declareOutputFields(OutputFieldsDeclarer declarer) {
        declarer.declare(new Fields("word", "count"));
    }

    @Override
    public RedisDataTypeDescription getDataTypeDescription() {
        return description;
    }

    // 从Redis白名单集合中比对是否包含tuple中的"word"字段的值
    // 如果存在就放行
    @Override
    public String getKeyFromTuple(ITuple tuple) {
        return tuple.getStringByField("word");
    }

    @Override
    public String getValueFromTuple(ITuple tuple) {
        return null;
    }
}

使用

JedisPoolConfig poolConfig = new JedisPoolConfig.Builder()
        .setHost(host).setPort(port).build();
RedisFilterMapper filterMapper = new WhitelistWordFilterMapper();
RedisFilterBolt filterBolt = new RedisFilterBolt(poolConfig, filterMapper);

RedisStoreBolt 用法

class WordCountStoreMapper implements RedisStoreMapper {
    private RedisDataTypeDescription description;
    private final String hashKey = "wordCount";

    public WordCountStoreMapper() {
        description = new RedisDataTypeDescription(
            RedisDataTypeDescription.RedisDataType.HASH, hashKey);
    }

    @Override
    public RedisDataTypeDescription getDataTypeDescription() {
        return description;
    }

    @Override
    public String getKeyFromTuple(ITuple tuple) {
        return tuple.getStringByField("word");
    }

    @Override
    public String getValueFromTuple(ITuple tuple) {
        return tuple.getStringByField("count");
    }
}
JedisPoolConfig poolConfig = new JedisPoolConfig.Builder()
                .setHost(host).setPort(port).build();
RedisStoreMapper storeMapper = new WordCountStoreMapper();
RedisStoreBolt storeBolt = new RedisStoreBolt(poolConfig, storeMapper);

WordCount示例(将统计结果持久化到Redis)

public class WordCountRedisTopology {

    public static class RandomSentenceSpout extends BaseRichSpout {

        SpoutOutputCollector collector;
        Random rand;

        @Override
        public void open(Map<String, Object> conf, TopologyContext context, SpoutOutputCollector collector) {
            this.collector = collector;
            rand = new Random();
        }

        @Override
        public void nextTuple() {

            Utils.sleep(1000);
            String[] sentences = new String[]{
                    "the cow jumped over the moon",
                    "an apple a day keeps the doctor away",
                    "four score and seven years ago",
                    "snow white and the seven dwarfs",
                    "i am at two with nature"
            };

            String sentence = sentences[rand.nextInt(sentences.length)];
            collector.emit(new Values(sentence));
        }

        @Override
        public void declareOutputFields(OutputFieldsDeclarer declarer) {
            declarer.declare(new Fields("line"));
        }
    }

    public static class SentenceSplitBolt extends BaseRichBolt {

        private OutputCollector collector;

        @Override
        public void declareOutputFields(OutputFieldsDeclarer declarer) {
            declarer.declare(new Fields("word"));
        }

        @Override
        public void prepare(Map<String, Object> map, TopologyContext topologyContext, OutputCollector outputCollector) {
            collector = outputCollector;
        }

        @Override
        public void execute(Tuple tuple) {

            String line = tuple.getStringByField("line");
            StringTokenizer tokenizer = new StringTokenizer(line);
            while (tokenizer.hasMoreTokens()) {
                String word = tokenizer.nextToken();
                collector.emit(new Values(word));
            }
        }
    }

    public static class DataRedisStoreMapper implements RedisStoreMapper {
        private RedisDataTypeDescription description;
        private final String hashKey = "word-count";

        public DataRedisStoreMapper() {
            description = new RedisDataTypeDescription(
                    RedisDataTypeDescription.RedisDataType.HASH, hashKey);
        }

        @Override
        public RedisDataTypeDescription getDataTypeDescription() {
            return description;
        }

        @Override
        public String getKeyFromTuple(ITuple tuple) {
            return tuple.getStringByField("word");
        }

        @Override
        public String getValueFromTuple(ITuple tuple) {
            return tuple.getIntegerByField("count") + "";
        }
    }

    public static class WordCountBolt extends BaseBasicBolt {

        Map<String, Integer> counts = new HashMap<>();

        @Override
        public void execute(Tuple tuple, BasicOutputCollector collector) {
            String word = tuple.getStringByField("word");
            Integer count = counts.get(word);
            if (count == null) {
                count = 0;
            }
            count++;
            counts.put(word, count);
            collector.emit(new Values(word, count));
        }

        @Override
        public void declareOutputFields(OutputFieldsDeclarer declarer) {
            declarer.declare(new Fields("word", "count"));
        }
    }

    public static void main(String[] args) {

        Config conf = new Config();
        conf.setNumAckers(0);
        conf.setDebug(true);

        conf.setNumWorkers(2);  // 设置为1个topology创建2个worker进程
        TopologyBuilder builder = new TopologyBuilder();
        builder.setSpout("spout", new RandomSentenceSpout());
        builder.setBolt("split", new SentenceSplitBolt(), 2).setNumTasks(4).shuffleGrouping("spout");
        builder.setBolt("count", new WordCountBolt(), 3).setNumTasks(6).fieldsGrouping("split", new Fields("word"));

        // storm to redis store
        JedisPoolConfig poolConfig = new JedisPoolConfig.Builder()
                .setPassword("niit1234").setHost("hadoop001").setPort(6379).build();
        RedisStoreMapper storeMapper = new DataRedisStoreMapper();
        RedisStoreBolt storeBolt = new RedisStoreBolt(poolConfig, storeMapper);

        builder.setBolt("store", storeBolt).shuffleGrouping("count");

        String topologyName = "word-count";

        if (args != null && args.length > 0) {
            topologyName = args[0];
        }

        try {
            LocalCluster localCluster = new LocalCluster();
            localCluster.submitTopology(topologyName, conf, builder.createTopology());
            // StormSubmitter.submitTopology(topologyName, conf, builder.createTopology());
        } catch (Exception e) {
            e.printStackTrace();
        }
    }
}

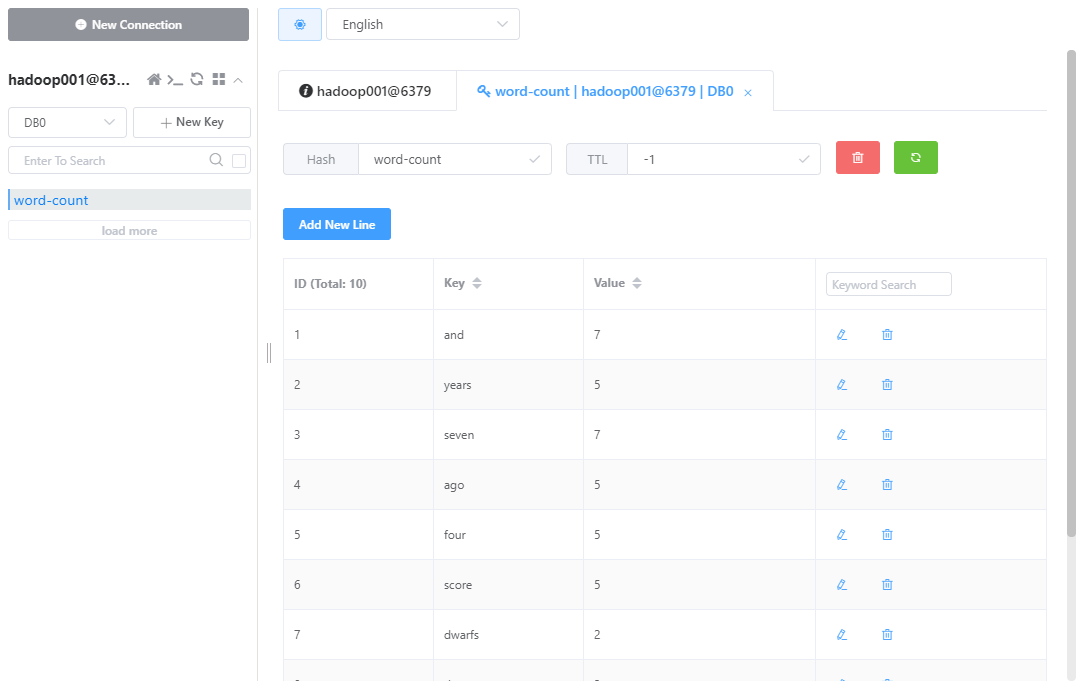
结果

image-20201215015520057

复杂情况

Storm-redis提供了通用的bolt抽象类,当 RedisStoreBolt、RedisLookupBolt、RedisFilterBolt 不符合你的使用场景时, storm-redis 也提供了抽象的 AbstractRedisBolt 类来供你继承并实现你自己的业务逻辑.

RedisLookupBolt、RedisStoreBolt、RedisFilterBolt 均继承自 AbstractRedisBolt 抽象类。我们可以通过继承该抽象类,实现自定义 Bolt,进行功能的拓展。

实现自定义Bolt: LookupWordTotalCountBolt

将数据流中字段为"word"的单词作为key在Redis中查找对应的value(即对应词频),并抽样打印结果.

public static class LookupWordTotalCountBolt extends AbstractRedisBolt {
    private static final Logger LOG = LoggerFactory.getLogger(LookupWordTotalCountBolt.class);
    private static final Random RANDOM = new Random();

    public LookupWordTotalCountBolt(JedisPoolConfig config) {
        super(config);
    }

    public LookupWordTotalCountBolt(JedisClusterConfig config) {
        super(config);
    }

    @Override
    public void execute(Tuple input) {
        JedisCommands jedisCommands = null;
        try {
            jedisCommands = getInstance();
            String wordName = input.getStringByField("word");
            String countStr = jedisCommands.get(wordName);
            if (countStr != null) {
                int count = Integer.parseInt(countStr);
                this.collector.emit(new Values(wordName, count));

                // print lookup result with low probability
                if(RANDOM.nextInt(1000) > 995) {
                    LOG.info("Lookup result - word : " + wordName + " / count : " + count);
                }
            } else {
                // skip
                LOG.warn("Word not found in Redis - word : " + wordName);
            }
        } finally {
            if (jedisCommands != null) {
                returnInstance(jedisCommands);
            }
            this.collector.ack(input);
        }
    }

    @Override
    public void declareOutputFields(OutputFieldsDeclarer declarer) {
        // wordName, count
        declarer.declare(new Fields("wordName", "count"));
    }
}

在Trident State集成Redis

  1. RedisState 和 RedisMapState, 提供了单个的Jedis客户端接口.
  2. RedisClusterState 和 RedisClusterMapState, 提供了JedisCluster客户端接口用于在拥有Redis集群情况下使用.

RedisState

JedisPoolConfig poolConfig = new JedisPoolConfig.Builder()
                                .setHost(redisHost).setPort(redisPort)
                                .build();
RedisStoreMapper storeMapper = new WordCountStoreMapper();
RedisLookupMapper lookupMapper = new WordCountLookupMapper();

RedisState.Factory factory = new RedisState.Factory(poolConfig);

TridentTopology topology = new TridentTopology();
Stream stream = topology.newStream("spout1", spout);

stream.partitionPersist(factory,
                        fields,
                        new RedisStateUpdater(storeMapper).withExpire(86400000),
                        new Fields());

TridentState state = topology.newStaticState(factory);
stream = stream.stateQuery(state, new Fields("word"),
                        new RedisStateQuerier(lookupMapper),
                        new Fields("columnName","columnValue"));

RedisClusterState

Set<InetSocketAddress> nodes = new HashSet<InetSocketAddress>();
for (String hostPort : redisHostPort.split(",")) {
    String[] host_port = hostPort.split(":");
    nodes.add(new InetSocketAddress(host_port[0], Integer.valueOf(host_port[1])));
}
JedisClusterConfig clusterConfig = new JedisClusterConfig.Builder().setNodes(nodes)
                                .build();
RedisStoreMapper storeMapper = new WordCountStoreMapper();
RedisLookupMapper lookupMapper = new WordCountLookupMapper();
RedisClusterState.Factory factory = new RedisClusterState.Factory(clusterConfig);

TridentTopology topology = new TridentTopology();
Stream stream = topology.newStream("spout1", spout);

stream.partitionPersist(factory,
                        fields,
                        new RedisClusterStateUpdater(storeMapper).withExpire(86400000),
                        new Fields());

TridentState state = topology.newStaticState(factory);
stream = stream.stateQuery(state, new Fields("word"),
                        new RedisClusterStateQuerier(lookupMapper),
                        new Fields("columnName","columnValue"));

Views: 217

Redis的5种数据类型

Redis 是一种基于键值对的NoSQL数据库,它的值主要由string(字符串),hash(哈希),list(列表),set(集合),zset(有序集合)五种基本数据结构构成,除此之外还支持一些其他的数据结构和算法。其中key都是由字符串构成的.

这些数据类型的使用方式可以查看官方文档, 下面重点说一说数据类型的选择.

Redis五大数据类型的使用场景

1. 字符串(string)

字符串类型是Redis最基础的数据类型,字符串类型可以是JSON、XML甚至是二进制的图片等数据,但是最大值不能超过512MB。

底层数据结构

Redis会根据当前值的类型和长度决定使用哪种底层数据结构来实现。

字符串类型的底层数据结构有3种:

  • int:8个字节的长整型。

  • embstr:小于等于39个字节的字符串。

  • raw:大于39个字节的字符串。

字符串类型的添加和查询

> set mykey somevalue
OK
> get mykey
"somevalue"
> set mykey newval nx   # when not exists
#> SETNX mykey newval   # 和上面命令等效
(nil)
> set mykey newval xx   # only when exists
OK

> set counter 100       # string type includes number also
OK
> incr counter          # atomic increcement by 1
(integer) 101
> incr counter
(integer) 102
> incrby counter 50      # atomic increcement by 50
(integer) 152

# Multple Set/Get 批量查询和获取
> mset a 10 b 20 c 30
OK
> mget a b c
10
20
30

字符串类型的Key空间操作

这里只列出key空间(key space)比较常用的三个方法:

  • del 删除key空间

  • type 返回key空间中所保存数据的数据类型

  • exists 查询key空间是否存在, 返回1为存在, 返回0则不存在

> set mykey hello
OK
> exists mykey
1
> type mykey
string
> del mykey
1
> exists mykey
0
> type mykey
none

设置key的过期时间-方法 1

> set key some-value
OK
> expire key 5
(integer) 1
> get key (immediately)
"some-value"
> get key (after some time)
(nil)

设置key的过期时间-方法 2

> set key 100 ex 10 # set key to 100 with expire time of 10 seconds
OK
> ttl key  # check the remaining time to live for the key
(integer) 9

设置key的过期时间-方法 3

# SETEX key seconds value 
# 给key设置value, 同时设置过期(EXpireTime)时间, 单位秒
# 如果过期则查询结果为null
> SETEX exkey 120 value
> get exkey
valuie
# 120秒后
> get exkey
null

1.2 使用场景

1.2.1 缓存

在web服务中,使用MySQL作为数据库,Redis 作为缓存。由于Redis具有支撑高并发的特性,通常能起到加速读写和降低后端压力的作用。web端的大多数请求都是从Redis中获取的数据,如果Redis中没有需要的数据,则会从MySQL中去获取,并将获取到的数据写入redis。

1.2.2 计数

Redis中有一个字符串相关的命令incr key,incr命令对值做自增操作,返回结果分为以下三种情况:

  • 值不是整数,返回错误

  • 值是整数,返回自增后的结果

  • key不存在,返回1

比如文章的阅读量,视频的播放量等等都会使用redis来计数,每播放一次,对应的播放量就会加1,同时将这些数据异步存储到数据库中达到持久化的目的。

1.2.3 共享Session

在分布式系统中,用户的每次请求会访问到不同的服务器,这就会导致session不同步的问题,假如一个用来获取用户信息的请求落在A服务器上,获取到用户信息后存入session。下一个请求落在B服务器上,想要从session中获取用户信息就不能正常获取了,因为用户信息的session在服务器A上,为了解决这个问题,使用redis集中管理这些session,将session存入redis,使用的时候直接从redis中获取就可以了。

1.2.4 限速

为了安全考虑,有些网站会对IP进行限制,限制同一IP在给定的一段时间内访问次数不能超过n次。

在redis中保存一个count值,key为user:$ip,value为该ip访问的次数,第一次设置key的时候,设置过期时间为给定时间。

count加1之前,判断是否key是否存在,不存在的话,有两种情况:1、该ip未访问过;2、该ip访问过,但是key已经过期了。那么此时需要再次设置一次expires。

如果用户访问的时候,判断count的值是否大于上限,如果低于上限,就处理请求,否则就拒绝处理请求。

2. 哈希

Redis中哈希类型是指一个键值对的存储结构,其中键不能重复,值对应一个map。

可以用来表示一个表中的一列数据, 其中键为主键,值也就是map的key可以作为列名, map的value可以作为列的值.

比如要表示这样的一条结构化记录:

记录的主键: user:1000

username birthyear verified
antirez 1977 1

使用Redis中的哈希类型存储方式如下:

> hmset user:1000 username antirez birthyear 1977 verified 1
OK
> hget user:1000 username
"antirez"
> hget user:1000 birthyear
"1977"
> hgetall user:1000
1) "username"
2) "antirez"
3) "birthyear"
4) "1977"
5) "verified"
6) "1"

> hmget user:1000 username birthyear no-such-field
1) "antirez"
2) "1977"
3) (nil)     # 当key不存在时返回 nil

hincrby 可以对哈希表中的数据进行修改

> hincrby user:1000 birthyear 10
(integer) 1987
> hincrby user:1000 birthyear -10
(integer) 1977

You can find the full list of hash commands in the documentation.

2.1 底层数据结构

哈希类型的底层数据结构有两种:

ziplist(压缩列表):当哈希类型元素个数小于hash-max-ziplist-entries配置(默认512个)同时所有值都小于hash-max-ziplist-value配置(默认64字节)时使用。ziplist使用更加紧凑的结构实现多个元素的连续存储,所以比hashtable更加节省内存。hashtable(哈希表):当ziplist不能满足要求时,会使用hashtable。

2.2 使用场景

由于hash类型存储的是一个键值对,比如数据库有以下一个用户表结构:

表名为user,其中一个记录如下:

id username birthyear verified
1000 antirez 1977 1

将以上信息存入redis,用:作为key:

> hmset user:1000 username antirez birthyear 1977 verified 1

哈希可以让一个Map结构(一系列的键值对)和一个表的主键关联拿起来, 对这样的具有多个字段的记录使用哈希存储会比字符串更加方便直观.

3. 列表

列表类型用来存储多个有序的字符串,一个列表最多可以存储2^32-1个元素,列表的两端都可以插入和弹出元素。

列表的用法

可以列表看成一个数组构成的双端队列, 那么首先我们约定索引小的元素在左边, 索引大的元素在右边.rpush命令表示向数组的最右侧插入元素, lpush表示想数组的最左侧插入元素.

> rpush mylist A
(integer) 1
> rpush mylist B
(integer) 2
> lpush mylist first
(integer) 3
> lrange mylist 0 -1
1) "first"
2) "A"
3) "B"

即:

> rpush mylist A:           1) "A" -
> rpush mylist B            1) "A" -> 2) "B"
> lpush mylist first         1) "first" -> 2) "A" -> 3) "B"

lrange 可以查询一段范围内的元素, 元素索引从0开始, 负数表示倒序的第几个

> rpush mylist 1 2 3 4 5 "foo bar"
9                           # 返回总元素数量
> lrange mylist 0 -1          # 列出所有元素
first
A
B
1
2
3
4
5
foo bar
> lrange mylist 1 8            # 效果一样
first
A
B
1
2
3
4
5
foo bar

list也具有栈数据结构类似的pop命令, 不同的是可以选择从左边或者右边弹出元素并返回.

> rpush mylist a b c
3
> rpop mylist
c
> rpop mylist
b
> rpop mylist
a
> rpop mylist
null

同样, 如果要从左边弹出则可以使用LPOP命令.

> rpush mylist a b c
6
> del mylist
1
> rpush mylist a b c
3
> lpop mylist
a
> lpop mylist
b
> lpop mylist
c
> lpop mylist
null

Capped lists - 带上限的列表

ltrim的使用类似lrange,只不过它的作用是将指定区间的元素作为新的列表返回.

> rpush mylist 1 2 3 4 5
(integer) 5
> ltrim mylist 0 2
OK
> lrange mylist 0 -1
1) "1"
2) "2"
3) "3"

上面的LTRIM命令告诉Redis仅从索引0到2列出列表元素,其他所有内容都将被丢弃。将PUSH + TRIM命令搭配可以很容易维护一个有限容量的队列, 以便添加新元素并丢弃超出限制的元素.

LPUSH mylist <some element>
LTRIM mylist 0 999

上面的组合添加了一个新元素,并且仅将1000个最新元素纳入列表。使用LRANGE可以访问最重要的1000个元素,而无需记住旧的数据。

注意:LRANGE从技术上讲是O(N)命令,但朝列表的开头或结尾访问较小范围的元素可以近似为O(1)操作。

3.1 底层数据结构

列表的底层数据结构有两种:

ziplist(压缩列表):当哈希类型元素个数小于list-max-ziplist-entries配置(默认512个)同时所有值都小于list-max-ziplist-value配置(默认64字节)时使用。ziplist使用更加紧凑的结构实现多个元素的连续存储,所以比hashtable更加节省内存。linkedlist(链表):当ziplist不能满足要求时,会使用linkedlist。

3.2 使用场景

3.2.1 消息队列

列表用来存储多个有序的字符串,既然是有序的,那么就满足消息队列的特点。使用lpush + rpop或者rpush + lpop实现消息队列。

除此之外,redis支持阻塞操作,在弹出元素的时候使用阻塞命令来实现阻塞队列。

列表具有一项特殊功能,使其适合于实现队列,并且通常用作进程间通信系统的构建块:阻止操作。

想象一下,您想通过一个流程将项目推入列表,然后使用不同的流程来对这些项目进行某种处理工作。这是通常的生产者/使用者设置,可以通过以下简单方式实现:

  • 为了将项目推送到列表中,生产者调用LPUSH。
  • 为了从列表中提取/处理项目,消费者调用RPOP。

但是,有时列表可能为空,没有任何要处理的内容,因此RPOP仅返回NULL。在这种情况下,消费者被迫等待一段时间,然后使用RPOP重试。这称为轮询,这种情况下这不是一个好主意,因为它有几个缺点:

  1. 强制Redis和客户端处理无用的命令(列表为空时的所有请求将无法完成任何实际工作,它们只会返回NULL)。
  2. 由于消费者在收到NULL之后会等待一段时间,因此会增加项目处理的延迟。

所以,命令BRPOP和BLPOP就是带有堵塞功能的RPOP和LPOP,作用是能够如果列表是空的就堵塞,如果在指定的超时时间到达前列表有了新的数据则返回新数据,否则超过超时时间则直接返回.

这是BRPOP调用的示例:

> brpop tasks 5
1) "tasks"
2) "do_something"

这意味着:“等待列表中的元素tasks的最后一个元素,但如果5秒钟后没有可用元素,则返回”。

请注意,您可以将0用作超时来永远等待元素,还可以指定多个列表,而不仅仅是一个列表,以便同时等待多个列表,并在第一个列表收到一个元素时得到通知。

注意:

  1. 客户端以有序方式提供服务:第一个阻塞等待列表的客户端,在某个元素被其他客户端推送时首先提供服务,依此类推。
  2. 返回值与RPOP相比有所不同:它是一个包含两个元素的数组,因为它还包含键的名称,因为BRPOP和BLPOP能够阻止等待来自多个列表的元素。
    1. 如果达到超时,则返回NULL。

关于列表和阻止操作,建议了解以下内容:

  • 使用 LMOVE 可以实现循环队列.
  • 相对应的堵塞版本命令就是 BLMOVE.
3.2.2 栈

由于列表存储的是有序字符串,满足队列的特点,也就能满足栈先进后出的特点,使用lpush + lpop或者rpush + rpop实现栈。

3.2.3 文章列表

因为列表的元素不但是有序的,而且还支持按照索引范围获取元素。因此我们可以使用lrange命令分页获取文章列表

> lrange key 0 9

4. 集合

集合类型也可以保存多个字符串元素,与列表不同的是,集合中不允许有重复元素并且集合中的元素是无序的。一个集合最多可以存储2^32-1个元素。可以对集合使用SADD命令添加新的元素。还可以对集合进行许多其他操作,例如测试给定元素是否已存在,执行多个集合之间的交集,并集或求差集等等。

> sadd myset 1 2 3              # set::add
(integer) 3
> smembers myset
1. 3                            # not ordered
2. 1
3. 2

> sismember myset 3              # set::is_member
(integer) 1                     # 3 is member
> sismember myset 30 
(integer) 0                     # 30 is not member

提取元素的命令称为SPOP,对于建模某些问题非常方便。例如,为了实现基于Web的扑克游戏,您可能需要用一组字符来代表您的套牌。扑克牌有四种花色, Clubs(梅花),Diamond(方块),Heart(红桃),Spade(黑桃), 使用首字母作为前缀表示花色,则一副扑克牌我们可以使用集合表示:

>  sadd deck C1 C2 C3 C4 C5 C6 C7 C8 C9 C10 CJ CQ CK
   D1 D2 D3 D4 D5 D6 D7 D8 D9 D10 DJ DQ DK H1 H2 H3
   H4 H5 H6 H7 H8 H9 H10 HJ HQ HK S1 S2 S3 S4 S5 S6
   S7 S8 S9 S10 SJ SQ SK
   (integer) 52

现在我们要为每个玩家提供5张卡片。该SPOP命令删除一个随机元素,将其返回到客户端,所以在这种情况下完美运行。

但是,如果我们直接操作deck集合,那么在游戏的下一场比赛中,我们将需要再次填充纸牌。因此,首先我们可以将deck集合复制到新集合game:1:deck中,用于开始第一局游戏。

这可以使用SUNIONSTORE来完成,SUNIONSTORE通常执行多个集合之间的联合,并将结果存储到第一个集合中。语法:

SUNIONSTORE destination key [key ...]

但是,由于单个集合的并集就是它本身,我可以使用以下命令复制我的卡组:

> sunionstore game:1:deck deck
(integer) 52

现在,我准备为第一位玩家提供五张牌:

> spop game:1:deck
"C6"
> spop game:1:deck
"CQ"
> spop game:1:deck
"D1"
> spop game:1:deck
"CJ"
> spop game:1:deck
"SJ"

Redis 的一个命令可以返回集合中元素的数量。在集合理论中元素数量也称为_集合_的基数(cardinality),因此Redis的这个命令叫做SCARD。

> scard game:1:deck
(integer) 47

数学原理:52-5 = 47。

当您只需要获取随机元素而不将其从集合中删除时,可以使用SRANDMEMBER命令。它还具有返回重复元素和非重复元素的功能。

4.1 底层数据结构

集合类型的底层数据结构有两种:

intset(整数集合):当集合中的元素都是整数且元素个数小于set-max-intset-entries配置(默认512个)时,redis会选用intset来作为集合的内部实现,从而减少内存的使用。hashtable(哈希表):当intset不能满足要求时,会使用hashtable。

4.2 使用场景

4.2.1 用户标签

集合非常适合表示对象之间的关系。例如,我们可以轻松地使用集合来实现标签功能。

对这个问题进行建模的一种简单方法是为我们要标记的每个对象设置一个集合。该集合包含与对象关联的标签的ID。

以新闻文章来举例。如果ID为1000的新闻带有标签1、2、5和77,实现标签功能需要实现:

  1. 则使用集合可以将这些标签ID与新闻项相关联:
> sadd news:1000:tags 1 2 5 77
(integer) 4
  1. 反过来我们还需要将给定标签关联到所有新闻的列表:
> sadd tag:1:news 1000
(integer) 1
> sadd tag:2:news 1000
(integer) 1
> sadd tag:5:news 1000
(integer) 1
> sadd tag:77:news 1000
(integer) 1

以上2个步骤应放在一个事务中.

有了以上关系后, 要获取给定新闻ID的所有标签很简单:

> smembers news:1000:tags
1. 5
2. 1
3. 77
4. 2

也可以给定标签查询所有包含该标签的新闻

> smembers tag:id:news
... results here ...

注意:如果是完整的工程,还需要有完整的标签表结构和完整的新闻表结构,例如Redis的哈希数据类型,可以将标签ID映射到标签名称, 将新闻ID映射到新闻名称上。

还有其他一些非常简单的操作,使用正确的Redis命令仍然很容易实现。例如,我们可能需要包含标签1、2、10和27的所有对象的列表。我们可以使用SINTER命令执行此操作,该命令执行不同集合之间的交集。我们可以用:

> sinter tag:1:news tag:2:news tag:10:news tag:27:news
... results here ...

除了交集之外,您还可以执行并集,求差,提取随机元素等等。

4.2.2 抽奖功能

集合有两个命令支持获取随机数,分别是:

随机获取count个元素,集合元素个数不变

> srandmember key [count]

随机弹出count个元素,元素从集合弹出,集合元素个数改变

> spop key [count]

用户点击抽奖按钮,参数抽奖,将用户编号放入集合,然后抽奖,分别抽一等奖、二等奖,如果已经抽中一等奖的用户不能参数抽二等奖则使用spop,反之使用srandmember。

5. 有序集合

有序集合(sorted-set, zset)是集合和哈希表的结合,这是因为在有序集合也属于集合,和集合一样不能有重复元素。但是有序集合可以排序,它给每个元素设置一个score的浮点值作为排序的依据。最多可以存储2^32-1个元素。

排序规则:

  • 如果A和B是两个 score 不同的元素,如果 A.score > B.score,则有 A>B。
  • 如果A和B的score完全相同,那么如果A字符串在字典序上大于B字符串,则有A>B。A和B字符串不能相等,因为有序集合不能保存重复的key。

下面使用zadd将黑客信息添加到有序集合里, 其中出生日期作为排序的score值:

> zadd hackers 1940 "Alan Kay"
(integer) 1
> zadd hackers 1957 "Sophie Wilson"
(integer) 1
> zadd hackers 1953 "Richard Stallman"
(integer) 1
> zadd hackers 1949 "Anita Borg"
(integer) 1
> zadd hackers 1965 "Yukihiro Matsumoto"
(integer) 1
> zadd hackers 1914 "Hedy Lamarr"
(integer) 1
> zadd hackers 1916 "Claude Shannon"
(integer) 1
> zadd hackers 1969 "Linus Torvalds"
(integer) 1
> zadd hackers 1912 "Alan Turing"
(integer) 1

根据生日先后排序

> zrange hackers 0 -1
1) "Alan Turing"
2) "Hedy Lamarr"
3) "Claude Shannon"
4) "Alan Kay"
5) "Anita Borg"
6) "Richard Stallman"
7) "Sophie Wilson"
8) "Yukihiro Matsumoto"
9) "Linus Torvalds"

根据生日先后倒序排序

> zrevrange hackers 0 -1
1) "Linus Torvalds"
2) "Yukihiro Matsumoto"
3) "Sophie Wilson"
4) "Richard Stallman"
5) "Anita Borg"
6) "Alan Kay"
7) "Claude Shannon"
8) "Hedy Lamarr"
9) "Alan Turing"

zrange或者zrevrange后面加上WITHSCORES可以同时返回score数值,如:

> zrange hackers 0 -1 withscores
1) "Alan Turing"
2) "1912"
3) "Hedy Lamarr"
4) "1914"
5) "Claude Shannon"
6) "1916"
7) "Alan Kay"
8) "1940"
9) "Anita Borg"
10) "1949"
11) "Richard Stallman"
12) "1953"
13) "Sophie Wilson"
14) "1957"
15) "Yukihiro Matsumoto"
16) "1965"
17) "Linus Torvalds"
18) "1969"

对排序的区间进行操作,比如找出出生日期早于等于1950年龄的记录

> zrangebyscore hackers -inf 1950 # range by score [-infinite,1950]
1) "Alan Turing"
2) "Hedy Lamarr"
3) "Claude Shannon"
4) "Alan Kay"
5) "Anita Borg"

再比如删除生日区间在1940到1060之间的记录,并返回删除的记录个数

> zremrangebyscore hackers 1940 1960 # remove range by score
(integer) 4

获取"Anita Borg"的生日排名:

> zrank hackers "Anita Borg"
(integer) 4         # 正数第5

如果要获取"Anita Borg"的生日倒序排名可以使用zrevrank命令。

5.1 底层数据结构

有序集合类型的底层数据结构有两种:

ziplist(压缩列表):当有序集合的元素个数小于list-max-ziplist-entries配置(默认128个)同时所有值都小于list-max-ziplist-value配置(默认64字节)时使用。ziplist使用更加紧凑的结构实现多个元素的连续存储,更加节省内存。skiplist(跳跃表):当不满足ziplist的要求时,会使用skiplist。

5.2 使用场景

5.2.1 排行榜

用户发布了n篇文章,其他人看到文章后给喜欢的文章点赞,使用score来记录点赞数,有序集合会根据score排序。流程如下

用户发布一篇文章,初始点赞数为0,即score为0

zadd user:article 0 url://a
(integer) 0
zadd user:article 0 url://b
(integer) 0
zadd user:article 0 url://c
(integer) 0

有人给文章点赞,递增1

zincrby user:article 1 url://a
(integer) 1
zincrby user:article 1 url://a
(integer) 2
zincrby user:article 1 url://a
(integer) 3
zincrby user:article 1 url://b
(integer) 1
zincrby user:article 1 url://c
(integer) 1
zincrby user:article 1 url://c
(integer) 2

查询点赞前三篇文章(倒序排序)

> zrevrange user:article 0 -1
1) "url://a"    # score=3
2) "url://c"    # score=2
3) "url://b"    # score=1

查询点赞后三篇文章(正序排序)

> zrange user:article 0 -1
1) "url://b"      # score=1
2) "url://c"      # score=2
3) "url://a"      # score=3

5.2.2 延迟消息队列

下单系统,下单后需要在15分钟内进行支付,如果15分钟未支付则自动取消订单。将下单后的十五分钟后的时间作为score,订单作为value存入redis,消费者轮询去消费,如果消费订单的时间大于等于这笔记录的score,则将这笔记录移除队列,即取消订单。

总结

在开发中,字符串类型是用的最多的数据类型,导致我们忽视了redis的其他四种数据类型,在具体场景下选择具体的数据类型对提升redis性能有非常大的帮助。redis虽然支持消息队列的实现,但是并不支持ack。所以redis实现的消息队列不能保证消息的可靠性,除非自己实现消息确认机制,不过这非常麻烦,所以如果是重要的消息还是推荐使用专门的消息队列去做。

注:另外可以利用Redis的Java客户端Jedis实现分布式锁。加锁实际上就是在redis中,给指定客户端的Key键设置一个值,为避免死锁,并给定一个过期时间。解锁的过程就是将指定客户端的Key键删除。但是实际上要实现真正好用且健壮的分布式锁是比较复杂的,一般会使用Redisson、zookeeper或者DataBase来实现。

Views: 174