Java集合框架

集合框架是 Java 中最重要的内容之一。无论是最基本的 Java SE 应用程序开发,还是企业级的 Java EE 程序开发,集合都是开发过程中常用的部分。

1 集合的基本概念

首先,什么是集合呢?
集合是一种对象,只不过这种对象的功能,是储存和管理多个对象。例如,我们生活中的“抽屉”对象,抽屉就是用来放东西的,也就是说,“抽屉”这个对象的功能,就是用来储存和管理多个对象的。
那是不是除了集合之外,就没有别的管理多个对象的方式了呢?不是。我们之前学到的
数组,就能够完成储存和管理多个对象的功能。

那使用数组管理和储存多个对象,有什么问题呢? 看下面这个需求:

  1. 创建一个长度为 3 的字符串数组,在数组中放入“zhang3”,“li4”,“wang5”这三个字符串。

  2. 在下标为 1 的位置插入“zhao6”字符串(这意味着需要进行数组扩容)

  3. 删除“li4”这个字符串。

上面这段需求,用数组怎么实现呢?

参考实现代码如下:

public class TestArray {
    public static void main(String args[]){ 
        String[] names = new String[3]; names[0] = "zhang3";
        names[1] = "li4"; names[2] = "wang5";

        //插入 zhao6 之前需要扩容
        String[] newNames = new String[names.length * 2]; for(int i = 0; i<names.length; i++){
        newNames[i] = names[i];
        }
        names = newNames;

        //插入(不使用 for 循环,而直接赋值)
        names[3] = names[2]; names[2] = names[1]; names[1] = "zhao6";

        //删除(不使用 for 循环)
        names[2] = names[3];
    }
}

可以看出,用数组也可以实现相应的扩容、插入、删除等操作。但是,是用数组进行这些相关操作,却非常的不方便,需要撰写大量的基础代码。这些代码繁琐、重复,而且容易出错(很有可能产生数组下标越界异常等),有没有办法把程序员从这种繁重的劳动中解放出来呢?

我们可以把数组、以及对数组相关的操作封装在一个类中。例如,我们封装一个 MyList类:

public class MyList {
    //data 用来保存数组数据
    private Object[] data;
    //index 保存有效元素的个数
    private int index;
    //初始数组长度是 5,有效元素个数为 0 
    public MyList(){
        data = new Object[5]; index = 0;
    }
    //把 value 元素放到末尾 如果 data 数组已满则自动扩充
    public void add(Object value){
    …
    }
    //把 value 元素插入在 pos 位置 如果 data 数组已满则自动扩充
    public void add(int pos, Object value){
    …
    }
    //删除 pos 位置的元素
    public void delete(int pos){
    …
    }

    //获得下标为 pos 的元素
    public Object get(int pos){
    …

    }
    //获得有效元素的个数public int size(){
    …
    }
    //判断数组中是否包含 obj 对象
    //如果存在则返回 true
    //否则返回 false
    public boolean contains(Object obj){
    …
    }
}

注意几个要点。

  1. 为了能够让 MyList 类更通用,能够保存 Java 中任何一种对象,我们把数据类型设为 Object 类型。由于 Object 类型是Java 中所有类型的父类,因此可以把任何对象都赋值给 Object 类型的引用,也就是说,能够把任何一种对象都放入 Object 数组。如果遇到基本类型的数据,也能将数据转换为包装类对象,同样可以放入 Object 数组。
  2. MyList 类有一个属性 index,这个属性用来保存有效元素的个数。例如,刚开始的时候,创建了一个长度为 5 的 Object 类型数组,但是这相当于有 5 个元素的空间。但是刚创建的时候,数组中并没有存入有价值的数据,因此有效元素的个数为 0 个,index 值也为0。再举一个例子,假设在一个长度为 10 的数组中,存入了 10 个元素。之后,调用了一次delete 方法,此时,由于删掉了一个元素,因此有效元素的个数变为 9 个。虽然有效元素的个数变少了,但是数组的长度并没有减小,数组的长度依然是 10。利用 index 属性,就可以判断数组是不是已经满了(如果 index 等于 data.length,则意味着数组满了)。在执行插入操作时,如果发现数组已满,则自动完成数组长度的扩充。
  3. MyList 中,封装了数据 data,并且封装了跟数据相关的操作,例如对数组进行增加、删除和插入等操作。这样,我们就把数组这种数据,和对数组的基本操作封装在了一起,从而再遇到数组的一些插入和删除操作时,可以不用重新实现复杂的数组插入和删除操作,而直接利用 MyList 类中封装的函数。这样,通过封装 MyList 类,减少了程序员的工作量,也提高了代码的重用性。

例如,利用 MyList 改写之前那个数组的练习,代码下可以修改如下:

public class TestMyList {
    public static void main(String args[]){ MyList list = new MyList();
        //初始化
        list.add("zhang3");
        list.add("li4");
        list.add("wang5");

        // 插 入 zhao6 list.add(1, "zhao6");

        //删除 li4

        list.delete(2);

    }
}

可以看到,利用了 list 的 add 和 delete 方法,可以让程序员省略自己实现数组插入删除的麻烦。也就是说,MyList 封装了数组的插入和删除操作,让程序员可以直接调用而不用自己重新实现。
完整的 MyList 代码如下:

public class MyList {
    //data 用来保存数组数据
    private Object[] data;
    //index 保存有效元素的个数
    private int index;

    //初始数组长度是 5,有效元素个数为 0 public MyList(){
    data = new Object[5]; index = 0;
    }

    //把 value 元素放到末尾
    public void add(Object value){
        if(index == data.length) this.expand(); data[index] = value;
        index++;
    }

    //把 value 元素插入在 index 位置
    public void add(int pos, Object value){ if(index == data.length) this.expand(); for(int i = index; i>pos; i--){
        data[i] = data[i-1];
        }
        data[pos] = value; index++;
        }

        //删除 index 位置的元素
        public void delete(int pos){ for(int i=pos;i<index-1;i++){
        data[i] = data[i+1];
        }
        index--;
        }

        //获得有效元素的个数public int size(){
        return index;
    }

    //判断数组中是否包含 obj 对象
    //如果存在则返回 true
    //否则返回 false
    public boolean contains(Object obj){ for(int i = 0; i<index; i++){
        if (data[i].equals(obj)) return true;
        }
        return false;
        }
        //获得下标为 pos 的元素
        public Object get(int pos){ return data[pos];
    }

    private void expand(){
        Object[] newArray = new Object[data.length * 2]; for(int i = 0; i<data.length; i++){
        newArray[i] = data[i];
        }
        data = newArray;
    }
}

2 集合框架概览

类似于 MyList 这样的类,其实,Sun 公司已经为我们写好了,完全不需要我们自己实现。这就是 Sun 公司提供的集合框架。对于我们来说,重要的不是如何实现这些类,而是如何使用 Sun 公司提供给我们的集合类。
集合就是 Sun 公司为程序员写的很多类。这些类用来储存和管理多个对象。当然,对于管理多个对象来说,管理的方式和特点多种多样。对不同的管理方式会有不同的类来实现。将这些集合类提炼出共性,就能够提炼出很多不同的接口。这些包含着共性的接口,就是我们学习集合重点要掌握的内容。
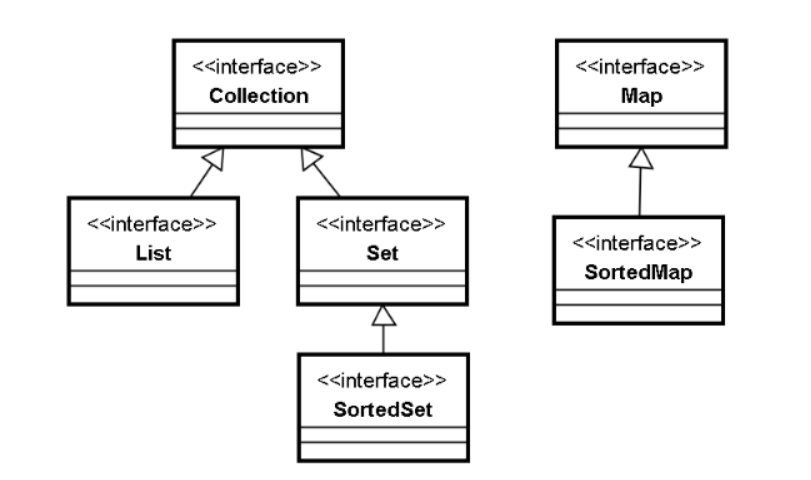
下面就是 Java 集合框架中,几个主要的接口:
file

上图是 Java 集合框架中主要的接口。我们分别对每个接口进行描述。

  1. Collection 接口。这个接口的特点是:元素是 Object。换而言之,Collection 接口所有的子接口,以及其实现类,所管理的元素单位都是对象。
  2. Map 接口。与 Collection 接口对应,Map 接口所管理的元素不是对象,而是“键值对”。什么是键值对呢?“键”和“值”各是一个对象,这两个对象之间,存在着对应的关系,我们可以通过键对象,来找到对应的值对象。在 Map 中,键对象是唯一的,不可重复的,而键对象所对应的值对象是可以重复的。
    例如,每隔四年,都会举办一次世界杯,经过艰苦的捉对厮杀,最终会有一个世界杯冠军产生。这样,举办世界杯的年份,和世界杯冠军,组成了一个对应的关系。上面所说的对应的关系,就是“键值对”的关系。值可以重复,但是键却是唯一的。例如,世界杯举办年份和世界杯冠军的对应关系中,键是世界杯举办的年份,而值是世界杯冠军的获得者。世界杯举办年份这个键不可能重复。例如,2002 年世界杯冠军为巴西队,则“2002—巴西”形成一个键值对的关系。2002 这个键不能够重复, 因为 2002 年只有一个世界杯冠军。而巴西队在 1994 年也获得过世界杯冠军,因此
    “1994—巴西”也形成一个键值对。由此可见,值对象可以重复。
  3. Collection 有两个子接口,其中一个子接口为 List 接口。List 接口的特点,是 List 中元素有顺序,可以重复。所谓元素有顺序,指的是说,几个元素放入 List 的先后顺序,就是这几个元素在 List 中的排列顺序。通过集合中元素的顺序,我们可以区分出集合中第 1 个元素,第 2 个元素……
  4. Collection 还有一个子接口 Set 接口。Set 接口的特点是元素不可以重复,无顺序。例如,在一家饭店中,有“蒸羊羔”、“蒸熊掌”、“蒸鹿尾”三道菜。对于厨师来说, 他会做这三道菜,可以认为他会做的菜放在一个 Set 集合中,顾客可以从这个集合中挑选若干道菜。在这个集合中,没有元素重复(不会有个厨师跟顾客说,我会做蒸羊羔,还有蒸熊掌,还有蒸羊羔、还有蒸熊掌„„),并且元素的顺序也不重要,没有第 1 个第 2 个之分。
  5. Set 接口有个子接口 SortedSet。这个接口具有 Set 的特点,其中的元素不能够重复。
    但是这个接口与 SortedSet 不同的地方在于,这个接口中的元素会按照一定的排序规则,自动对集合中的元素排序。
  6. Map 有个子接口 SortedMap。这个接口与 Map 一样,管理的元素是键值对,键不能重复,值可以重复。所不同的是,在这个接口中,键对象会按照一定的排序规则, 自动排序。

下面我们就针对这几种接口,分别进行学习和讨论。
要掌握每种集合接口,就要重点掌握集合接口的这几个方面:
1、 接口的特点
2、 接口中定义的基本操作
3、 该集合如何遍历
4、 接口的不同实现类,以及实现类之间的区别

3 Collection

1、 接口特点
Collection 接口的特点是元素是 Object。遇到基本类型数据,需要转换为包装类对象。
2 、基本操作
Collection 接口中常用的基本操作罗列如下:

  • boolean add(Object o)
    这个操作表示把元素加入到集合中。add 方法的返回值为 boolean 类型。如果元素加入集合成功,则返回 true,否则返回 false。
  • boolean contains(Object o)
    这个方法判断集合中是否包含了 o 元素。
  • boolean isEmpty()
    这个方法判断集合是否为空。
  • Iterator iterator()
    这个方法很重要,可以用来完成集合的迭代遍历操作。
  • boolean remove(Object o)
    remove 方法表示从集合中删除 o 元素。返回值表示删除是否成功。
  • void clear()
    clear 方法清空集合。
  • int size()
    获得集合中元素的个数。

3、 Collection 如何遍历Collection 的实现类
Collection 没有直接的实现类。也就是说,某些实现类实现了 Collection 接口的子接口, 例如 List、Set,这样能够间接的实现 Collection 接口。但是没有一个实现类直接实现了Collection 接口却没有实现其子接口。
正因为如此,Collection 如何遍历,我们会在讲解其子接口时详细阐述。

4 List

4.1 List 特点和基本操作

List 接口的特点:元素是对象,并且元素有顺序,可以重复。
可以把 List 当做是一个列表。例如,如果让我们列出历任美国总统,我们必然会按照顺序说出每一任的人名,对于连任的总统,在这个列表中就会出现多次。这样的结构就是一个典型的 List:元素有顺序,并且可以重复出现。
对于 List 而言,元素的所谓“顺序”,指的是每个元素都有下标。因此,List 的基本操作,除了从 Collection 接口中继承来的之外,还有很多跟下标相关的操作。基本操作罗列如下:

  • boolean add(Object o) / void add(int index, Object element)
    在 List 接口中有两个重载的 add 方法。第一个 add 方法是从 Collection 接口中继承而来的,表示的是把 o 元素加入到 List 的末尾;第二个 add 方法是 List 接口特有的方法,表示的是把元素 element 插入到集合中 index 下标处。
  • Object get(int index) / Object set(int index, Object element)
    get 方法获得 List 中下标为 index 的元素,set 方法把 List 中下标为 index 的元素设置为 element。
    利用这两个方法,可以对 List 根据相应下标进行读写。
  • int indexOf(Object o)
    这个方法表示在 List 中进行查找。如果 List 中存在 o 元素,则返回相应的下标。如果 List 中不存在 o 元素,则返回-1。
    这个方法可以用来查找某些元素的下标。

除此之外,List 接口中还有一些诸如 size、clear、isEmpty 等方法,这些方法与介绍 Collection 接口中的相应方法含义相同,在此不再赘述。

4.2 遍历

首先,为了能使用 List 接口,必须先简单介绍一个 List 接口的实现类:ArrayList。这个类使用数组作为底层数据结构,实现了 List 接口,我们使用这个类来演示应该如何对 List 进行遍历。
由于 List 接口具有下标,因此我们用类似对数组遍历的方式,采用 for 循环对 List 进行遍历。示例代码如下:

public class TestArrayList {
public static void main(String args[]){ 
        List list = new ArrayList(); list.add("hello");
        list.add("world");
        list.add("java");
        list.add("study");

        for(int i = 0; i<list.size(); i++){ System.out.println(list.get(i));
        }

    }
}

可以看出,利用 List 接口中的 size 方法,我们可以得出集合中元素的个数,那么集合中元素的下标范围就是 0 ~ size-1 。继而我们可以通过 get 方法,根据下标获得相应的元素。利用这种方法,我们就可以遍历一个 List。
除此之外,List 接口还有另外一种遍历方式:迭代遍历。

4.2.1 迭代遍历
迭代遍历是 Java 集合中的一个比较有特色的遍历方式。这种方法被用来遍历 Collection 接口,也就是说,既可以用来遍历 List,也可以用来遍历 Set。
使用迭代遍历时,需要调用集合的 iterator 方法。这个方法在 Collection 接口中定义, 也就是说,List 接口也具有 iterator 方法。
这个方法的返回值类型是一个 Iterator 类型的对象。Iterator 是一个接口类型,接口类型没有对象,由此可知,调用 iterator 方法,返回的一定是 Iterator 接口的某个实现类的对象。这是非常典型的把多态、接口用在方法的返回值上面。
Iterator 接口表示的是“迭代器”类型。利用迭代器,我们可以对集合进行遍历,这种遍历方式即称之为迭代遍历。
例如,有如下代码:

public class TestArrayList {
    public static void main(String args[]){ 
        List list = new ArrayList(); list.add("hello");
        list.add("world");
        list.add("java");
        list.add("study");

        Iterator iter = list.iterator();
    }
}

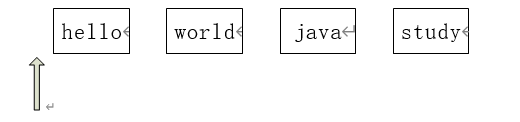
此时,在集合中有四个元素:hello、world、java、study。

在调用 list 的 iterator 方法之后,返回一个 Iterator 类型的对象。这个对象就好像一个指针,指向第一个元素之前。如下图:
file

在迭代器中定义了两个方法:

  • boolean hasNext()
    这个方法返回一个 boolean 类型,表示判断迭代器右方还有没有元素。对于上面这种情况,对迭代器调用 hasNext()方法,返回值为 true。
  • Object next()
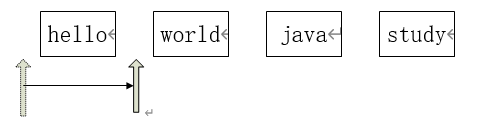
    这个方法,会把迭代器向右移动一格。同时,这个方法返回一个对象,这个对象就是迭代器向右移动时,跳过的那个对象。如下图:
    file
    调用一次 next 方法之后,迭代器向右移动一位。在向右移动的同时,跳过了“hello” 这个元素,于是这个元素就作为返回值返回。

我们可以再持续的调用 next()方法,依次返回“world”,“java”,“study”对象,直至 hasNext()方法返回 false,意味着迭代器已经指向了集合的末尾,遍历过程即结束。

利用 Iterator 接口以及 List 中的 iterator 方法,可以对整个 List 进行遍历。代码如下:

public class TestArrayList {
    public static void main(String args[]){ 
        List list = new ArrayList(); list.add("hello");
        list.add("world");
        list.add("java");
        list.add("study");
        Iterator iter = list.iterator(); while(iter.hasNext()){
        Object value = iter.next(); System.out.println(value);
    }

    }
}

迭代遍历往往是用 while 循环来实现的。利用 hasNext 方法返回值作为循环条件,判断List 后面是否还有其他元素。在循环体中,调用 next 方法,一方面把迭代器向后移动,另外一方面一一返回 List 中元素的值。

4.3 实现类

List 接口有以下几个实现类。要注意的是,这几个类都实现了 List 接口,也就是说,如果我们针对 List 接口编程的话,使用不同的实现类,编程的方式是一样的。例如,ArrayList 和 LinkedList 都实现了 List 接口,如果我们要把上一小节的程序里的实现由 ArrayList 替换成 LinkedList,只需要把这一句代码

List list = new ArrayList();

改为

List list = new LinkedList();

其余代码由于都是针对 List 接口的,因此完全不需要修改。也就是说,不管实现类是什么样子,对 List 接口的操作是一样的。这也从一个侧面反映了接口的作用:解耦合。

下面针对不同的实现类,分别进行一下介绍。

4.3.1 ArrayList 和 LinkedList

ArrayList 的特点是采用数组实现。很类似于之前我们写的 MyList 类,当然,实际的 ArrayList 类和我们写的 MyList 相比,还是复杂了很多。

用数组这样一种结构来实现 List 接口,具有以下特点:
用数组实现 List 接口,如果要查询 List 中给定下标的元素,只需要使用数组下标就可以直接查到,实现起来非常方便,而且由于数组中,元素的存储空间是连续的,因此通过下标很容易快速对元素进行定位,因此查询效率也很高。

但是,如果使用数组实现 List 接口,则必须要面对一个问题:数组的插入和删除的效率较低。例如,如果要进行数组的插入,有可能要大量移动数组的元素,有可能要进行数组的扩容从而进行大量的内存拷贝的工作。而数组的删除,同样可能意味着要移动大量的数组元素。因此,从这方面来说,数组的插入和删除操作效率比较低。
而 LinkedList 实现 List 接口时,采用的是链表的实现方式。

下面简单介绍一下链表这种数据结构。
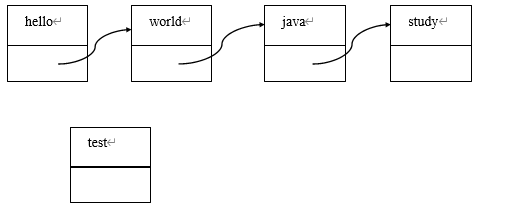
最基本的链表结构是这样的:链表由多个节点组成。每个节点分为两个部分:第一个部分用来储存链表的数据,另一个部分用来储存下一个节点的地址。如何来理解这个问题呢?有些寻宝和侦探小说里,常常有这样的情节:要打开一个宝藏,需要分散在不同地方的 n 把钥匙。我们伟大的主人公刚出场的时候,往往手上握有一条线索。通过这条线索,能够找到一个装有钥匙的盒子,并且发现,在装着钥匙的装帧精美的盒子中,会发现寻找下一把 钥匙需要的线索。就这样历经千辛万苦,最后终于获得宝藏。

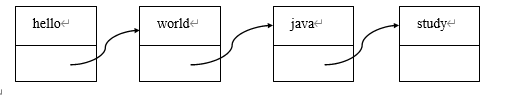
在这种情形中,如果我们把钥匙当做数据,那么每个盒子就可以当做一个节点:在节点中,一部分放着数据,另一部分指向下一个节点。也就好像是,盒子中装着钥匙,并且装着发现下一个盒子的线索。我们可以用图来表示这种情况。例如,假设有如下代码:

List list = new LinkedList(); list.add("hello");
list.add("world");
list.add("java");
list.add("study");

上面的代码创建了一个 LinkedList,在内存中的图像如下:
file
此时,如果调用 get(3)方法,则会由 hello 节点开始,先从 hello 节点找到 world 节点, 再从 world 节点找到 java 节点,再从 java 节点找到 study 节点。因此在查询方面,相对于数组直接使用下标,链表实现的 LinkedList,在查询方面效率较低。
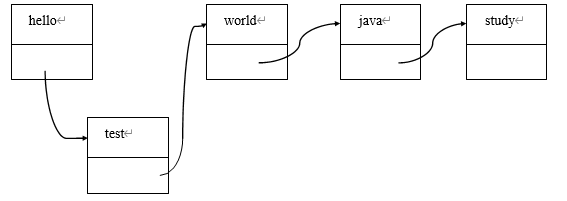
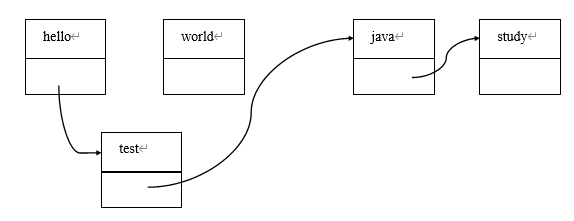
而如果要进行插入操作,LinkedList 就会有比较明显的优势:因为 LinkedList 不需要进行数据内容的复制。例如,假设运行了如下代码:
list.add(1, “test”);
则内存中会进行下面的操作:

  1. 创建一个新节点。
    file
  2. 修改 hello 和 test 的指针指向即可。
    file
    与之类似的,使用链表进行删除也只需要改动某个指针的指向即可。例如,假设运行了如下代码:
    list.delete(2);
    file

由上面的例子可知,相对使用数组实现 List,使用链表实现 List 中的插入和删除功能, 由于没有数组扩容以及移动数据等问题,因此效率要远远高于使用数组实现。

ArrayList 和 LinkedList 之间的区别如下表:

实现方式    特点

ArrayList 数组实现 增删慢,查询快
LinkedList 链表实现 增删快,查询慢

4.3.2 Vector

Vector 是JDK1.0 遗留下的产物。Vector 同样实现了 List 接口,而且也是使用数组实现。
Vector 和 ArrayList 之间的比较如下:

实现方式 特点
ArrayList 数组实现-轻量级,速度快,线程不安全
Vector 数组实现-重量级,速度慢,线程安全

这两个类实现的方式都采用数组实现,所不同的是,Vector 为了保证线程安全,采用了重量级的实现方式。在 Vector 中,所有的方法都被设计为了同步方法。这样,当多线程共同访问同一个 Vector 对象时,不会产生同步问题,但却牺牲了访问的效率。
而 ArrayList 中所有方法并没有被作成同步方法,因此访问效率较快。当然,当多线程同时访问同一个 ArrayList 对象时,可能会造成线程的同步问题。
关于线程的同步,在本书线程的章节中有更加详细的描述,请读者参考。

5 Set

5.1 Set 特点和基本操作

就像之前提到的一样,Set 接口的特点是元素不可以重复,无顺序。具体例子不再赘述。那 Set 接口有哪些基本操作呢?Set 接口中所有的操作都继承自 Collection 接口,也就是说,Set 接口没有自己特有的操作,其所有操作都来源于父接口 Collection。因此,它具有 Collection 接口中定义的那些诸如 add、remove 等方法。
特别要注意的是,由于 Set 集合中的元素没有顺序,因此 Set 集合中的元素没有下标的概念。因此,和 List 接口不同,Set 接口中没有定义与下标相关的操作。
Set 接口相关的内容请参考对 Collection 接口的描述。

5.2 遍历

与 List 接口一样,我们先介绍一个 Set 接口的实现类,HashSet。我们利用这个类来测试 Set 接口的遍历。
Set 接口中没有跟下标相关的方法,也就是说,Set 接口中没有类似 List 接口中的 get方法,因此,无法使用跟下标紧密联系的 for 循环遍历。
但是,Set 接口可以使用迭代遍历。Collection 接口中定义了 iterator 方法,因此 Set 接口中也包含了这个方法。对于 Set 集合来说(尤其是 JDK1.5 以前的版本),只能采用迭代器的方式来遍历。
示例代码如下:

public class TestSet {
public static void main(String[] args) { Set set = new HashSet(); set.add("hello");
set.add("world");
set.add("java");
//加入重复元素是,add 方法会返回 false

set.add("hello");

//迭代遍历

Iterator iter = set.iterator();
while(iter.hasNext()){
    Object value = iter.next(); System.out.println(value);
    }
}

要注意的是,迭代遍历输出的结果为:
hello java world
注意到对 set 调用了两次 add(“hello”)方法,但是输出结构只有一个 hello 字符串。同时,
注意到输出结果的排列顺序与加入 set 的顺序完全无关。这就是 Set 集合的特点:元素无顺序,不可以重复。

5.3 实现类

对于 Set 集合的基本操作,相对而言比较容易掌握。对于 Set 接口而言,比较难掌握的地方在于 Set 接口的实现类相关内容。下面这部分内容是学习 Set 接口的重点。

5.3.1 HashSet

HashSet 实现了 Set 接口,因此要求元素不可以重复。那么,HashSet 是怎么来判断元素是否可以重复的呢?
我们首先看下面这个代码的例子:

class Student{ private int age;
private String name;

public Student() {
}

public Student(String name, int age) { 
    this.name = name;
    this.age = age;
}

public int getAge() { 
    return age;
}
public void setAge(int age) { 
    this.age = age;
}

public String getName() { 
    return name;
}
public void setName(String name) { 
    this.name = name;
}
public String toString(){ 
    return name + " " + age;
}

}
public class TestStudent{
    public static void main(
        String args[]){ Set set = new HashSet();
        Student stu1 = new Student(“Tom”, 18);
        Student stu2 = new Student(“Tom”, 18);
        set.add(stu1);
        set.add(stu2); 
        System.out.println(set.size());
    }
}

看上述代码。我们创建了两个 Student 对象,这两个对象具有相同的属性。根据 Set 接口的含义,Set 集合中不应该有内容重复元素,因此我们希望调用了两次 add 方法之后,set 的长度依然为 1。然而运行结果却是 2。问题出在哪儿呢?首先来说,要判断两个对象内容是否相等,会调用对象的 equals 方法。而 Student 类中没有覆盖 equals 方法,因此 Student 类中的 equals 方法来源于 Object 类, 判断的是引用中保存的地址是否相等。显然,stu1 和stu2 这两个引用分别指向了一个 Student对象,这两个对象地址不相同,因此用 equals 方法判断,结果为 false。
为了能让 Student 类能够正确的进行判断,我们应该为 Student 类覆盖 equals 方法。示 例代码如下:

public boolean equals(Object obj) { 
    if (this == obj) return true;  
    if (obj == null) return false;
    if (getClass() != obj.getClass()) return false;
    Student stu = (Student) obj;
    if (this.age == stu.age && this.name.equals(stu.name)){ 
        return true;
    }else {
        return false;
    }
}

覆盖了 equals 方法之后,再次运行。但是,运行结果还是 2!这次问题又出在哪里呢? 这里面涉及到了 HashSet 的实现机制:Hash 算法。下面我们简单的来介绍一下 Hash 算
法的原理。
在 Object 类中,有一个 hashCode 方法,这个方法的签名如下:
public int hashCode()
这是一个 Object 类中定义的公开方法,意味着所有对象中都具有这个方法。这个方法没有参数,返回值为一个 int 类型的数值。
在我们把一个对象放到HashSet 中时,HashSet 的add 方法会调用对象的hashCode 方法。假设,我们的 HashSet 的大小为 4,为这四个位置设置下标为 0~3。内存中情况如下:

0
1
2
3

然后,假设调用 add 方法。假设我们有三个对象:str1、str2、str3 三个不同的字符串对象,假设对这三个对象调用 hashCode 方法的返回值为 96、99、100。
调用四次 add 方法如下:

set.add(str1);
set.add(str2);
set.add(str3);
set.add(str1);

在第一个 add 方法中,会调用 str1 的 hashCode 方法,返回值为 96。str1 对象在 HashSet中的位置,是根据这个整数 96 对数组长度取模,计算出来的。由于 96%4=0,因此会把 str1 放入下标为 0 的位置,如下图:

0 <- str1
1
2
3

在第二个 add 方法中,同样会调用str2 的 hashCode 方法,返回值为 99。由于 99%4=3, 因此会把 str2 放入下标为 3 的位置,如下图:

0 <- str1
1
2
3 <- str2

在第三个 add 方法中,会调用 str3 的 hashCode 方法,返回值为 100。由于 100%4=0, 但是下标为0 的位置已经有了一个str1 元素。此时,就产生了hashCode 冲突。当产生hashCode 冲突时,HashSet 会调用 equals 方法进行判断。这是,由于 str1.equals(str3)返回值为false, 这两个对象的值不相等,因此 str3 同样会被加入到 HashSet 中。示意图如下:

0 <- str1 <- str3
1
2
3 <- str2

在第四次调用 add 方法时,会再次调用 str1 的 hashCode 方法,返回值为 96。这时,由于 96%4=0,此时产生了 hashCode 冲突。而这时,HashSet 会调用 equals 方法进行判断。由于判断的结果是返回 true,因此 HashSet 认为这是重复元素,从而不会把 str1 对象再次加入Set,从而避免了重复元素。
示意图如下:

0 <- str1 <- str3
1
2
3 <- str2

从上述我们对 Hash 算法的描述中,可以看出 HashSet 只有在 hashCode 返回值冲突的时候才会调用 equals 方法进行判断。也就是说,两个对象,如果 hashCode 没有冲突,HashSet 就不会调用 equals 方法判断而直接认为这两个对象是不同的对象。
而对我们自己写的 Student 类调用 hashCode 方法时,由于 Student 类没有覆盖 Object 类中的 hashCode 方法,因此得到的返回值是 Object 类中的 hashCode 方法返回值。参考下面的代码:

Student stu1 = new Student("Tom", 18); 
Student stu2 = new Student("Tom", 18); 
System.out.println(stu1.hashCode()); 
System.out.println(stu2.hashCode()); 

程序输出结果如下:

33263331
6413875

可以看出,虽然这两个对象的值相同,并且也覆盖了 equals 方法,但是 hashCode 方法返回值并不相同。这样,HashSet 就认为这两个对象是两个不同的对象,直接把这两个对象放入 HashSet。但是这样一来,就破坏了“Set 中的元素不可重复”这个原则。
那为什么 Student 类有这个问题,而String 类没有这个问题呢?因为String 类是 Sun 公司类库的一部分,在 Sun 公司提供 String 类的时候,就为 String 类提供了正确的 hashCode方法的实现。从而保证了,相同字符串对象,调用 hashCode 方法的返回值都是相同的。 而 Student 类是我们自己写的,这个类中没有覆盖 hashCode 方法,因此调用的 hashCode方法来源于 Object 类。Object 类中的方法不能够满足我们的要求,无法保证相同的对象返回的 hashCode 相同。
那怎么解决这个问题呢?我们应该从 Student 类本身入手,应该在 Student 类中覆盖hashCode 方法。例如,在 Student 类中添加如下方法:

public int hashCode(){
    return age + name.hashCode();
}

这样,就能保证,当两个 Student 对象的age 和name 属性的值都相同时,返回的 hashCode值必定相同。因此,应当这样覆盖 hashCode:相同对象的 hashCode()返回值应当相同。

接下来考虑下面的情况。如果我们把 Student 类中的 hashCode 的覆盖写成下面的形式:
public int hashCode(){ return 0; }
这样是否能满足 hashCode 方法的要求呢?
这样的实现,从结果上来说,是对的。由于任何对象返回的 hashCode 值均为 0,因此符合之前所说的:相同对象的 hashCode 相同。但是这样的实现也有问题:由于任何情况之下返回的 hashCode 值都为 0,因此在往 HashSet 中放入对象时,每次都会产生 hashCode 的冲突,从而每次调用 add 方法都必须要调用 equals 方法比较。而第一个 hashCode 的实现,不同对象造成的 hashCode 冲突的可能性要小得多,因此调用 equals 方法的次数也会少很多。
因此,基于性能方面的考虑,不同的对象 hashCode 返回值应当尽量不同。

总结一下,如果要正常使用 HashSet 存放对象,为了保证对象的内容不重复,则要求这个对象满足:

  1. 覆盖 equals 方法。要求相同的对象,调用 equals 方法返回 true。
  2. 覆盖 hashCode 方法。要求,相同对象的 hashCode 相同,不同对象的 hashCode 尽量不同。

完整代码如下:

import java.util.*;

class Student{
    private String name; private int age;

    public Student() {
    }
    public Student(String name, int age) {
        this.name = name;
    this.age = age;
    }
    public String getName() {
        return name;
    }
    public void setName(String name) {
        this.name = name;
    }
    public int getAge() {
        return age;
    }
    public void setAge(int age) { 
        this.age = age;
    }

    public int hashCode() {
        return age + name.hashCode();
    }

    public boolean equals(Object obj) {
        if (this == obj) return true;
        if (obj == null) return false;
        if (getClass() != obj.getClass()) return false;
            Student stu = (Student) obj;
        if ( (this.age == stu.age) && (this.name.equals(stu.name)) ){
            return true;
        }else{
            return false;
        }
    }

    public String toString(){ 
        return name + " " + age;
    }
}

public class TestHashSet {
    public static void main(String[] args) { 
        Set set = new HashSet();
        set.add(new Student("Tom", 18));
        set.add(new Student("Jim", 20));
        set.add(new Student("Fred", 22));
        set.add(new Student("Tom", 18));

        Iterator iter = set.iterator(); while(iter.hasNext()){
            System.out.println(iter.next());
        }
    }
}

输出结果如下:

Fred 22
Jim 20
Tom 18

注意,add()方法被调用了四次,但是遍历 set 集合时,只读到了三个元素。

5.3.2 LinkedHashSet

HashSet 的特点是元素不可重复且元素无顺序。某些情况下,我们依然需要元素不可以重复,但是希望按照我们加入 Set 的先后顺序来加入这些元素。这个时候,我们就可以使用
LinkedHashSet。例如下面的例子:

import java.util.*;
public class TestLinkedHashSet {
    public static void main(String args[]){

        Set set = new LinkedHashSet(); set.add("hello");
        set.add("world");
        set.add("java");
        set.add("hello");

        Iterator iter = set.iterator(); while(iter.hasNext()){
        System.out.println(iter.next());
        }
    }
}

输出结果如下:

hello world java

我们可以看到,字符串的打印顺序和它们添加到 LinkedHashSet 中的顺序是一致的。同时,hello 字符串被添加了两次,但只打印了一次。
要注意的是,如果要使用 LinkedHashSet 的话,也必须正确的覆盖对象的 hashCode 和
equals 方法。

6 Map

6.1 Map 特点和基本操作

Map 接口与 Collection 接口不同,这个接口的元素是“键值对”。其中,键值对的特点

是:键不可以重复,值可以重复。
之前解释过,所谓“键值对”,可以理解成一种一一对应的关系。在这种关系中,我们可以通过“键”来找到特定的值。例如,如果把举办世界杯的年份当做键,把该年获得世界杯冠军的球队作为值,则这就形成了一个典型的键值对的关系。在这个关系中,我们可以通过年份查询对应年份的世界杯冠军,这就是“通过键,找到对应的值”的操作;并且举办世界杯的年份不会有重复,而不同年份的世界杯冠军有可能相同,这就对应着“键不可以重复, 值可以重复”。
Map 接口中的一些基本操作罗列如下:

  • Object get(Object key)
    这个方法完成的功能是,通过键对象 key,来找到相应的值对象。
  • put(Object key, Object value)
    这个方法是把一个键值对放入 Map 中。如果键不存在,则在 Map 中新增一个键值对。如果键已存在,则把新值替换旧值。例如,有如下代码:
System.out.println(map.get(“2002”)); map.put(“2002”, “Brazil”); System.out.println(map.get(“2002”)); map.put(“2002”, “China”); System.out.println(map.get(“2002”));

在第一个输出语句中,由于 Map 中不存在以 2002 作为键的键值对,因此第一个输出语句输出为 null。
之后,调用 put 方法。此时,由于 Map 中不存在 2002 这个键,因此会在 Map 中增加一个新的键值对。第二个输出语句就会输出“Brazil”。
之后,再次调用 put 方法。此时,由于在 Map 中 2002 这个键已经存在,因此会用新值“China”替换旧值“Brazil”。于是,第三个输出语句就会输出“China”。

  • remove(Object key)
    这个方法根据一个键,删除一个键值对。
  • Set keySet()
    这个方法返回所有键的集合。由于在 Map 中,键没有顺序,且不可以重复,因此所有的键对象组成的就是一个 Set。也就是说,keySet 方法返回的是一个 Set,这个
    Set 就是所有键对象的集合。
  • Collection values()
    values 方法返回类型是一个 Collection,返回的是所有值对象的集合。
  • containsKey / containsValue
    这两个方法用来判断在 Map 中键是否存在,或者值是否存在。
  • size()
    这个方法返回 Map 中键值对的个数
  • isEmpty()
    判断 Map 是否为空
  • clear()
    清空 Map
  • entrySet
    这个方法返回值类型是一个 Set 集合,集合中放的是 Map.Entry 类型。这个方法是

用来做键值对遍历的,在讲解遍历的时候还会给大家讲到。

6.2 遍历

与之前一样,在真正开始讲解遍历之前,首先先使用一个 Map 接口的实现类:HashMap。创建相应的 HashMap 对象,并放入一些初始值,如下面代码所示:

import java.util.*; 

public class TestMap {
    public static void main(String args[]){ Map map = new HashMap();

        map.put("2006", "Italy");
        map.put("2002", "Brazil");
        map.put("1998", "France");
        map.put("1994", "Brazil");
    }
}

在这个 Map 的基础上,我们开始对 Map 进行遍历。
由于 Map 管理的是键值对,因此对于 Map 而言,有多种遍历的方式:键遍历、键值遍历、利用 Map.Entry 进行键值遍历。

6.2.1 键遍历与键值遍历

键遍历指的是遍历所有的键。键遍历的实现非常简单:通过调用 Map 接口中的 keySet 方法,就能获得所有键的集合。然后,就可以像遍历普通 Set 一样遍历所有键对象的集合。键遍历参考代码如下:

Set set = map.keySet(); 
Iterator iter = set.iterator(); 
while(iter.hasNext()){
    System.out.println(iter.next());
}

键遍历输出结果如下:

2006
1998
2002
1994

可以看到,键遍历输出了集合中所有的键,并且,键并没有顺序。

在键遍历的基础上更进一步,能够遍历所有的键值对。思路如下:
利用键遍历能够遍历所有的键,而在遍历键的时候,可以使用 get 方法,通过键找到对应的值。键值遍历的参考代码如下:

Set set = map.keySet(); 
Iterator iter = set.iterator(); 
while(iter.hasNext()){
    Object key = iter.next();
    Object value = map.get(key); System.out.println(key + "--->" + value);
}

键值遍历的结果如下:

2006--->Italy 1998--->France
2002--->Brazil 1994--->Brazil

可以看到,键值遍历时能够输出键值对这种一一对应的关系。

6.2.2 值遍历

除了键遍历以及键值遍历之外,Map 接口还有一种遍历方式:值遍历。值遍历表示的是遍历 Map 中所有的值对象。与键遍历类似,我们对 Map 进行值遍历的思路也很简单:首先利用 Map 的 values()方法获得 Map 中所有值的集合。需要注意的是,values()方法返回的是一个 Collection 类型的对象,因此,应当用迭代遍历的方式,遍历这个 Collection。参考代码如下:

Collection conn = map.values(); 
Iterator iter = conn.iterator(); 
while(iter.hasNext()){
    System.out.println(iter.next());
}

这样,我们就遍历了 Map 中的所有值。输出结果如下:

Italy France Brazil Brazil
6.2.3 利用 Map.Entry 进行遍历

在 Map 接口中,有一个方法叫做 entrySet。这个方法返回一个 Set 集合,这个集合中装的元素的类型是 Map.Entry 类型。
Map.Entry 是 Map 接口的一个内部接口。这个接口封装了 Map 中的一个键值对。在这个接口中,主要定义了这样几个方法:

  • getKey() : 获得该键值对中的键
  • getValue(): 获得该键值对中的值
  • setValue():修改键值对中的值
    因此,利用 Map.Entry 也可以进行遍历。相关代码如下:

    Set set = map.entrySet(); 
    Iterator iter = set.iterator(); 
    while(iter.hasNext()){
    Map.Entry entry = (
    Map.Entry) iter.next(); 
    System.out.println(entry.getKey()   +   "-->"  +
    entry.getValue());
    }

注意,在赋值的时候,应当把 iter.next 的返回值强转成 Map.Entry 类型才可以。结果如下:
2006-->Italy 1998-->France 2002-->Brazil 1994-->Brazil
可以看到,用 Map.Entry 进行遍历,以及使用 keySet()方法以及 get()方法进行键值,这两种遍历的结果是一样的。

6.3 实现类

Map 接口主要的实现类就是 HashMap 和 LinkedHashMap,此外还有一个使用较少的 Hashtable。
HashMap 的特点是:在判断键是否重复的时候,采用的算法是 Hash 算法,因此要求作为 HashMap 的键的对象,也应该正确覆盖 equals 方法和 hashCode 方法。
LinkedHashMap 和 HashMap 之间的区别有点类似于 LinkedHashSet 和HashSet 之间的区别:LinkedHashMap 能够保留键值对放入 Map 中的顺序。
例如, 如果我们把上一小节的例子中, Map 接口的实现类由 HashMap 改为
LinkedHashMap,修改后的完整的代码如下:

import java.util.*;
public class TestLinkedHashMap {
    public static void main(String args[]){ 
        Map map = new LinkedHashMap(); map.put("2002", "Brazil");
        map.put("1998", "France");
        map.put("1994", "Brazil");
        map.put("2006", "Italy");

        Set set = map.keySet(); 
        Iterator iter = set.iterator(); 
        while(iter.hasNext()){
            Object key = iter.next(); 
            Object value = map.get(key);
            System.out.println(key + "--->" + value);
        }
    }
}

键值遍历之后,输出结果如下:
2002--->Brazil 1998--->France 1994--->Brazil 2006--->Italy
可以看到,进行键值遍历时,输出的顺序,与我们在 Map 中进行 put 的顺序相同。这就是 LinkedHashMap 的特点,这个类能够保留键值对放入 Map 中的顺序。

Hashtable 也是 Map 接口的一个实现类。HashMap 和 Hashtable 之间的区别罗列如下:

null 值处理
HashMap 轻量级,速度快,线程不安全 允许 null 作为键/值
Hashtable 重量级,速度慢,线程安全 null 作为键/值时会抛出异常

要注意,HashMap 和 Hashtable 有两方面的区别。一方面,这两个实现类一个是重量级, 一个是轻量级。这类似于 ArrayList 和 Vector 的区别,也就是说,Hashtable 中的所有方法都是同步方法,因此是线程安全的。另一方面,在于对 null 值的处理。例如,有如下代码:
Map map = new HashMap(); map.put(“2010”, null);
上面的代码创建了一个 HashMap 作为 Map 接口的实现类,并增加了一个“2010:null” 的键值对。在这个键值对中,2010 是键,null 作为值。
而如果把实现类改为 Hashtable,则上面的代码会抛出一个异常。也就是说,不允许把null 作为键值对中的键或者值。

7 Comparable 与排序

7.1 Collections 类与 Comparable

在 java.util 包中,提供了一个 Collections 的类(注意这个类的名字,与我们的 Collection 接口只相差最后一个字母 s)。这个类中所有的方法都是静态方法,也就是说,Collections类所有方法都能够通过类名直接调用。这个类为我们提供了很多使用的功能,例如:sort 方法,这个方法能够对 List 进行排序。再例如,max 方法可以找到集合中的最大值,而 min 方法可以找到集合中的最小值,等等。
调用 Collections.sort 方法,可以对一个 List 进行排序。与在接口那一章中讲述的一样, 要想对 List 进行排序,就要求 List 中的对象实现 Comparable 接口。具体应该如何实现请参考“接口”的章节。

7.2 TreeSet 与 TreeMap

Set 接口有一个子接口:SortedSet,这个接口的特点是:元素不可重复,且经过排序。这个接口有个典型的实现类:TreeSet。要注意的是,因为TreeSet 中要对对象进行排序,因此要求放入 TreeSet 接口中的对象都必须实现 Comparable 接口。

例如,在讲述接口的知识时,我们曾经介绍过如何实现 Comparable 接口。我们利用
Student 类实现 Comparable 接口。在实现 Comparable 接口时,必须要实现 compareTo 方法, 表示对学生进行排序。排序时,我们按照如下排序规则:对学生的年龄进行排序,年龄较小的学生排前面,年龄较大的学生排后面。Student 类的代码如下:

class Student implements Comparable<Student>{ 
    int age;
    String name;
    public Student() {
    }
    public Student(String name, int age) { 
        this.name = name;
        this.age = age;
    }
    public int compareTo(Student stu){ if (
        this.age > stu.age){
        return 1;
    }else if (this.age < stu.age){ return -1;
    }else {
        return 0;
    }
}
}

然后,就可以把学生对象放入 TreeSet 中。代码如下:

public class TestTreeSet {
    public static void main(String args[]) { 
        Set set = new TreeSet();
        set.add(new Student("Tom", 18));
        set.add(new Student("Jim", 17));
        set.add(new Student("Jerry", 20));

        Iterator iter = set.iterator(); 
        while(iter.hasNext()){
        Student stu = (Student) iter.next(); 
        System.out.println(stu.name + " " + stu.age);
        }
    }
}

输出结果如下:

Jim 17
Tom 18
Jerry 20

可以看出,遍历输出时,按照年龄的顺序,从小到大依次输出。这说明了在 TreeMap 内部进行排序时,使用了我们定义的 compareTo 方法比较两个元素的大小。

特别要注意的一点,TreeSet 进行比较时,会把利用 compareTo 方法比较时,返回值为 0 的两个对象,当做是相同对象。例如下面的代码:

set.add(new Student("Tom", 18));
set.add(new Student("Jim", 18));

上面的两行代码,在 set 中放入了两个对象。这两个对象用compareTo 进行比较时,由于两个对象的 age 属性相同,因此会返回 0。则 TreeSet 认为这两个元素是相同元素,所以在 TreeSet 中只保留了一个对象。
完整代码如下:

public class TestTreeSet {
    public static void main(String args[]) {

        Set set = new TreeSet(); set.add(new Student("Tom", 18));
        set.add(new Student("Jim", 18));

        Iterator iter = set.iterator(); while(iter.hasNext()){
        Student stu = (Student) iter.next(); System.out.println(stu.name + " " + stu.age);
        }
    }
}

输出结果如下:

Tom 18

可以看到,虽然调用了两次 add 方法,但两个元素被认为是相同元素,因此在 TreeSet 中只有一个元素。

与之类似的,Map 接口有一个子接口:SortedMap。这个接口的特点是:对 Map 的键进行了排序。这个接口的典型实现类是 TreeMap,如果要把某个键值对放入 TreeMap,则要求键对象必须实现 Comparable 接口。
我们把前一小节中世界杯的例子,使用TreeMap 来改写。要注意的是,在这个例子中,
Map 的键是 String 类型,这个类型是由 Sun 公司提供的,已经实现了 Comparable 接口。代码如下:

import java.util.*;
public class TestTreeMap {
    public static void main(String args[]){
        Map map = new TreeMap(); map.put("2002", "Brazil");
        map.put("1998", "France");
        map.put("1994", "Brazil");
        map.put("2006", "Italy");

        Set set = map.keySet(); Iterator iter = set.iterator(); 
        while(iter.hasNext()){
            Object key = iter.next(); Object value = map.get(key);
            System.out.println(key + "--->" + value);
        }
    }
}

运行结果如下:

1994--->Brazil 1998--->France 2002--->Brazil
2006--->Italy

可以看到,遍历 Map 时,对键进行了排序,按照键对象的排序结果,依次输出 Map 中的键值对。

8 5.0 新特性:foreach 循环

在 JDK5.0 中,Sun 公司对集合框架部分进行了比较大的修改和调整,为集合框架增加了很多新的特性。首先介绍一下一个简单的新特性:foreach 循环。
foreach 循环主要要解决的是遍历的问题。对于 List 来说,我们可以采用 for 循环遍历,
而对于 Set 而言,我们只能采用迭代遍历。相对 for 循环遍历而言,迭代遍历的代码比较繁琐和复杂。例如,对于一个 Set 而言,采用迭代遍历的代码如下:

Iterator iter = set.iterator();
while(iter.hasNext()){
    Object value = iter.next();
    System.out.println(value);
}

为了简化遍历的代码,在 5.0 中引入了 foreach 循环。基本语法如下:

for(变量 : 集合){ 循环体;
}

这段代码表示,遍历整个集合,每次迭代时都把集合中的一个元素赋值给 foreach 循环中的变量,并执行循环体。
例如,上面采用迭代遍历的代码,可以写成:

for(Object value : set){ System.out.println(value);
}

这段代码表示,遍历 set 集合,在每次迭代时把 set 集合的元素赋值给 value 变量。可以看出,使用 foreach 循环遍历,语法比迭代遍历要简洁的多。
实际上,foreach 循环遍历和迭代遍历是完全等价的。在写代码时,如果程序员使用了 foreach 循环的语法,那么 5.0 的编译器会把 foreach 循环自动的翻译成对应的迭代遍历。那么什么样的集合能够用 foreach 循环来遍历呢?在 Java5.0 中, 只要是实现了java. lang.Iterable 接口的集合对象,都能使用 foreach 方式来遍历。前面介绍的所有 Collection 接口的实现类,都符合这个特点。
此外,foreach 循环还能够用来遍历数组。例如下面的代码:

String[] ss = new String[]{“hello”, “world”, “java”}; 
for(String obj : ss){
    System.out.println(obj);
}

上面的代码演示了如何使用 foreach 循环来遍历数组。

9 5.0 新特性:泛型

泛型本身是一个非常大的话题,要彻底的掌握以及用好泛型,并不是一朝一夕的事情。在本书中,我们会介绍泛型最常用、最需要掌握的概念和语法。

在正式介绍泛型知识之前,我们首先谈一下 Java5.0 以前集合框架的缺点。在 5.0 以前,ArrayList 这个类相比直接使用数组来管理多个对象而言,具有很多优势,例如方法更多, 使用更加方便等等。但是 ArrayList 也有缺点。例如,如果定义三个类:Animal、Dog 和 Cat 类如下:

abstract class Animal{ 
    abstract public void eat();
}
class Dog extends Animal{ 
    public void eat(){
        System.out.println("dog eat bones");
    }

    public void bark(){ 
        System.out.println("wang");
    }
}

class Cat extends Animal{ 
    public void eat(){
        System.out.println("Cat eat fish");
    }
    public void miaow(){ System.out.println("miao");
    }
}

如果创建一个 Dog 类型的数组,并且对每个对象调用 bark 方法,代码如下:

Dog[] dogs = new Dog[2];
dogs[0] = new Dog();
dogs[1] = new Dog();
for(int i = 0; i<dogs.length; i++){
    dogs[i].bark();
}

由于这是一个 Dog 数组,因此数组中的每一个元素都是 Dog 类型,从而可以直接把数组中的元素赋值给一个 Dog 类型的变量。而对这个变量,则可以直接调用 bark 方法。

而如果不是一个数组,使用一个 ArrayList,同样对 ArrayList 中每个对象调用 bark 方法, 则代码如下:

List list = new ArrayList(); list.add(new Dog());
list.add(new Dog());
for(int i = 0; i<list.size(); i++){ 
    Dog d = (Dog) list.get(i);
    d.bark();
}

由于 ArrayList 的 get 方法返回的是一个 Object 类型,为了调用 bark 方法,还必须进行强制类型转换。这就是集合不如数组的第一个地方:存入集合的是 Dog 类型,而取出来的时候则变成了 Object 类型,需要进行强制类型转换。
此外,如果在 list 中调用了下面的代码:
list.add(new Cat());
这个程序在编译时没有错误,但是在运行时会产生一个 ClassCastException。这是集合不如数组的第二个地方:使用集合时,由于一个集合中能够装多个类型的对象,因此在使用时很有可能发生类型转换异常。
为什么会有这两个问题呢?原因很简单:ArrayList 为了设计的更加通用,其内部保存
数据的时候,保存数据的时候都采用的是 Object 类型。因为只有设计成这样,ArrayList 才能用来保存所有的 Java 对象。但是,如果把 ArrayList 设计成这样的话,就会造成之前的两个问题:我们无法象定义某个类型的数组那样,定义一个专门用于存放某个类型对象的集合。因此,我们称传统的集合对象是:类型不安全的。
5.0 引入的泛型机制能够很好的解决我们上面所说的问题。

9.1 泛型的基本使用

使用 5.0 的泛型机制非常简单。例如,我们希望创建一个只能用来保存 Dog 对象的 List, 可以使用如下代码:

List<Dog> list = new ArrayList<Dog>();

注意,跟原有的代码相比,在 List 接口和 ArrayList 后面,都有个后缀:。这表明,创建的 ArrayList 只能够放置 Dog 类型。此时,如果对 list 放入非 Dog 类型对象,则会产生一个编译错误,示例如下:

list.add(new Dog()); //OK list.add(new Cat()); //!编译错误

这样,就能保证 ArrayList 中所有的对象都是 Dog 类型的对象。于是,get 方法返回值就可以确定,一定是 Dog 类型,也就省略了强制类型转换的步骤。所以原有的代码就可以修改成:

for(int i = 0; i<list.size(); i++){ 
    Dog d = list.get(i);
    d.bark();
}

注意到在调用 get 方法的时候,没有进行强制类型转换。
现在我们更仔细的探讨一下上面的这段程序。在 5.0 以后的 Java 文档中,List 接口定义为:List,其中,E 就表示 List 的泛型。

上面的代码中,我们定义 list 变量的类型为 List,这就意味着,我们把 E 类型设置为 Dog 类型。在 List 中定义的 get 方法,其声明为:
E get(int index)
其返回值类型为 E。由于我们设置了 E 为 Dog 类型,因此,我们对我们定义的 list 变量调用 get 方法,其返回值类型为 Dog 类型。
对 Set 集合使用泛型的方法,和 List 接口使用泛型的方法类似,在此不再赘述。
此外,考虑 foreach 循环。如果不使用泛型的话,foreach 循环每次迭代的时候,只能确定元素是 Object 类型,因此 foreach 循环只能写成:

for(Object obj : list){
…
}

而是用了泛型以后,由于能够确定集合中元素的类型,因此 foreach 循环可以写成:

for(E e : list){
…
}
例如,上面遍历包含 Dog 的 list 的代码,就可以修改成:
```jav
```a
for(Dog d : list){ d.bark();
}

可以看出,泛型与 foreach 循环结合,大大简化了遍历集合的代码。
除了可以对 List 和 Set 使用泛型,对 Map 类型也可以使用泛型。但是要注意的是,Map 由于管理的是键值对,键有一个类型,值也有一个类型,因此 Map 的泛型需要有两个参数。示例代码如下:

Map<Integer, String> map = new HashMap<Integer, String>(); 
map.put(2002, “Brazil”);
map.put(1998, “France”); Set<Integer> set = map.keySet(); for(Integer i : set){
System.out.println(i    + “” + map.get(i) );
}

请注意,map 的 keySet 方法返回值为一个 Set类型。另外,上述代码中,map 对象的键类型被设置为 Integer,而我们在调用 put 方法的时候采用了 2002,1998 这样的 int 数据,根据 JDK5.0 中自动封箱的语法,int 类型的数据会被自动封装为Integer 类型的对象。

9.2 泛型与多态

请看下面的例子:

List<Dog> dogList = new ArrayList<Dog>(); List<Animal> aniList = dogList; //! 编译出错!

这两行代码中,第一行编译正确,第二行编译出错。
在第一行代码中,把一个 ArrayList直接赋值给一个 List类型的引用。在这个赋值过程中,类型里有多态(把 ArrayList 赋值给 List),但是泛型是一样的(均是 Dog 的泛型)。
在第二行代码中,把一个 List赋值给一个 List,这样赋值是错误的!在这个过程中,类型中没有多态(List 是相同的),而泛型有多态(一个是 Dog 的泛型,一个是 Animal 的泛型)。这句话会导致一个编译错误!
请记住这个结论:类型可以有多态,但是泛型不能够有多态!
为什么会有这么个结论呢?假设可以把 dogList 直接赋值给 aniList,则可以对 aniList调用 add 方法:
aniList.add(new Cat());
这句代码能够编译通过,因为根据泛型,add 方法接受一个 Animal 类型的参数,而 Cat 对象能够当做一个 Animal 对象。
而事实上,对象是被添加到了 dogList 当中,而这个 list 中只能存放 Dog 对象,不能存放 Cat 对象,这就出现了前后矛盾的问题。
为了避免这样的问题出现,因此,在 java 中,泛型不能有多态。不同泛型的引用之间不能相互赋值。

这个结论可以扩展到把泛型用在函数参数上。例如,写一个 playWithDog 方法如下:

public static void playWithDog(List<Dog> dogs){ 
    for(Dog d : dogs){
        d.bark();
    }
}

这个函数接受一个参数,这个参数的类型是 List类型。根据我们的结论,类型可以有多态,因此我们可以给这个函数传递一个 ArrayList类型的对象作为参数,也可以给这个函数传递一个 LinkedList类型的对象作为参数。但是,泛型上没有多态。假设有一个类 Courser 表示猎狗:
class Courser extends Dog{}
在传递参数给 playWithDog 的时候,不能够传递一个 ArrayList类型的对象作为实参。这同样是因为,不同泛型的引用之间不能相互赋值。

9.3 自定义泛型化类型

现在我们定义一个类,用来表示“一对”这个概念。如果不用泛型的话,示例代码如下:

class Pair{
    private Object valueA; private Object valueB;

    public Object getValueA() {

    return valueA;
    }

    public void setValueA(Object valueA) { 
        this.valueA = valueA;
    }

    public Object getValueB() { 
        return valueB;
    }

    public void setValueB(Object valueB) { 
        this.valueB = valueB;
    }

    }

    public class TestPair {

    public static void main(String[] args){ 
        Pair p = new Pair(); p.setValueA(new Dog()); 
        p.setValueB(new Dog());
    }
}

可以看到,Pair 类为了尽可能通用,使用了 Object 类型来保存一对值。但是这样就会有类型方面的问题,例如:
p.setValueA(new Dog()); p.setValueB(new Cat());
这样,这个代码就把一只猫和一条狗硬生生配成了一对,显然,我相信无论是猫还是狗
都不会愿意的。
为此,我们应该考虑让我们的 Pair 类具有更加安全的类型,即:要求对 Pair 类来说,
valueA 属性和 valueB 属性具有相同的类型。为此,我们可以为 Pair 类使用泛型。首先修改 Pair 类的定义:
class Pair<T>
在 Pair 类后面,写一对尖括号,表明 Pair 类要使用泛型。在尖括号中的大写字母 T 称为泛型参数,T 用来标识 Pair 的泛型类型。
然后,把 valueA 和 valueB 的声明也进行修改:
private T valueA; private T valueB;
表明 valueA 和 valueB 属性为 T 类型。
最后,把所有的方法也进行修改:

public T getValueA() { return valueA;
}

public void setValueA(T valueA) { this.valueA = valueA;
}

public T getValueB() { return valueB;
}

public void setValueB(T valueB) { this.valueB = valueB;
}

注意,set 方法的参数以及 get 方法的返回值类型,都为 T 类型。这样,使用泛型的 Pair 类就定义好了。在使用的时候,我们就可以指定泛型:
Pair<Dog> p= new Pair<Dog>();
这就指定了,对于 p 对象来说,泛型 T 被赋值为 Dog 类型。在代码中凡是出现“T” 的地方,都会被“Dog”所取代。
此时,如果对 p 调用 set 方法而给出一个不是 Dog 的类型,则会编译出错。例如:

p.setValueA(new Dog());//OK p.setValueB(new Cat());//!编译出错!

完整的代码如下:

class Pair<T>{ 
    private T valueA; private T valueB;

    public T getValueA() { 
        return valueA;
    }

    public void setValueA(T valueA) { 
        this.valueA = valueA;
    }

    public T getValueB() { return valueB;
    }

    public void setValueB(T valueB) { 
        this.valueB = valueB;
    }

    }

    public class TestPair {
    public static void main(String[] args){ 
        Pair<Dog> p = new Pair<Dog>(); p.setValueA(new Dog()); p.setValueB(new Dog());
        // p.setValueA(new  Cat()); 编译出错!
    }
}

Views: 61
Java面向对象设计

抽象类 VS 接口

Java相比于其他面向对象语言,如C++,设计上有一些基本区别,比如Java不支持多继承。这种限制,在规范了代码实现的同时,也产生了一些局限性,影响着程序设计结构。Java类可以实现多个接口,因为接口是抽象方法的集合,所以这是声明性的,但不能通过扩展多个抽象类来重用逻辑。

在一些情况下存在特定场景,需要抽象出与具体实现、实例化无关的通用逻辑,或者纯调用关系的逻辑,但是使用传统的抽象类会陷入到单继承的窘境。以往常见的做法是,实现由静态方法组成的工具类(Utils),比如java.util.Collections。

设想,为接口添加任何抽象方法,相应的所有实现了这个接口的类,也必须实现新增方法,否则会出现编译错误。对于抽象类,如果我们添加非抽象方法,其子类只会享受到能力扩展,而不用担心编译出问题。
接口的职责也不仅仅限于抽象方法的集合,其实有各种不同的实践。有一类没有任何方法的接口,通常叫作Marker Interface,顾名思义,它的目的就是为了声明某些东西,比如我们熟知的Cloneable、Serializable等。这种用法,也存在于业界其他的Java产品代码中。
从表面看,这似乎和Annotation异曲同工,也确实如此,它的好处是简单直接。对于Annotation,因为可以指定参数和值,在表达能力上要更强大一些,所以更多人选择使用Annotation。

Java 8增加了函数式编程的支持,所以又增加了一类定义,即所谓functional interface,简单说就是只有一个抽象方法的接口,通常建议使用@FunctionalInterfaceAnnotation来标记。Lambda表达式本身可以看作是一类functional interface,某种程度上这和面向对象可以算是两码事。我们熟知的Runnable、Callable之类,都
是functional interface,这里不再多介绍了,有兴趣可以参考:https://www.oreilly.com/learning/java-8-functional-interfaces 。

还有一点可能让人感到意外,严格说,Java 8以后,接口也是可以有默认方法实现的!

从Java 8开始,interface增加了对default method的支持。Java 9以后,甚至可以定义private default method。Default method提供了一种二进制兼容的扩展已有接口的办法。比如,我们熟知的java.util.Collection,它是collection体系的root interface,在Java 8中添加了一系列default method,主要是增加Lambda、Stream相关的功能。我在专栏前面提到的类似Collections之类的工具类,很多方法都适合作为default method实现在基础接口里面。
你可以参考下面代码片段:

public interface Collection<E> extends Iterable<E> {
     /**
     * Returns a sequential Stream with this collection as its source 
     * ...
     **/
     default Stream<E> sream() {
        return StreamSupport.sream(spliterator(), false);
     }
 }

面向对象设计

谈到面向对象,很多人就会想起设计模式,那些是非常经典的问题和设计方法的总结。不过在那之前还是先夯实一下基础,先来聊聊面向对象设计的基本方面。

我们一定要清楚面向对象的基本要素:封装、继承、多态。

封装的目的是隐藏事务内部的实现细节,以便提高安全性和简化编程。封装提供了合理的边界,避免外部调用者接触到内部的细节。我们在日常开发中,因为无意间暴露了细节导致难缠bug太多了,比如在多线程环境暴露内部状态,导致的并发修改问题。从另外一个角度看,封装这种隐藏,也提供了简化的界面,避免太多无意义的细节浪费调用者的精力。
继承是代码复用的基础机制,类似于我们对于马、白马、黑马的归纳总结。但要注意,继承可以看作是非常紧耦合的一种关系,父类代码修改,子类行为也会变动。在实践中,过度滥用继承,可能会起到反效果。
多态,你可能立即会想到重写(override)和重载(overload)、向上转型。简单说,重写是父子类中相同名字和参数的方法,不同的实现;重载则是相同名字的方法,但是不同的参数,本质上这些方法签名是不一样的,为了更好说明,请参考下面的样例代码:

public int doSomething() {
 return 0;
}

// 输入参数不同,意味着方法签名不同,重载的体现
public int doSomething(Lis<String> srs) {
 return 0;
}
// return类型不一样,编译不能通过
public short doSomething() {
 return 0;
}

这里你可以思考一个小问题,方法名称和参数一致,但是返回值不同,这种情况在Java代码中算是有效的重载吗? 答案是不是的,编译都会出错的。

进行面向对象编程,掌握基本的设计原则是必须的,我今天介绍最通用的部分,也就是所谓的S.O.L.I.D原则。

  • 单一职责(Single Responsibility),类或者对象最好是只有单一职责,在程序设计中如果发现某个类承担着多种义务,可以考虑进行拆分。
  • 开关原则(Open-Close, Open for extension, close for modifcation),设计要对扩展开放,对修改关闭。换句话说,程序设计应保证平滑的扩展性,尽量避免因为新增同
    类功能而修改已有实现,这样可以少产出些回归(regression)问题。
  • 里氏替换(Liskov Substitution),这是面向对象的基本要素之一,进行继承关系抽象时,凡是可以用父类或者基类的地方,都可以用子类替换。
  • 接口分离(Interface Segregation),我们在进行类和接口设计时,如果在一个接口里定义了太多方法,其子类很可能面临两难,就是只有部分方法对它是有意义的,这就破坏
    了程序的内聚性。
    对于这种情况,可以通过拆分成功能单一的多个接口,将行为进行解耦。在未来维护中,如果某个接口设计有变,不会对使用其他接口的子类构成影响。
  • 依赖反转(Dependency Inversion),实体应该依赖于抽象而不是实现。也就是说高层次模块,不应该依赖于低层次模块,而是应该基于抽象。实践这一原则是保证产品代码之
    间适当耦合度的法宝。

OOP原则实践中的取舍

值得注意的是,现代语言的发展,很多时候并不是完全遵守前面的原则的,比如,Java 10中引入了本地方法类型推断和var类型。按照,里氏替换原则,我们通常这样定义变量:
List<String> list = new ArrayLis<>();
如果使用var类型,可以简化为
var list = new ArrayLis<String>();
但是,list实际会被推断为“ArrayList ”
ArrayList<String> list = new ArrayLis<String>();
理论上,这种语法上的便利,其实是增强了程序对实现的依赖,但是微小的类型泄漏却带来了书写的变量和代码可读性的提高,所以,实践中我们还是要按照得失利弊进行选择,而不是一味得遵循原则。

OOP原则的分析

看看下面这段代码,改编自朋友圈盛传的某
伟大公司产品代码,你觉得可以利用面向对象设计原则如何改进?

public class VIPCenter {
     void serviceVIP(T extend User user>) {
     if (user insanceof SlumDogVIP) {
     // 穷X VIP,活动抢的那种
     // do somthing
     } else if(user insanceof RealVIP) {
     // do somthing
     }
     // ...
 }

这段代码的一个问题是,业务逻辑集中在一起,当出现新的用户类型时,比如,大数据发现了我们是肥羊,需要去收获一下, 这就需要直接去修改服务方法代码实现,这可能会意外影响不相关的某个用户类型逻辑。
利用开关原则,我们可以尝试改造为下面的代码:

public class VIPCenter {
     private Map<User.TYPE, ServiceProvider> providers;
     void serviceVIP(T extend User user) {
        providers.get(user.getType()).service(user);
     }
}

interface ServiceProvider{
    void service(T extend User user) ;
}

class SlumDogVIPServiceProvider implements ServiceProvider{
     void service(T extend User user){
     // do somthing
     }
 }
 class RealVIPServiceProvider implements ServiceProvider{
     void service(T extend User user) {
     // do something
}

上面的示例,将不同对象分类的服务方法进行抽象,把业务逻辑的紧耦合关系拆开,实现代码的隔离保证了方便的扩展。

Views: 36

Shell 编程入门

Shell 简介

管理整个计算机硬件的其实就是操作系统的核心(kernel),用户一般是通过 Shell 来和 kernel 沟通,来达到我们想要的工作。

Shell 脚本就是包含一组可运行的特定 Shell 命令(在这里指 bash shell)的文本文件,命令的执行与其出现在脚本中的顺序一致。

Shell 提供了一种方式让人可以方便的调用操作系统命令库的接口,便于简化那些人们不愿意操作的重复而繁杂的工作,比如 web 应用程序的部署,特别是一套多服务系统,尤其是对于新手来说更是灾难。对于一些小公司来说,没能那么幸运拥有一位高级运维人员,这就对开发提出了更高的要求,需要熟练使用 shell 脚本实现自动化部署系统。拿我们公司举例来说,之前没有自动化部署,装完数据库后,部署应用得花半天时间,用上自动部署后可以在半小时内部署好,只需输入一些自定义信息就可以,比如端口。

除了这些还可以用来做比如:定时删除日志文件、Web 爬取、磁盘用量跟踪、天气数据下载、文件更名,等等。

常见的 shell 指令我们肯定经常会使用,比如:cd、ll、ls -la、vim。bash 的功能里面最棒的一个就是它能记住使用过的指令,你只要摁上下键,就可以找到前/后一个指令,非常方便,默认可以记住多达 1000 个的指令!

我们可以使用 alias 来帮助我们减少输入,比如下达命令设定别名:$ alias lm = 'ls -la',这样就可以使用 lm 代替 ls -la。

Shell 变量

自定义变量和环境变量
在 Shell 变量中包括自定义变量和环境变量:

自定义变量:脚本中自己命名定义的变量,通常为局部变量,其他 Shell 程序不能访问到;

环境变量,操作系统已定义的变量,如 PATH,所有 Shell 程序都能访问到,也可以通过 env 查看所有环境变量。 可以通过 echo $ORACLE_HOME 来查看所有环境变量。

常见的环境变量有:

变量名 作用
PATH 决定了 Shell 将从哪些目录下查找程序或命令
LANG 操作系统字符集
HOME 当前用户主目录,如 oracle 的主目录为:/home/oracle
HISTSIZE 历史记录数,可以记住的 shell 指令数
HOSTNAME 指主机的名称
SHELL 当前用户 Shell 类型,如:/bin/bash

命名

变量名由字母、数字、下划线组成,如:url_1。
只能以字母或者下划线开头,如:route_path、_pig。
不能使用 Shell 的保留字。
不能使用空格、不能使用标点符号。
赋值、调用、删除

  1. 新建 hello.sh 脚本,扩展名不影响执行:
#!/bin/bash
#自定义变量 hello
hello="Hello world!"; //注意等号两边不能有空格
echo $hello;
  1. 给 hello.sh 脚本赋予执行权限:chmod +x hello.sh。

  2. 调用脚本 ./hello.sh,hello.sh 的前面需要加上 ./,这是因为不加上的话会去 PATH 下查找是否有对应的命令可以执行,而 PATH 下只有 /bin、/sbin、/usr/bin、/usr/sbin,通常当前目录不在 PATH 下,就会提示 comman not found,所以要用 ./ 告诉系统在当前目录下查找。

. 使用 unset 命令可以删除变量:

unset variable_name
例如:


#!/bin/bash
#自定义 hello
hello="Hello world!"
echo "hello="$hello
unset hello
echo "hello="$hello

输出结果:

[oracle@195 ~]$ ./hello.sh 
hello=Hello world!
hello=

Shell 字符串

单引号、双引号
Shell 中最常用的数据类型就是字符串和数字,除此之外也没有数据类型了,在 Shell 中字符串可以用单引号或者双引号来包围,如:‘/opt/IBM’、"/opt/IBM"、/opt/IBM。也可以没有引号包围。

两者的区别在于:

  • 单引号包围的字符串会以原样输出,如:echo 'hello ${name}',会输出:hello ${name},且单引号包围的字符串中不能出现单引号,进行转义也不行。

  • 双引号包围的字符串会将变量进行替换,如:echo "hello ${name}",会输出:hello jack,且双引号包围的字符串中可以出现双引号,进行转义就行。
    不被引号包围的字符串,会对变量进行解析,这点跟双引号一样,但是字符串中不能出现空格,否则空格后面的字符串会被当作命令或者其他变量解析。
    综上,当有变量时最好是使用双引号包围字符串,且变量最好有 {} 包围,明确变量名,这也是最佳编程实践。

获取字符串长度

获取字符串长度的方式有两种:

${#string_name}
expr length string_name

举个例子:

#!/bin/bash
#自定义 hello
hello="Hello world!"
echo "length of hello is:"${#hello}
expr length "$hello"

输出:

[oracle@195 ~]$ ./hello.sh 
length of hello is:12
12

截取字符串

使用 # 截取右边字符,方式为 ${hello#*chars},例如:

#!/bin/bash
#自定义 hello
hello="Hello world!"
echo ${hello#*o}

输出:


[oracle@195 ~]$ ./hello.sh 
world!

表明截取了从左到右第一个 o 右边的字符串,*chars 代表忽略 chars 左边任意长度的字符串(包括 chars)。如果不写星号,那么就不会忽略 chars 左边的字符串。

如果像直到最后一个 chars 再截取右边的字符串,那么可以用 ## 来截取,例如:

#!/bin/bash
#自定义 hello
hello="Hello world!"
echo ${hello##o}

输出:

[oracle@195 ~]$ ./hello.sh 
rld!

使用 % 截取左边字符串,方式为:${hello%chars}。与 # 不同的是,这里在右边,代表忽略 chars 右边的任意长度字符串,来截取 chars 左边的字符串,其用法跟 # 类似。

看个例子:

#!/bin/bash
#自定义 hello
hello="Hello world!"
echo ${hello%o*}

输出:


[oracle@195 ~]$ ./hello.sh 
Hello w

可以看到“%”截取时是从右边开始的,从右往左,也可使用“%%”直到最后一个 chars 再截取左边的字符串。

Shell 数组
Shell 数组只能是一维的,不支持多维数组,并且 Shell 是弱类型的,数组中的类型不一定只有一种,且不限制数组的长度大小,理论上可以是无限大小。

#!/bin/bash
#创建数组
array=(a b c d e)
#获取数组长度
length1=${#array[@]}
echo "length1=${length1}"
#另一种获取数组长度方法
length2=${#array[*]}
echo "length2=${length2}"
#获取第三个元素
echo ${array[2]}
#删除第二个元素
unset array[1]
#输出整个数组
echo ${array[@]}
#for 遍历整个数组
for i in ${array[@]};do echo $i;done;
#删除整个数组
unset array
#查看是否已删除
for i in ${array[@]};do echo $i;done;

输出:

[oracle@195 ~]$ ./test_array.sh 
length1=5
length2=5
c
a c d e
a
c
d
e

Shell 基本运算符

算数运算符

包括:+、-、*、/、%、=、==、!=

这些跟我们其他编程语言遇到的是一样的,就不详细说明,举个简单例子。

#!/bin/bash
a=1;
b=2;
c=`expr $a + $b`;
echo "total is: ${c}";

输出:

[oracle@195 shelldir]$ ./test_operation.sh 
total is: 3
关系运算符

包括:-eq、-nq、-gt、-lt、-ge、-le

运算符 说明
-eq 判断两个数据是否相等
-nq 判断两个数据是否不相等
-gt 判断左边的数据是否大于右边的数据
-lt 判断左边的数据是否小于右边的数据
-ge 判断左边的数据是否大于等于右边的数据
-le 判断左边的数据是否小于等于右边的数据

接下来看下程序怎么写:

#!/bin/bash
a=100;
b=99;
if [ $a -eq $b ]
then
  echo "A"
else
  echo "B"
fi

输出:

[oracle@195 shelldir]$ ./test_operation.sh 
B

其他关系运算符相信大家都应该知道怎么使用了。

逻辑运算符

包括:&&、||

运算符 说明
&& 逻辑与,左右两边的表达式都为 true 才 true,有一个为 false 则为 false
\ \
接下来看下程序


#!/bin/bash
a=100;
b=99;
c=90;
if [[ $a -gt $b && $a -gt $c ]]
then
  echo "A"
elif [[ $b -gt $a && $b -gt $c ]]
then
  echo "B"
else
  echo "C"
fi

输出:

[oracle@195 shelldir]$ ./test_operation.sh 
A

布尔运算符

包括:!、-o、-a

运算符 说明
! 非运算,对表达式取反,如:[ !false ] 返回 false
-o 或运算,左右两边的表达式存在 true 则为 true,都为 false 则为 false
-a 与运算,左右两边的表达式存在 false 则为 false,都为 true 则为 true
接下来看下程序

#!/bin/bash
a=100;
b=99;
c=90;
if !((a == b))
then
  echo "a 与 b 不相等"
else
  echo "a 与 b 相等"
fi

if [ $a -gt $b -a $a -gt $c ]
then
  echo "A"
elif [ $b -gt $a -a $b -gt $c ]
then
  echo "B"
else
  echo "C"
fi

输出:

a 与 b 不相等
A
-a 与 -o 用法相同。

字符串运算符

包括:=、!=、-z、-n、str

运算符 说明
= 检测两个字符串是否相等,相等返回 true
!= 检测两个字符串是否不相等,不相等则返回 true
-z 检测字符串长度是否为 0,为 0 则返回 true
-n 检测字符串长度是否为 0,不为 0 则返回 true
str 检测字符串是否为空,不为空则返回 true
接下来一起看下程序:

#!/bin/bash
a="zoom"
b=""
if [ -n $a ]
then
  echo "a 长度不为 0"
else
  echo "a 长度为 0"
fi
if [ -z $b ]
then
  echo "b 长度为 0"
else
  echo "b 长度不为 0"
fi
if [ $b ]
then
  echo "b 不为空字符串"
else
  echo "b 是空字符串"
fi

输出:


a 长度不为 0
b 长度为 0
b 是空字符串

Shell 流程控制

if 条件语句

前面我们也看到了 if 条件语句的使用,基本语法就是:

#!/bin/bash
if conditionA
then 
  exprA
elif conditionB
then 
  exprB
else
  exprC
fi

这就是 if-elif-else,最后别忘了 fi 作为结尾。跟 Java 不同的是,Shell 的 if 不能有空语句,即什么都不做的条件表达式。还有一点是 condition 一般用中括号[],Java 都是用小括号 ()。

for 循环语句

for 循环语句的基本语法是:

#!/bin/bash
for loop in item1 item2 ... itemN
do
  condition1
  condition2
  ...
  conditionP
done

其中,for loop in 1 2 3 4 5 可被替换成 for loop in {1..5}。以及 类似于 java 中的 for 条件语句写法:for((i=0;i<=5;i++))。

举个例子:

#!/bin/bash
for((i=0;i<=5;i++))
do
  echo "num is ${i}"
done

输出:

num is 0
num is 1
num is 2
num is 3
num is 4
num is 5

while 循环语句

有了上面的 if 和 for 之后,相信可以实现很多的逻辑控制了,接下来再看看 while 循环语句怎么写。

基本语法是:

#!/bin/bash
while conditionA
do
  commandA
done

看个例子:

#!/bin/bash
i=0
while(( i<=5 ))
do
  echo "num is ${i}"
  let i++
done

输出:

num is 0
num is 1
num is 2
num is 3
num is 4
num is 5

while 语句还可以用来接收用户输入,用法是:

while read choose
无限循环是经常会用到的一个语法,下面列举了无限循环的三种实现方式:

 1. while : 
 2. while true
 3. for(( ; ; ))

Shell 函数

了解完了上面的流程控制语句,下面我们来看看 Shell 是怎么定义函数,以及调用函数的,我们先来看个简单的例子。

#!/bin/bash
printnum(){
    echo "my first function"
}
echo "call funtion start"
printnum
echo "call funtion end"
输出:

call funtion start
my first function
call funtion end

这个是不带参数没有返回值的例子,接下来我们来看看不带参数没有返回值的例子:

#!/bin/bash
plusnum(){
    a=1
    b=3
    return $((a+b))
}
plusnum
echo "a+b="$?

输出:

a+b=4
从上面我们可以看出,在调用函数 plusnum 后,通过$?可以拿到返回结果。而调用方式是直接用函数名即可,不需要加上括号,这点跟 Java 和其他面向对象的编程语言都有所不同。

下面再看一个有参数的函数:

#!/bin/bash
plusnum(){
    a=$1
    b=$2
    return $((a+b))
}
plusnum 99 100
echo "a+b="$?

从上面我们可以看到函数 plusnum 中通过 $1 和 $2 获取传入的参数,在相加后返回结果,调用时直接跟在函数后面,并不像 Java 的函数传参。

理解一个 Shell 脚本
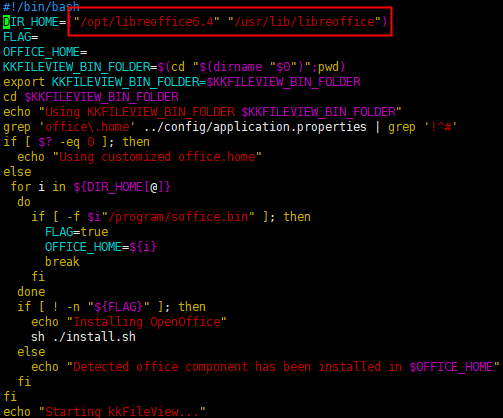
其实前面举得例子都比较简单,可以认为前面的语法是 Shell 程序的一个骨架,而众多的 Shell 命令以及业务内容将是填充进去的血肉,下面我们利用前面学过的知识来理解下下面的这个 Shell 程序。

file

首先他先定义了一个 DIR_HOME 数组
然后定义变量 FLAG、OFFICE_HOME,值为空
$(cd "$(dirname "$0")";pwd) 意为取当前目录
输出环境变量 KKFILEVIEW_BIN_FOLDER
进入目录
输出目录
查询 application.properties 中不以 # 开头的 office.home 的数量
如果上面的值为 0,那么就认为用了自定义的 office.home
否则循环最开始定义的 DIR_HOME 数组,看看其中是否有 soffice.bin 文件,若有则修改 FLAG 的值为 true,OFFICE_HOME 赋值为当前 DIR_HOME 数组的值,并且跳出循环
接下来判断 FLAG 是否为空,如果为空说明系统中从未安装过 OpenOffice,则调用 install.sh 进行安装,否则将认为已安装 OpenOffice,并输出安装路径
下面开始正式启动应用程序

总结

通过 Shell 脚本可以大大简化我们的工作,使我们从日复一日的重复劳动中解放出来,有时间去尝试更有趣的事物。学了技术之后就赶紧动手尝试起来吧,有些东西看看都会,一写起来就不会了,所以玩过之后印象才会更加深刻。

Views: 51

Exception Handling in Java

Exception Handling in Java

The Exception Handling in Java is one of the powerful mechanism to handle the runtime errors so that normal flow of the application can be maintained.

What is Exception in Java

Dictionary Meaning: Exception is an abnormal condition.

In Java, an exception is an event that disrupts the normal flow of the program. It is an object which is thrown at runtime.

What is Exception Handling

Exception Handling is a mechanism to handle runtime errors such as ClassNotFoundException, IOException, SQLException, RemoteException, etc.

Advantage of Exception Handling

The core advantage of exception handling is to maintain the normal flow of the application. An exception normally disrupts the normal flow of the application that is why we use exception handling. Let's take a scenario:

statement 1;  
statement 2;  
statement 3;  
statement 4;  
statement 5;//exception occurs  
statement 6;  
statement 7;  
statement 8;  
statement 9;  
statement 10;  

Suppose there are 10 statements in your program and there occurs an exception at statement 5, the rest of the code will not be executed i.e. statement 6 to 10 will not be executed. If we perform exception handling, the rest of the statement will be executed. That is why we use exception handling in Java.

Hierarchy of Java Exception classes

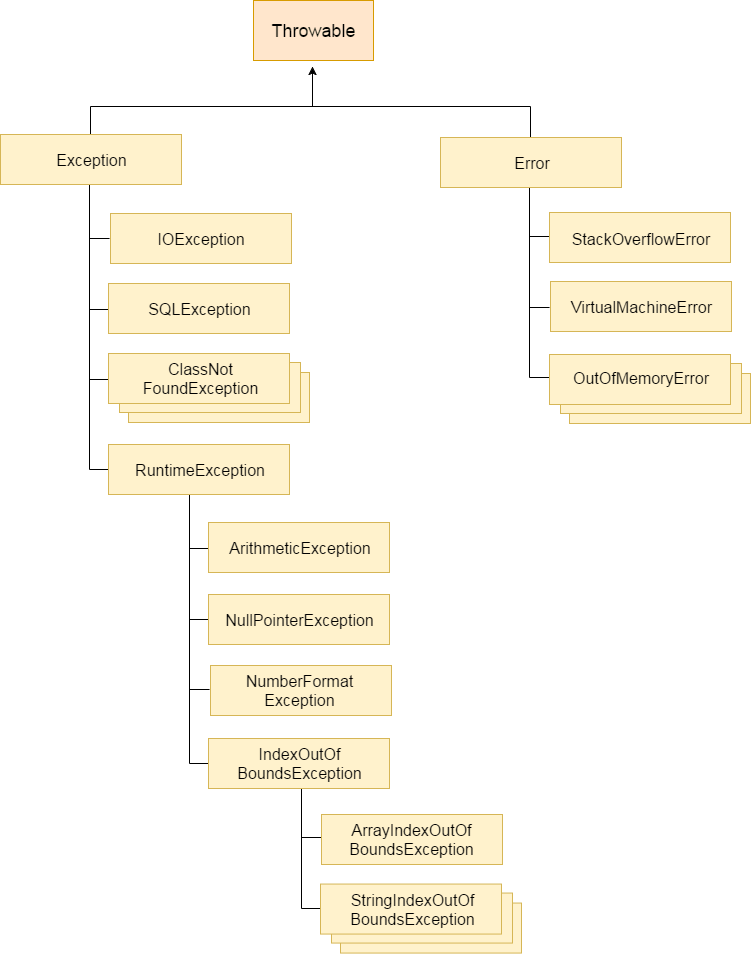
The java.lang.Throwable class is the root class of Java Exception hierarchy which is inherited by two subclasses: Exception and Error. A hierarchy of Java Exception classes are given below:

hierarchy of exception handling

Hierarchy of Java Exception classes

Types of Java Exceptions

There are mainly two types of exceptions: checked and unchecked. Here, an error is considered as the unchecked exception. According to Oracle, there are three types of exceptions:

  • Checked Exception
  • Unchecked Exception
  • Error

Types of Java Exceptions
Difference between Checked and Unchecked Exceptions
1) Checked Exception
The classes which directly inherit Throwable class except RuntimeException and Error are known as checked exceptions e.g. IOException, SQLException etc. Checked exceptions are checked at compile-time.

2) Unchecked Exception
The classes which inherit RuntimeException are known as unchecked exceptions e.g. ArithmeticException, NullPointerException, ArrayIndexOutOfBoundsException etc. Unchecked exceptions are not checked at compile-time, but they are checked at runtime.

3) Error
Error is irrecoverable e.g. OutOfMemoryError, VirtualMachineError, AssertionError etc.

Java Exception Keywords

There are 5 keywords which are used in handling exceptions in Java.

Keyword Description

  • try The "try" keyword is used to specify a block where we should place exception code. The try block must be followed by either catch or finally. It means, we can't use try block alone.
  • catch The "catch" block is used to handle the exception. It must be preceded by try block which means we can't use catch block alone. It can be followed by finally block later.
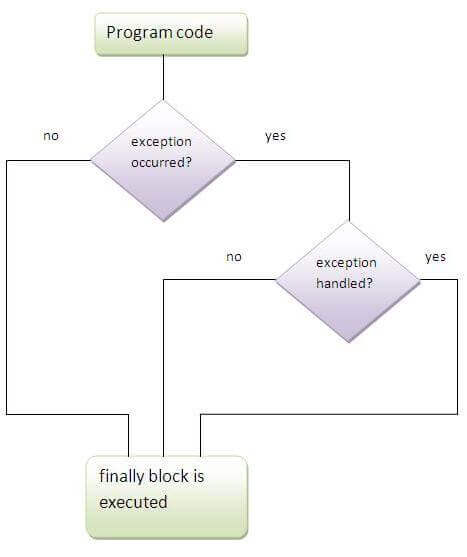
  • finally The "finally" block is used to execute the important code of the program. It is executed whether an exception is handled or not.
  • throw The "throw" keyword is used to throw an exception.
  • throws The "throws" keyword is used to declare exceptions. It doesn't throw an exception. It specifies that there may occur an exception in the method. It is always used with method signature.

Java Exception Handling Example

Let's see an example of Java Exception Handling where we using a try-catch statement to handle the exception.

public class JavaExceptionExample{  
  public static void main(String args[]){  
   try{  
      //code that may raise exception  
      int data=100/0;  
   }catch(ArithmeticException e){System.out.println(e);}  
   //rest code of the program   
   System.out.println("rest of the code...");  
  }  
}  

Test it Now
Output:

Exception in thread main java.lang.ArithmeticException:/ by zero
rest of the code...
In the above example, 100/0 raises an ArithmeticException which is handled by a try-catch block.

Common Scenarios of Java Exceptions

There are given some scenarios where unchecked exceptions may occur. They are as follows:

1) A scenario where ArithmeticException occurs
If we divide any number by zero, there occurs an ArithmeticException.

int a=50/0;//ArithmeticException  

2) A scenario where NullPointerException occurs
If we have a null value in any variable, performing any operation on the variable throws a NullPointerException.

String s=null;  
System.out.println(s.length());//NullPointerException  

3) A scenario where NumberFormatException occurs
The wrong formatting of any value may occur NumberFormatException. Suppose I have a string variable that has characters, converting this variable into digit will occur NumberFormatException.

String s="abc";  
int i=Integer.parseInt(s);//NumberFormatException  

4) A scenario where ArrayIndexOutOfBoundsException occurs
If you are inserting any value in the wrong index, it would result in ArrayIndexOutOfBoundsException as shown below:


int a[]=new int[5];  
a[10]=50; //ArrayIndexOutOfBoundsException  

Java try-catch block

Java try block

Java try block is used to enclose the code that might throw an exception. It must be used within the method.

If an exception occurs at the particular statement of try block, the rest of the block code will not execute. So, it is recommended not to keeping the code in try block that will not throw an exception.

Java try block must be followed by either catch or finally block.

Syntax of Java try-catch

try{    
//code that may throw an exception    
}catch(Exception_class_Name ref){}    
Syntax of try-finally block
try{    
//code that may throw an exception    
}finally{}    

Java catch block

Java catch block is used to handle the Exception by declaring the type of exception within the parameter. The declared exception must be the parent class exception ( i.e., Exception) or the generated exception type. However, the good approach is to declare the generated type of exception.

The catch block must be used after the try block only. You can use multiple catch block with a single try block.

Let's try to understand the problem if we don't use a try-catch block.

Example 1

public class TryCatchExample1 {  

    public static void main(String[] args) {  

        int data=50/0; //may throw exception   

        System.out.println("rest of the code");  

    }  

}  

Test it Now
Output:

Exception in thread "main" java.lang.ArithmeticException: / by zero

As displayed in the above example, the rest of the code is not executed (in such case, the rest of the code statement is not printed).

There can be 100 lines of code after exception. So all the code after exception will not be executed.

Solution by exception handling
Let's see the solution of the above problem by a java try-catch block.

Example 2

public class TryCatchExample2 {  

    public static void main(String[] args) {  
        try  
        {  
        int data=50/0; //may throw exception   
        }  
            //handling the exception  
        catch(ArithmeticException e)  
        {  
            System.out.println(e);  
        }  
        System.out.println("rest of the code");  
    }  

}  

Test it Now
Output:


java.lang.ArithmeticException: / by zero
rest of the code

Now, as displayed in the above example, the rest of the code is executed, i.e., the rest of the code statement is printed.

Example 3
In this example, we also kept the code in a try block that will not throw an exception.

public class TryCatchExample3 {  

    public static void main(String[] args) {  
        try  
        {  
        int data=50/0; //may throw exception   
                         // if exception occurs, the remaining statement will not exceute  
        System.out.println("rest of the code");  
        }  
             // handling the exception   
        catch(ArithmeticException e)  
        {  
            System.out.println(e);  
        }  

    }  

}  

Test it Now
Output:

java.lang.ArithmeticException: / by zero

Here, we can see that if an exception occurs in the try block, the rest of the block code will not execute.

Example 4
Here, we handle the exception using the parent class exception.

public class TryCatchExample4 {  

    public static void main(String[] args) {  
        try  
        {  
        int data=50/0; //may throw exception   
        }  
            // handling the exception by using Exception class      
        catch(Exception e)  
        {  
            System.out.println(e);  
        }  
        System.out.println("rest of the code");  
    }  

}  

Test it Now
Output:


java.lang.ArithmeticException: / by zero
rest of the code

Example 5
Let's see an example to print a custom message on exception.

public class TryCatchExample5 {

public static void main(String[] args) {  
    try  
    {  
    int data=50/0; //may throw exception   
    }  
         // handling the exception  
    catch(Exception e)  
    {  
              // displaying the custom message  
        System.out.println("Can't divided by zero");  
    }  
}  

}
Test it Now
Output:

Can't divided by zero

Example 6
Let's see an example to resolve the exception in a catch block.

public class TryCatchExample6 {  

    public static void main(String[] args) {  
        int i=50;  
        int j=0;  
        int data;  
        try  
        {  
        data=i/j; //may throw exception   
        }  
            // handling the exception  
        catch(Exception e)  
        {  
             // resolving the exception in catch block  
            System.out.println(i/(j+2));  
        }  
    }  
}  

Test it Now
Output:


25

Example 7
In this example, along with try block, we also enclose exception code in a catch block.

public class TryCatchExample7 {  

    public static void main(String[] args) {  

        try  
        {  
        int data1=50/0; //may throw exception   

        }  
             // handling the exception  
        catch(Exception e)  
        {  
            // generating the exception in catch block  
        int data2=50/0; //may throw exception   

        }  
    System.out.println("rest of the code");  
    }  
}  

Test it Now
Output:


Exception in thread "main" java.lang.ArithmeticException: / by zero

Here, we can see that the catch block didn't contain the exception code. So, enclose exception code within a try block and use catch block only to handle the exceptions.

Example 8
In this example, we handle the generated exception (Arithmetic Exception) with a different type of exception class (ArrayIndexOutOfBoundsException).

public class TryCatchExample8 {

public static void main(String[] args) {  
    try  
    {  
    int data=50/0; //may throw exception   

    }  
        // try to handle the ArithmeticException using ArrayIndexOutOfBoundsException  
    catch(ArrayIndexOutOfBoundsException e)  
    {  
        System.out.println(e);  
    }  
    System.out.println("rest of the code");  
}  

}
Test it Now
Output:

Exception in thread "main" java.lang.ArithmeticException: / by zero

Example 9
Let's see an example to handle another unchecked exception.


public class TryCatchExample9 {  

    public static void main(String[] args) {  
        try  
        {  
        int arr[]= {1,3,5,7};  
        System.out.println(arr[10]); //may throw exception   
        }  
            // handling the array exception  
        catch(ArrayIndexOutOfBoundsException e)  
        {  
            System.out.println(e);  
        }  
        System.out.println("rest of the code");  
    }  

}  

Test it Now
Output:

java.lang.ArrayIndexOutOfBoundsException: 10
rest of the code

Example 10
Let's see an example to handle checked exception.

import java.io.FileNotFoundException;  
import java.io.PrintWriter;  

public class TryCatchExample10 {  

    public static void main(String[] args) {  

        PrintWriter pw;  
        try {  
            pw = new PrintWriter("jtp.txt"); //may throw exception   
            pw.println("saved");  
        }  
// providing the checked exception handler  
 catch (FileNotFoundException e) {  

            System.out.println(e);  
        }         
    System.out.println("File saved successfully");  
    }  
}  

Test it Now
Output:

File saved successfully

Internal working of java try-catch block

internal working of try-catch block
The JVM firstly checks whether the exception is handled or not. If exception is not handled, JVM provides a default exception handler that performs the following tasks:

  1. Prints out exception description.
    Prints the stack trace (Hierarchy of methods where the exception occurred).
    Causes the program to terminate.

  2. But if exception is handled by the application programmer, normal flow of the application is maintained i.e. rest of the code is executed.

Java catch multiple exceptions

Java Multi-catch block

A try block can be followed by one or more catch blocks. Each catch block must contain a different exception handler. So, if you have to perform different tasks at the occurrence of different exceptions, use java multi-catch block.

Points to remember
  • At a time only one exception occurs and at a time only one catch block is executed.
  • All catch blocks must be ordered from most specific to most general, i.e. catch for ArithmeticException must come before catch for Exception.

Example 1
Let's see a simple example of java multi-catch block.

public class MultipleCatchBlock1 {  

    public static void main(String[] args) {  

           try{    
                int a[]=new int[5];    
                a[5]=30/0;    
               }    
               catch(ArithmeticException e)  
                  {  
                   System.out.println("Arithmetic Exception occurs");  
                  }    
               catch(ArrayIndexOutOfBoundsException e)  
                  {  
                   System.out.println("ArrayIndexOutOfBounds Exception occurs");  
                  }    
               catch(Exception e)  
                  {  
                   System.out.println("Parent Exception occurs");  
                  }             
               System.out.println("rest of the code");    
    }  
}  

Test it Now
Output:

Arithmetic Exception occurs

rest of the code
Example 2

public class MultipleCatchBlock2 {  

    public static void main(String[] args) {  

           try{    
                int a[]=new int[5];    

                System.out.println(a[10]);  
               }    
               catch(ArithmeticException e)  
                  {  
                   System.out.println("Arithmetic Exception occurs");  
                  }    
               catch(ArrayIndexOutOfBoundsException e)  
                  {  
                   System.out.println("ArrayIndexOutOfBounds Exception occurs");  
                  }    
               catch(Exception e)  
                  {  
                   System.out.println("Parent Exception occurs");  
                  }             
               System.out.println("rest of the code");    
    }  
}  

Test it Now
Output:


ArrayIndexOutOfBounds Exception occurs
rest of the code

Example 3
In this example, try block contains two exceptions. But at a time only one exception occurs and its corresponding catch block is invoked.

public class MultipleCatchBlock3 {  

    public static void main(String[] args) {  

           try{    
                int a[]=new int[5];    
                a[5]=30/0;    
                System.out.println(a[10]);  
               }    
               catch(ArithmeticException e)  
                  {  
                   System.out.println("Arithmetic Exception occurs");  
                  }    
               catch(ArrayIndexOutOfBoundsException e)  
                  {  
                   System.out.println("ArrayIndexOutOfBounds Exception occurs");  
                  }    
               catch(Exception e)  
                  {  
                   System.out.println("Parent Exception occurs");  
                  }             
               System.out.println("rest of the code");    
    }  
}  

Test it Now
Output:

Arithmetic Exception occurs
rest of the code

Example 4
In this example, we generate NullPointerException, but didn't provide the corresponding exception type. In such case, the catch block containing the parent exception class Exception will invoked.

public class MultipleCatchBlock4 {

public static void main(String[] args) {  

       try{    
            String s=null;  
            System.out.println(s.length());  
           }    
           catch(ArithmeticException e)  
              {  
               System.out.println("Arithmetic Exception occurs");  
              }    
           catch(ArrayIndexOutOfBoundsException e)  
              {  
               System.out.println("ArrayIndexOutOfBounds Exception occurs");  
              }    
           catch(Exception e)  
              {  
               System.out.println("Parent Exception occurs");  
              }             
           System.out.println("rest of the code");    
}  

}
Test it Now
Output:


Parent Exception occurs
rest of the code

Example 5
Let's see an example, to handle the exception without maintaining the order of exceptions (i.e. from most specific to most general).

class MultipleCatchBlock5{    
  public static void main(String args[]){    
   try{    
    int a[]=new int[5];    
    a[5]=30/0;    
   }    
   catch(Exception e){System.out.println("common task completed");}    
   catch(ArithmeticException e){System.out.println("task1 is completed");}    
   catch(ArrayIndexOutOfBoundsException e){System.out.println("task 2 completed");}    
   System.out.println("rest of the code...");    
 }    
}   

Test it Now
Output:

Compile-time error

Java Nested try block

The try block within a try block is known as nested try block in java.

Why use nested try block
Sometimes a situation may arise where a part of a block may cause one error and the entire block itself may cause another error. In such cases, exception handlers have to be nested.

Syntax:

....  
try  
{  
    statement 1;  
    statement 2;  
    try  
    {  
        statement 1;  
        statement 2;  
    }  
    catch(Exception e)  
    {  
    }  
}  
catch(Exception e)  
{  
}  
....  

Java nested try example
Let's see a simple example of java nested try block.

class Excep6{  
 public static void main(String args[]){  
  try{  
    try{  
     System.out.println("going to divide");  
     int b =39/0;  
    }catch(ArithmeticException e){System.out.println(e);}  

    try{  
    int a[]=new int[5];  
    a[5]=4;  
    }catch(ArrayIndexOutOfBoundsException e){System.out.println(e);}  

    System.out.println("other statement);  
  }catch(Exception e){System.out.println("handeled");}  

  System.out.println("normal flow..");  
 }  
}  

Finally Block in Exception Handling

Java finally block is a block that is used to execute important code such as closing connection, stream etc.

Java finally block is always executed whether exception is handled or not.

Java finally block follows try or catch block.

java finally

 Note: If you don't handle exception, before terminating the program, JVM executes finally block(if any).

Why use java finally

Finally block in java can be used to put "cleanup" code such as closing a file, closing connection etc.

Java throw exception

Java throw keyword

The Java throw keyword is used to explicitly throw an exception.

We can throw either checked or uncheked exception in java by throw keyword. The throw keyword is mainly used to throw custom exception. We will see custom exceptions later.

The syntax of java throw keyword is given below.

throw exception;  

Let's see the example of throw IOException.

throw new IOException("sorry device error);  

java throw keyword example

In this example, we have created the validate method that takes integer value as a parameter. If the age is less than 18, we are throwing the ArithmeticException otherwise print a message welcome to vote.

public class TestThrow1{  
   static void validate(int age){  
     if(age<18)  
      throw new ArithmeticException("not valid");  
     else  
      System.out.println("welcome to vote");  
   }  
   public static void main(String args[]){  
      validate(13);  
      System.out.println("rest of the code...");  
  }  
}  

Test it Now
Output:

Exception in thread main java.lang.ArithmeticException:not valid

Java Exception propagation

An exception is first thrown from the top of the stack and if it is not caught, it drops down the call stack to the previous method,If not caught there, the exception again drops down to the previous method, and so on until they are caught or until they reach the very bottom of the call stack.This is called exception propagation.

Rule: By default Unchecked Exceptions are forwarded in calling chain (propagated).

Program of Exception Propagation

class TestExceptionPropagation1{  
  void m(){  
    int data=50/0;  
  }  
  void n(){  
    m();  
  }  
  void p(){  
   try{  
    n();  
   }catch(Exception e){System.out.println("exception handled");}  
  }  
  public static void main(String args[]){  
   TestExceptionPropagation1 obj=new TestExceptionPropagation1();  
   obj.p();  
   System.out.println("normal flow...");  
  }  
}  

Test it Now

Output:exception handled
       normal flow...

exception propagation

In the above example exception occurs in m() method where it is not handled,so it is propagated to previous n() method where it is not handled, again it is propagated to p() method where exception is handled.

Exception can be handled in any method in call stack either in main() method,p() method,n() method or m() method.

Rule: By default, Checked Exceptions are not forwarded in calling chain (propagated).
Program which describes that checked exceptions are not propagated

class TestExceptionPropagation2{  
  void m(){  
    throw new java.io.IOException("device error");//checked exception  
  }  
  void n(){  
    m();  
  }  
  void p(){  
   try{  
    n();  
   }catch(Exception e){System.out.println("exception handeled");}  
  }  
  public static void main(String args[]){  
   TestExceptionPropagation2 obj=new TestExceptionPropagation2();  
   obj.p();  
   System.out.println("normal flow");  
  }  
}  

Test it Now

Output:Compile Time Error

Java throws keyword

The Java throws keyword is used to declare an exception. It gives an information to the programmer that there may occur an exception so it is better for the programmer to provide the exception handling code so that normal flow can be maintained.

Exception Handling is mainly used to handle the checked exceptions. If there occurs any unchecked exception such as NullPointerException, it is programmers fault that he is not performing check up before the code being used.

Syntax of java throws

return_type method_name() throws exception_class_name{  
//method code  
}  

Which exception should be declared checked exception only, because:
unchecked Exception: under your control so correct your code.
error: beyond your control e.g. you are unable to do anything if there occurs VirtualMachineError or StackOverflowError.

Advantage of Java throws keyword

Now Checked Exception can be propagated (forwarded in call stack).

It provides information to the caller of the method about the exception.

Java throws example
Let's see the example of java throws clause which describes that checked exceptions can be propagated by throws keyword.

import java.io.IOException;  
class Testthrows1{  
  void m()throws IOException{  
    throw new IOException("device error");//checked exception  
  }  
  void n()throws IOException{  
    m();  
  }  
  void p(){  
   try{  
    n();  
   }catch(Exception e){System.out.println("exception handled");}  
  }  
  public static void main(String args[]){  
   Testthrows1 obj=new Testthrows1();  
   obj.p();  
   System.out.println("normal flow...");  
  }  
}  

Test it Now
Output:


exception handled
normal flow...

Rule: If you are calling a method that declares an exception, you must either caught or declare the exception.

There are two cases:
Case1:You caught the exception i.e. handle the exception using try/catch.
Case2:You declare the exception i.e. specifying throws with the method.

Case1: You handle the exception
In case you handle the exception, the code will be executed fine whether exception occurs during the program or not.

import java.io.*;  
class M{  
 void method()throws IOException{  
  throw new IOException("device error");  
 }  
}  
public class Testthrows2{  
   public static void main(String args[]){  
    try{  
     M m=new M();  
     m.method();  
    }catch(Exception e){System.out.println("exception handled");}     

    System.out.println("normal flow...");  
  }  
}  

Test it Now

Output:exception handled
       normal flow...

Case2: You declare the exception
A)In case you declare the exception, if exception does not occur, the code will be executed fine.
B)In case you declare the exception if exception occures, an exception will be thrown at runtime because throws does not handle the exception.

A)Program if exception does not occur

import java.io.*;  
class M{  
 void method()throws IOException{  
  System.out.println("device operation performed");  
 }  
}  
class Testthrows3{  
   public static void main(String args[])throws IOException{//declare exception  
     M m=new M();  
     m.method();  

    System.out.println("normal flow...");  
  }  
}  

Test it Now

Output:device operation performed
       normal flow...

B)Program if exception occurs

import java.io.*;  
class M{  
 void method()throws IOException{  
  throw new IOException("device error");  
 }  
}  
class Testthrows4{  
   public static void main(String args[])throws IOException{//declare exception  
     M m=new M();  
     m.method();  

    System.out.println("normal flow...");  
  }  
}  

Test it Now

Output:Runtime Exception

Difference between throw and throws

There are many differences between throw and throws keywords. A list of differences between throw and throws are given below:

throw throws
Java throw keyword is used to explicitly throw an exception. Java throws keyword is used to declare an exception.
Checked exception cannot be propagated using throw only. Checked exception can be propagated with throws.
Throw is followed by an instance. Throws is followed by class.
Throw is used within the method. Throws is used with the method signature.
You cannot throw multiple exceptions. You can declare multiple exceptions e.g. public void method()throws IOException,SQLException.

Que) Can we rethrow an exception?
Yes, by throwing same exception in catch block.

Java throw example

void m(){  
throw new ArithmeticException("sorry");  
}  

Java throws example

void m()throws ArithmeticException{  
//method code  
}  

Java throw and throws example

void m()throws ArithmeticException{  
throw new ArithmeticException("sorry");  
}  

Difference between final, finally and finalize

There are many differences between final, finally and finalize. A list of differences between final, finally and finalize are given below:

No. final finally finalize
1) Final is used to apply restrictions on class, method and variable. Final class can't be inherited, final method can't be overridden and final variable value can't be changed. Finally is used to place important code, it will be executed whether exception is handled or not. Finalize is used to perform clean up processing just before object is garbage collected.
2) Final is a keyword. Finally is a block. Finalize is a method.

Java final example

class FinalExample{  
public static void main(String[] args){  
final int x=100;  
x=200;//Compile Time Error  
}}  

Java finally example

class FinallyExample{  
public static void main(String[] args){  
try{  
int x=300;  
}catch(Exception e){System.out.println(e);}  
finally{System.out.println("finally block is executed");}  
}}  

Java finalize example

class FinalizeExample{  
public void finalize(){System.out.println("finalize called");}  
public static void main(String[] args){  
FinalizeExample f1=new FinalizeExample();  
FinalizeExample f2=new FinalizeExample();  
f1=null;  
f2=null;  
System.gc();  
}}  

Next TopicException Handling With Method Overriding

Next →← Prev
ExceptionHandling with MethodOverriding in Java
There are many rules if we talk about methodoverriding with exception handling. The Rules are as follows:
If the superclass method does not declare an exception
If the superclass method does not declare an exception, subclass overridden method cannot declare the checked exception but it can declare unchecked exception.
If the superclass method declares an exception
If the superclass method declares an exception, subclass overridden method can declare same, subclass exception or no exception but cannot declare parent exception.
If the superclass method does not declare an exception
1) Rule: If the superclass method does not declare an exception, subclass overridden method cannot declare the checked exception.

import java.io.*;  
class Parent{  
  void msg(){System.out.println("parent");}  
}  

class TestExceptionChild extends Parent{  
  void msg()throws IOException{  
    System.out.println("TestExceptionChild");  
  }  
  public static void main(String args[]){  
   Parent p=new TestExceptionChild();  
   p.msg();  
  }  
}  

Test it Now

Output:Compile Time Error

2) Rule: If the superclass method does not declare an exception, subclass overridden method cannot declare the checked exception but can declare unchecked exception.

import java.io.*;  
class Parent{  
  void msg(){System.out.println("parent");}  
}  

class TestExceptionChild1 extends Parent{
void msg()throws ArithmeticException{
System.out.println("child");
}
public static void main(String args[]){
Parent p=new TestExceptionChild1();
p.msg();
}
}
Test it Now

Output:child

If the superclass method declares an exception
1) Rule: If the superclass method declares an exception, subclass overridden method can declare same, subclass exception or no exception but cannot declare parent exception.
Example in case subclass overridden method declares parent exception

import java.io.*;  
class Parent{  
  void msg()throws ArithmeticException{System.out.println("parent");}  
}  

class TestExceptionChild2 extends Parent{  
  void msg()throws Exception{System.out.println("child");}  

  public static void main(String args[]){  
   Parent p=new TestExceptionChild2();  
   try{  
   p.msg();  
   }catch(Exception e){}  
  }  
}  

Test it Now

Output:Compile Time Error

Example in case subclass overridden method declares same exception

import java.io.*;  
class Parent{  
  void msg()throws Exception{System.out.println("parent");}  
}  

class TestExceptionChild3 extends Parent{  
  void msg()throws Exception{System.out.println("child");}  

  public static void main(String args[]){  
   Parent p=new TestExceptionChild3();  
   try{  
   p.msg();  
   }catch(Exception e){}  
  }  
}  

Test it Now

Output:child

Example in case subclass overridden method declares subclass exception

import java.io.*;  
class Parent{  
  void msg()throws Exception{System.out.println("parent");}  
}  

class TestExceptionChild4 extends Parent{  
  void msg()throws ArithmeticException{System.out.println("child");}  

  public static void main(String args[]){  
   Parent p=new TestExceptionChild4();  
   try{  
   p.msg();  
   }catch(Exception e){}  
  }  
}  

Test it Now

Output:child

Example in case subclass overridden method declares no exception

import java.io.*;  
class Parent{  
  void msg()throws Exception{System.out.println("parent");}  
}  

class TestExceptionChild5 extends Parent{  
  void msg(){System.out.println("child");}  

  public static void main(String args[]){  
   Parent p=new TestExceptionChild5();  
   try{  
   p.msg();  
   }catch(Exception e){}  
  }  
}  

Test it Now

Output:child

Java Custom Exception

If you are creating your own Exception that is known as custom exception or user-defined exception. Java custom exceptions are used to customize the exception according to user need.

By the help of custom exception, you can have your own exception and message.

Let's see a simple example of java custom exception.

class InvalidAgeException extends Exception{  
 InvalidAgeException(String s){  
  super(s);  
 }  
}  
class TestCustomException1{  

   static void validate(int age)throws InvalidAgeException{  
     if(age<18)  
      throw new InvalidAgeException("not valid");  
     else  
      System.out.println("welcome to vote");  
   }  

   public static void main(String args[]){  
      try{  
      validate(13);  
      }catch(Exception m){System.out.println("Exception occured: "+m);}  

      System.out.println("rest of the code...");  
  }  
}  

Test it Now

Output:Exception occured: InvalidAgeException:not valid
       rest of the code...

[end, ref: https://www.javatpoint.com/exception-handling-in-java]

Views: 63

程序设计基础总复习

程序设计基础总复习

时间地点:

以教务系统为准.

课程得分:

平时: 40%, 考试: 60%

考核方式:

闭卷.

不允许电子设备和纸质材料.

选择题 30个
填空题 10个
判断题 10个
分析题 1个
编程题 2个

使用语言:

标准C语言

编程基础

image-20200629230244144

编程语言分类

  • 机器语言 0101
  • 汇编语言 指令: ADD MOV
  • 高级语言 C/C++, Python, Java

高级语言代码的旅程

image-20200629232948722

常用关键字

image-20200629233218677

sizeof关键字

sizeof是C语言中保留关键字,也是单目运算符。常见的使用方式:

int a=10;
int arr[] = {1, 2, 3};
char str[] = "hello";
int len_a = sizeof(a);
int len_arr = sizeof(arr);
int len_str = sizeof(str)

二进制计算

二进制整数最终都是以补码形式出现的.

•正数的补码与原码、反码是一样的.

•负数的补码是反码加 1 的结果.

这种设计, 使得符号位也可以参与运算, 使加法器也能实现减法运算. 在计算机里的任何计算最终都可以变成加法运算, 加法运算是高频率运算, 使用同一个运算器(加法器), 可以减少中间变量存储的开销, 降低CPU内部的设计复杂度, 使计算机内部结构更精简, 计算更高效.

举例使用二进制计算 2 - 3

为了方便演示, 假设存储单元长度为8位

有符号的情况下, 第一位为符号位, 正数符号位为0, 负数符号位为1

计算 2 - 3, 其实就是计算 (+2) + (-3)

+2 原码 (0)000 0010, 
+2 补码 (0)000 0010

-3 原码 (1)000 0011, 
-3 补码 (1)111 1101

因此当计算机处理 2 - 3的时候, 其实是将 +2 和 -3 的二进制补码相加

   0000 0010
 + 1111 1101 
 -----------
   1111 1111

最终结果为 1111 1111(补码), 对应的数值是 -1

不同进制的比较

image-20200629233813798

非负数在不同进制下的表示

image-20200629233819885

变量定义

不被初始化的局部变量,其值为随机数

变量作用域

#include <stdio.h>

int a = 1;
int main (){
    {
        printf("%d", a); // ?
        int a = 2;
        printf("%d", a); // ?
    }
    printf("%d", a);     // ?
}

合法标识符

C语言标识符是指用来标识某个实体的一个符号,在不同的应用环境下有不同的含义,标识符由字母(A-Z,a-z)、数字(0-9)、下划线“_”组成,并且首字符不能是数字,但可以是字母或者下划线($符号也可以)。例如,正确的标识符:abc,a1,prog_to。

另外标识符不可以是关键字.

基本数据类型

  • int

    整数,在目前绝大多数机器上占4个字节

  • float

    单精度浮点数,4个字节

  • double

    双精度浮点数,8个字节

  • char

    字符,1个字节

    表示256个ASCII字符,或0~255的整数

1 == sizeof(char) <= sizeof(short) <= sizeof(int) <= sizeof(long) <= sizeof(long long).

取值范围

Data Type Min Value Max Value
short int 2^15 2^1
unsigned short int 0 2^15-1
unsigned char 0 2^8-1

数据类型修饰符

  • short

    short int,简写为short

    短整数,2 个字节

  • long

    • long int,简写为long

    长整数,至少4个字节

    • long double,长双精度(高精度)

    浮点数,至少8字节

  • unsigned | signed

    用来修饰char | int | short | long

    unsigned表示无符号整数(包括正整数和0)

    signed表示有符号, 因为是默认情况一般省略

字符类型

通过关键字 char 来定义, 如

char c;

常用转义字符表

image-20200629234803070

  • 8进制转义字符

    - octal escape sequence

    8进制数字字符需在前面使用\进行转义

  • 16进制转义字符

    - hexadecimal escape sequence

    16进制数字字符需在前面使用\x进行转义

image-20200701010132169

编程思维

  • 变量的定义和初始化
  • 变量及其作用域
  • 基本数据类型
    • 前缀[unsigned/signed]
    • char 固定1字节
    • short [int] 一般2字节
    • int 一般4字节
    • long [int] 一般4字节
    • long long [int] 一般8字节
    • float 一般4字节
    • double 一般8字节
    • long double 一般16字节
  • 各类运算符和表达式:
    • 算术 + - * / %
    • 显示类型转换
    • 隐式类型转换
    • 赋值
    • 自增自减
    • 位操作
    • 关系运算
  • 结构化程序设计
  • 逻辑运算符和表达式: && || !
  • 运算符的优先级
  • 分支结构
    • if, switch的使用
  • 循环结构 for, while, do while的使用

变量

变量的四个属性

int a = 1;
  • 变量名字: a

  • 变量类型: int (4字节)

  • 变量值: 1

  • 存储单元地址: 6487620

image-20200630011538138

注: 每一个变量要有一个与其它变量不相同的合法名字.

该名字的第一个字符必须是字母或下划线, 其后的字符只能是字母、数字和下划线, 且不得与 C 语言系统所保留的关键字相同.

常量

常量(Constant) 在程序中不能改变其值的量

包括:

  • 整型常量

    如: 0, 67, -2, 123L, 123u, 022, 0x12

    默认为int

    85         /* 十进制 */
    0213       /* 八进制 */
    0x4b       /* 十六进制 */
    30         /* 整数 */
    30u        /* 无符号整数 */
    30l        /* 长整数 */
    30ul       /* 无符号长整数 */
    212         /* 合法的 */
    215u        /* 合法的 */
    0xFeeL      /* 合法的 */
    078         /* 非法的八进制没有8*/
  • 实型常量

    2.3, 1.2e-5, 2.73F, 2.73L

    默认为double

    3.14159    /* 合法的 */
    314159E-5L /* 合法的 */
    510E       /* 非法:不完整指数 */
    210f       /* 非法:没小数或指数 */
    .e55       /* 非法:缺基数(整数或分数) */
  • 字符型常量

    'z', '3', '$', '\n', '\x41'

    用'\'开头的字符为转义字符, 连同之后的字符一起代表1个字符

    '\\'      \
    '\''      '
    '\"'      "
    '\?'      ?
    '\a'      警报铃声
    '\b'      退格键
    '\f'      换页符
    '\n'      换行符
    '\r'      回车
    '\t'      水平制表符
    '\v'      垂直制表符
    '\ooo'      ooo 代表八进制数
    '\xhh'      hh 代表十六进制数
  • 字符串常量

    "123", "UKM", "1", "5a"

    // 3种写法相同
    char c1[] = "hello, dear";
    char c2[] = "hello, \
    dear";
    char c3[] = "hello, " "d" "ear";
  • 枚举型常量 enum

    枚举是 C 语言中的一种基本数据类型,它可以让数据更简洁,更易读。

    如果不指定, 第一个枚举成员的默认值为整型的 0,后续枚举成员的值在前一个成员上加 1

    enum DAY{
    MON=1, TUE, WED, THU, FRI, SAT, SUN};

定义常量

在 C 中,有两种简单的定义常量的方式:

  1. 使用 #define 预处理器

    #define LENGTH 10
    #define WIDTH  5
    #define NEWLINE
  2. 使用 const 关键字。

      const int  LENGTH = 10;
      const int  WIDTH  = 5;
      const char NEWLINE = '\n';

运算符优先级

表达式有多个运算符时, 需保证计算过程无二义性.

  • 通过规定运算符的 “优先级” 和 “结合性” 来保证运算结果的唯一性.
  • 对表达式求值, 应先按运算符优先级的高低次序执行.
  • 运算符优先级规律:! > 算术运算符 > 关系运算符 > && > || > 赋值运算符
  • 如果操作数两侧的运算符优先级相同, 则按运算符的结合性处理(运算次序由结合方向所决定).
  • 对于复杂的运算, 建议使用括号明确表示优先级关系
#include <stdio.h>

int main()
{
    int a = 1, b = 2, c = 3;
    a + b * c;  // 1
    a + b - c;  // 2
}
优先级 运算符 名称或含义 使用形式 结合方向 说明
1 [] 数组下标 数组名[常量表达式] 左到右 --
1 () 圆括号 (表达式)/函数名(形参表) 左到右 --
1 . 成员选择(对象) 对象.成员名 左到右 --
1 -> 成员选择(指针) 对象指针->成员名 左到右 --
2 - 负号运算符 -表达式 右到左 单目运算符
2 ~ 按位取反运算符 ~表达式 右到左 单目运算符
2 ++ 自增运算符 ++变量名/变量名++ 右到左 单目运算符
2 -- 自减运算符 --变量名/变量名-- 右到左 单目运算符
2 ***** 取值运算符 *指针变量 右到左 单目运算符
2 & 取地址运算符 &变量名 右到左 单目运算符
2 ! 逻辑非运算符 !表达式 右到左 单目运算符
2 (类型) 强制类型转换 (数据类型)表达式 右到左 --
2 sizeof 长度运算符 sizeof(表达式) 右到左 --
3 / 除 表达式/表达式 左到右 双目运算符
3 ***** 乘 表达式*表达式 左到右 双目运算符
3 % 余数(取模) 整型表达式%整型表达式 左到右 双目运算符
4 + 加 表达式+表达式 左到右 双目运算符
4 - 减 表达式-表达式 左到右 双目运算符
5 << 左移 变量<<表达式 左到右 双目运算符
5 >> 右移 变量>>表达式 左到右 双目运算符
6 > 大于 表达式>表达式 左到右 双目运算符
6 >= 大于等于 表达式>=表达式 左到右 双目运算符
6 < 小于 表达式<表达式 左到右 双目运算符
6 <= 小于等于 表达式<=表达式 左到右 双目运算符
7 == 等于 表达式==表达式 左到右 双目运算符
7 != 不等于 表达式!= 表达式 左到右 双目运算符
8 & 按位与 表达式&表达式 左到右 双目运算符
9 ^ 按位异或 表达式^表达式 左到右 双目运算符
10 | 按位或 表达式|表达式 左到右 双目运算符
11 && 逻辑与 表达式&&表达式 左到右 双目运算符
12 || 逻辑或 表达式||表达式 左到右 双目运算符
13 ? : 条件运算符 表达式1?表达式2: 表达式3 右到左 三目运算符
14 = 赋值运算符 变量=表达式 右到左 --
14 /= 除后赋值 变量/=表达式 右到左 --
14 *= 乘后赋值 变量*=表达式 右到左 --
14 %= 取模后赋值 变量%=表达式 右到左 --
14 += 加后赋值 变量+=表达式 右到左 --
14 -= 减后赋值 变量-=表达式 右到左 --
14 <<= 左移后赋值 变量<<=表达式 右到左 --
14 >>= 右移后赋值 变量>>=表达式 右到左 --
14 &= 按位与后赋值 变量&=表达式 右到左 --
14 ^= 按位异或后赋值 变量^=表达式 右到左 --
14 |= 按位或后赋值 变量|=表达式 右到左 --
15 , 逗号运算符 表达式,表达式,… 左到右 --

表达式

C语言的表达式由运算符、常量、变量所组成, 以分号结尾.

#include <stdio.h>

int main()
{
    int a = 0;
    1;
    a;
    -a + 1;
    -a + 2.5 * 3;

    return 0;
}

表达式的最基本形式就是一个数据, 也称为操作数, 可以是任意类型的常量或变量.

将操作数与运算符结合, 可以构建一个新的表达式, 继而使用多个运算符连接多个操作数可以形成更为复杂的表达式.

条件表达式

条件操作符(? :)中的第一个操作数,逻辑非(!)、逻辑与(&&)、逻辑或(||)的操作数都是条件表达式。if、while、do while、以及for的第2个表达式都是条件表达式。

在C语言里, 条件表达式返回0时表示为假(0), 返回非0时表示为真(1).

printf("%d\n", 2 == 1 + 1);  // 1

复合赋值

image-20200702222837881

隐式类型转换

隐式类型转换可以发生在:运算、赋值、函数参数、函数返回值时, 具体是在

  • 运算时操作数之间类型不同时
  • 赋值时表达式返回类型和接受变量类型不同时
  • 实参类型和形参类型不同时
  • 函数实际返回类型和定义返回类型不同时

转换后的类型范围更大, 精度更高.

image-20200702223036993

1 / 5;     // int
1 / 5.0;   // double 0.2

举例

int ival; double dval;
ival >= dval; // int -> double

整形提升

  • 算术转换通常的是做整型提升

    - integral promotion

int ival = 3.14; // 3.14  -> int 
int *ip = 0;     // 0 -> NULL ptr

流程控制

C语言的流程控制结构主要分为:顺序结构,选择(分支)结构,循环结构.

其中选择结构和循环结构可以互相任意嵌套

img

分支

if语句

// 语句可以是单独的一条语句
// 也可以是{}包围的一条复合语句
if (条件表达式) 
    语句;

// else 总是向上匹配距离最近的 if
if (条件表达式) 
    语句1;
else
    语句2;

// 三元运算符可以替换简单的 if else
int a = 3, b = 5, max;
if (a > b) max = a; else max = b;
// 等同于
max = a > b ? a : b;

// 多分支, else if 可以多个
if (条件表达式) 
    语句;
else if (条件表达式)
    语句;
else if (条件表达式)
    语句;
else 
    语句;

注意条件判断是有顺序的, 如果命中了一个判断条件, 则会跳过其他的判断.

举例: foo bar baz 问题

这是一个国外非常常见的编程面试题: 遍历打印数字1至数字50, 遇到能被3整除的打印'foo'、遇到能被5整除的打印'bar'、遇到即能被3整除也能被5整除的打印'baz'。

#include <stdio.h>

int main()
{
  int i;
  for (i = 1; i <= 50; i++)
  {
    if (i % 3 == 0 && i % 5 == 0)
      puts("baz");
    else if (i % 3 == 0)
      puts("foo");
    else if (i % 5 == 0)
      puts("bar");
    else
      printf("%d\n", i);
  }
  return 0;
}

输出

1
2
foo
4
bar
foo
7
8
foo
bar
11
foo
13
14
baz
16

switch语句

switch语句 只能对 返回整形(枚举返回的也是整形)的条件表达式 进行 相等判断

image-20200703105638017
image-20200703105702606

为了避免出错, 除了一些特殊情况外, 每一个case都应该用break结束

循环

for循环语句

image-20200703110329639

break VS continue

  • 都在循环体内出现

  • break: 无条件退出该层循环,循环控制变量不再起作用

  • continue: 并不退出该层循环,只是不再执行循环体中位于其后的语句,循环控制变量仍然起作用。

while 当循环

先检测 表达式 的值, 如果为 非0 则执行循环体中的 语句,如果为 0 则跳出循环过程

语法:

while (表达式)
{
    语句
};

do while 直到循环

先执行do里面的语句, 然后检查条件表达式的结果, 如果为 非0 继续循环,如果为 0 则跳出循环过程, 直到型循环可以保证至少执行语句一次.

语法:

do
{
    语句
} while (表达式);

最后的分号别忘了添加.

枚举算法

有序地去尝试每一种可能

所有的可能都一一验证.

把重复的工作交给计算机去完成.

// 伪代码
for (ans in allCandidates)
{
    if (ans is answer)
    {
        output ans;
    }
}

等式填数

在两个□内填入相同的数字, 使得以下等式成立:

_3 X 6528 = 3_ X 8256

如果有多个答案, 要求从小到大列出所有满足条件的等式. 例如:

43 X 6528 = 34 X 8256

过滤法(筛法)

在循环里面添加判断, 例如找出1-100之间的所有合数, 就可以通过筛去所有素数得到

#include <stdio.h>
#include <math.h>

int main()
{
  int nums[101] = {0};

  for (int i = 2; i < 101; i++)
  {
    int divisor = 2;
    while (divisor <= sqrt(i))
    {
      if (i % divisor == 0)
      {
        nums[i] = 1;
        break;
      }
      divisor++;
    }
  }

  for (int i = 2; i < 101; i++)
    printf("%d\t是%s\n", i, (nums[i] ? "合数" : "质数"));

  return 0;
}

函数和递归

  • 函数的定义: 名字, 形参列表, 返回值类型
  • 形参与实参概念和使用
  • 值传递和引用传递
  • 递归函数的特点
  • 熟记经典问题及其递归解法
    • 斐波那契序列, 汉诺塔, 8皇后…

求和函数定义示例

int sum (int x, int y)
{
    int z;
    z = x + y;
    return z;
}

函数首部 即"{}"以上的一行说明, 包括: 返回值类型、函数名、形式参数列表;

函数体 则是从"{"开始, 到"}"结束的代码块, 函数体又分为声明部分和语句部分

函数参数传递

  • 声明和定义时: 形参
  • 调用时: 实参
  • 形参是在函数被调用时才分配形参的存储单元.
  • 实参可以是常量、变量或表达式.
  • 实参类型必须与形参相符.
#include <stdio.h>

void AddOne(int a)  // a 形参
{
    a++;
    printf("a=%d", a);
}

int main()
{
    int x = 1;
    AddOne(x);     // x 实参
    printf("x=%d", x);
}

image-20200703111715423

数组作为参数

数组作为函数参数时,在函数内对数组名进行sizeof运算的结果总为4(目标编译平台是32位时)
这是因为,函数中的指针传递本质上也是属于值传递(指针变量的地址), 编译器并不会检查数组的长度. – 导致在函数内部数组退化成指针.

对编译器来说下面的三个定义并没有什么区别:

void Test( char array[20]);
void Test( char array[]);
void Test( char* const array);

这也是为什么C语言的很多函数在需要数组作为参数时需要同时传入数组名和数组大小作为形参.

void putValues(int arr[], int size);

函数返回值

在绝大多数情况下,函数定义的返回值类型与 return 语句中返回值的数据类型必须是一致的.

函数定义的返回值类型, 与return语句中返回值的数据类型不一致时, 以函数定义的返回值类型为准.

编译器先尝试将return语句中的返回值隐式转换为函数定义的返回值类型, 然后再返回给主调对象, 如果不能完成转换, 编译器将会报错.

#include <stdio.h>

int AddTwo(short a, short b)
{
    return a + b;   // short -> int
}

int main()
{
    short a = 2, b = 3;
    printf("x=%d", AddTwo(a, b));
}

void类型

void 被翻译为"无类型",相应的void * 为"无类型指针"。常用在程序编写中对定义函数的参数类型、返回值、函数中指针类型进行声明。

void的作用

  1. 当函数不需要返回值值时,必须使用void限定,这就是我们所说的第一种情况。例如:void func(int a,char *b)

  2. 当函数不允许接受参数时,必须使用void限定,这就是我们所说的第二种情况。例如:int func(void)

  3. 当没有定义函数返回值时, C语言默认返回值类型是int, 而C++是void

递归调用

  • 递归就是函数直接或者间接调用自身
  • 递归利用了函数调用栈, 如果调用层级过深会导致堆栈溢出错误 - Stack Overflow
  • 递归必须有出口, 如果没有出口就会出现无限循环调用, 同样会导致堆栈溢出.
  • 递归函数必须带有形参, 递归过程中的每一次调用必须调整函数的参数使问题范围越缩越小, 小到可以直接解决为止(到达出口).
  • 递归函数根据情况可以有返回值, 也可以没有返回值
// 返回n的阶乘 - 递归的方式
// n > 1 
long double f(const int n)
{
  if (n == 1)
    return 1;
  return f(n - 1) * n;
}

递归过程

image-20200426102528279

递归是自顶向下解决问题, 将大问题化解成小问题, 小问题解决了, 反过来大问题就解决了, 和迭代相比递归的代码量一般会更少, 逻辑更清晰, 符合人类思维方式, 可读性更好.

数组

  • 数组的定义和初始化
  • 数组下标的使用(从0开始)
  • 一维数组、二维数组
  • 数组作为函数形参
  • 常用数组元素的排序方法及其代码
  • 已排序数组元素的折半查找
  • 指针, 地址

何为数组

数组 (array) 是一种数据格式, 能够存储多个同类型的值, 数组在定义时就要确定空间大小, 里面的元素在内存上是连续的.

  1. 可以将数组中的每个元素看做一个简单的变量.
  2. 数组是具有一定顺序关系的若干相同类型变量的集合体, 组成数组的变量称为该数组的元素.
  3. 数组还被称为复合类型, 时因为它是使用其他类型来创建的.
  4. 数组的元素在逻辑上是连续, 在物理上也是连续的, 通过下标即可快速计算出指定元素的位置.

一维数组的顺序存储

数组元素在内存中顺次存放, 它们的地址时连续的:

image-20200630145804219

下标越界检查?

不存在的. C语言编译器不会帮你检查使用的下标是否有效.

例如, 如果将一个值赋给不存在的元素 a[10], 编译器并不会指出错误. 但是程序运行后, 这种赋值可能会引发问题, 它可能破坏数据或代码, 也可能导致程序异常终止.

所以必须确保程序只使用有效的下标.

image-20200630150500138

数组初始化

  • 在声明数组时对数组元素赋以初值. 例如:

    int a[10]={1, 2, 3, 4, 5, 6, 7, 8, 9,10};
  • 可以只给一部分元素赋初值.

    int a[10]={1, 3, 5, 7}; 
    int a[10]={0}; 
  • 在对全部数组元素赋初值时, 可以不指定数组长度.

    int a[]={1, 2, 3, 4, 5, 6, 7, 8, 9, 10}

    使用memset函数对数组初始化
    使用 memset 函数, 调用此库函数需要加入头文件 <memory.h>

用法: memset(数组名,初始化值,sizeof(数组名))

int arr[];
// 初始化成 0
memset(arr, 0, sizeof( arr ));
// 初始化成 -1
memset(arr, -1, sizeof( arr ));
// 注意, 这样不能初始化成 1
// 实际初始化成了 16843009
memset(arr, 1, sizeof( arr ));

image-20200703114215963

数组下标使用

&a[x] = a + x * sizeof(a[0]);

二维数组

二维数组本质上也是一维数组, 数组元素在内存中顺次存放, 它们的地址是连续的. 例如:

image-20200702001952774

二维数组初始化

二维数组的初始化: 在定义数组的同时赋给初值.

// 将所有数据写在一个{}内, 按顺序赋值
int a[3][4]={1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12};

// 分行给二维数组赋初值, 例如:
int a[3][4] ={
    {1,  2,  3,  4},
    {5,  6,  7,  8},
    {9, 10, 11, 12}
};

// 可以对部分元素赋初值, 例如:
int a[3][4]={
    {1}, 
    {0, 6}, 
    {0, 0, 11}
}; 

// 以上写法等同于
int a[3][4]={
    {1, 0,  0, 0}, 
    {0, 6,  0, 0}, 
    {0, 0, 11, 0}
};

// 列出全部初始值时, 第1维下标个数可以省略, 例如:
int a[][4]={1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12};
// 再如:
int a[][4] ={
    {1, 2, 3, 4}, 
    {5, 6, 7, 8}, 
    {9, 10, 11, 12}
}; 

// 但是这样是错误的
int a[3][] ={
    {1, 2, 3, 4},
    {5, 6, 7, 8},
    {9, 10, 11, 12}
}; 
  • 数组定义的时候必须指定数据类型, 好确定每个元素需要开辟多少空间.
  • 数组空间大小定义时就已经确定, 不能更改.
  • 多维数组可以视为特殊的一维数组, 只不过其元素也是数组.
  • 因为多维数组的其余维是用来确定每次开辟多少空间, 而第一维是用来确定开辟空间的倍数.
  • 如果定义时不指定其余维的长度将导致二义性, 即编译器无法确定给每次开辟多少空间, 造成编译错误.
  • 所以多维数组定义时, 除了第一维长度可以省略, 其余维度必须给出具体长度.

二维数组下标

// 二维数组下标与元素寻址
&a[x][y] == a + x*sizeof(a[0]) + y*sizeof(a[0][0])

冒泡排序

  for (int i = 0;i < SIZE-1;i++)
  {
    for (int j = 0;j < SIZE-i-1;j++)
    {
      if (arr[j] > arr[j + 1])
      {
        int temp = arr[j];
        arr[j] = arr[j + 1];
        arr[j + 1] = temp;
      }
    }
  }

基于数组的排序方法非常多, 例如:

  • 冒泡排序
  • 快速排序
  • 堆排序
  • 桶排序

字符数组

数组元素在内存中顺次存放, 它们的地址是连续的.字符数组中的每个元素在内存中占用一个字节的存储单元, 用于存取一个字符.

image-20200702010455008

空终止字符串

  • 也叫 NTBS - NULL Terminated Byte String
  • C语言中没有字符串数据类型, 于是将字符串中的字符逐个存放到数组元素中.
  • 字符串是一个独立的概念, 其以 '\0' 字符结尾, 字符串的本质还是字符数组.
  • 字符串常量用"xxx"表示

比如字符数组 {'\x63', '\x61', '\x74', '\0'} 是 ASCII 编码的字符串 "cat" 的 NTBS 。

用字符串来初始化字符数组

// 数组大小要考虑字符串末尾的空字符'\0'
char c[12] = {"hello world"};
// 花括号可以省略
char c[12] = "hello world";
// 数组大小可以省略
char c[] = "hello world";
// 虽然可以通过编译, 但避免这样使用
char *c = "hello world";

image-20200702011032282

字符表示ASCII

*注意, ASCII是American Standard Code for Information Interchange缩写, 而不是ASCⅡ(罗马数字2), 有很多人在这个地方产生误解.

ASCII (美国信息交换标准代码) 是基于拉丁字母的一套电脑编码系统, 主要用于显示现代英语和其他西欧语言.

ASCII包含三个部分内容:

img

  • "控制码“ 0~32: 规定了特殊的用途, 一旦终端、打印机遇上这些字符, 就要做一些约定的动作.

  • "标准字符" 33~127: 空格、标点符号、数字、大小写字母.

  • "扩展字符“ 128~255: 表示新的字母、符号, 还有画表格用到的横线、竖线、交叉等形状.

但是ASCII的扩展十分有限, 然而想要表示譬如中文这样的文字显然是不太够用的。于是,计算机工程师们给自己国家的语言创建了对应的字符集(Charset)和字符编码(Character Encoding)。

如果要表示汉字, 可以使用 GB编码(GB2312,GBK等可以表示简体中文),BIG5编码(表示繁体中文), UNICODE编码(也叫万国码, 包含了 150 种语言的 14 万个不同的字符).

以GB2312为例, 即《信息交换用汉字编码字符集》

两个大于 127 的字符(unsigned char)连在一起, 表示一个汉字. 这样, 双字节可以组合出约 7000 多个简体汉字 (常用的汉字都在这里面了).

image-20200702012054920

我们常常会看到乱码, 乱码是怎么产生的呢?

`手持两把锟斤拷,

口中疾呼烫烫烫。

脚踏千朵屯屯屯,

笑看万物锘锘锘`

锟斤拷:

UTF8编码的文本用<code>GBK格式解码时一些无法被字符集识别的字符会变成"\xef\xbf\xbd\xef\xbf\xbd", 由于GBK编码是2个字符表示一个汉字, 结果就成了"锟斤拷"

烫烫烫:

Visual Studio 的Debug模式用'0xCC'表示未初始化的内存, 其中'0xCC'在MBCS字符集中表示为"烫"

常用字符处理函数

Defined in header <string.h>

  • strlen

    returns the length of a given string

    strlen("HELLO WORLD");  //11
  • strcpy

    char src[] = "cpycpy";
    char des[strlen(src) + 1];
    strcpy(des, src);
  • strcmp

    // 使用字典序比较两个字符串
    strcmp("abc", "def"); // -1
    strcmp("aaa", "aaa"); // 0
    strcmp("acb", "abc"); // 1
  • strstr

    strstr("Hi, delucia, bye~", "delucia"); // delucia, bye~

结构体

结构体类型 struct

C语言允许使用结构体, 建立由不同数据类型组成的构造类型, 这种数据类型被称为结构体类型.

通过结构体类型, 我们可以将分散的信息集中起来表示一个实体类型.

如将学号、姓名、年龄、成绩等各项属性组织在一起, 用来表示某个学生.

image-20200702020753901

struct类型和C++的class类型基本用法相同. 主要区别是struct类型的成员默认可见性是public, 而class类型是private.

初始化

结构体类型可使用{}括起来的初值列表进行初始化

image-20200702021446810

结构体类型变量可以作为函数参数以及返回值使用.

但是要注意, 结构体类型做参数时, 如果需要永久改变实参变量的成员的值, 则需要传递指针

image-20200703100033468

typedef

typedef 声明, 可以给原有的数据类型定义 “别名”, 它的作用等同于数据类型名称, 通过合适的命名可以让数据类型表示的更直观.

image-20200702022618068

typedef unsigned long ULONG;
ULONG number = 1L;

字节对齐

结构体在内存中是连续存储的 为了让操作系统可以快速读取到每个成员的 数据, 需要进行字节对齐 目的是将不同的成员分段存储, 保证任何成 员的地址偏移都是2或4或8的倍数.

  • 在没指定对齐方式时, 按照最大成员类型的字节长度的倍数对齐
  • 如果指定对齐方式, 则按照指定的对齐值和最大成员类型的字节长度之间取最小值对齐

下面我们分别使用不同的编排方式定义结构体类型.

编排方式 1

struct test
{
    int a;      // 4 pad 4
    double b;   // 8
    char c;     // 1 pad 7
}

// 内存分成连续三段, 每段8字节
// |XXXX____|XXXXXXXX|X______|
// 一共24字节, 浪费11字节

编排方式 2

struct test 
{
    int a;      // 4
    char c;     // 1 pad 3
    double b;   // 8
}

// 内存分成连续三段, 每段8字节
// |XXXXX___|XXXXXXXX|
// 一共16字节, 浪费3字节

引用成员

struct NorthEastF4
{
  char name[20];
  char sex;
  unsigned long birthday;
  float height;
  float weight;
};

struct NorthEastF4 boys[4] =
{
  {"莱昂纳多·小沈阳", 'M', 19810507, 1.74, 60},
  {"约翰尼·刘小宝", 'M',   19810105, 1.62, 50},
  {"克里斯蒂安·刘能",'M',  19690226, 1.72, 75},
  {"尼古拉斯·赵四",'M',    19740320, 1.71, 65}
};

NorthEastF4 bao = boys[1]; //拷贝
NorthEastF4 *p_bao = &boys[1];//指向

// 赋值时字符串长度不匹配报出异常
// boys[1].name = "约翰尼·宋小宝";

strcpy(bao.name, "约翰尼·宋小宝"); 

// 访问结构体成员
bao.name;
p_bao->height;
(*p_bao).weight;

指针

image-20200703111805657

image-20200703111614526

文件

了解文件的

  • 打开
  • 关闭
  • 写入
  • 读出

文件与流

程序的处理结果或计算结果会随着程序运行结束而消失.

因此要将程序运行结束后仍需保存的数值和字符等数据, 保存在文件 (file) 上.

针对文件、键盘、显示器、打印机等外部设备的数据读写操作都是通过流 (stream) 进行的, 我们可以想象成流淌着字符的水管.

C语言中的文件读写步骤

  1. 打开文件

    无论对文件进行读还是写操作, 都需要先打开文件, 打开文件用 fopen 函数.

  2. 读写文件

    写就是将内存中的数据存到文件中去. 主要是 fscanf 和 fprintf 函数.

  3. 关闭文件

    当文件不再使用时, 需将其关闭. 关闭文件用 fclose 函数.

举例, 向 D:\c\f1.txt 中写入内容

image-20200702023113140

执行后, 打开f1.txt, 结果如下:

image-20200702023148607

格式输入输出

考试内容不涉及C++的写法

  • printf
  • scanf
  • gets
  • puts
  • getchar
  • getch

调试

给出一段代码, 可以很快指出代码存在的问题

常见编程问题

  • 判断质数: 1 3 5 7 9 11 13 17 19

  • 判断水仙花数: 153 370 371 401

  • 判断回文数: 101 111 121

  • foo-bar-baz

  • 猜大小游戏

  • 穷举法: 打印99乘法表

  • 穷举 + 过滤: 跳水成绩预测, 等式填数

  • 冒泡排序

  • 二分查找

  • 阶乘, 累加, 斐波那契序列等

其他注意事项

  • 考试都是C语言题目, 答题也使用C语言
  • 考试内容集中在3 - 9章
  • 这次不考或者很少涉及的内容有
    • 链表的具体实现
    • 使用指针动态分配和释放内存
    • 函数指针
    • 复杂递归算法实现
    • IO流和文件处理
  • 编程题需要手写编程
    • 唯手熟尔

Views: 323